
SpecEvo: Aligning Lightweight and Advanced LLMs to Reduce the Cost of Evolutionary Search
The SpecEvo framework redistributes evolutionary search: routine candidates refine inexpensive models, while stronger ones are brought in only at strategic checkpoints, guided by a history of successes and dead ends. In experiments across 176 tasks, this approach matched or outperformed costly alternatives while reducing API costs by 80%.
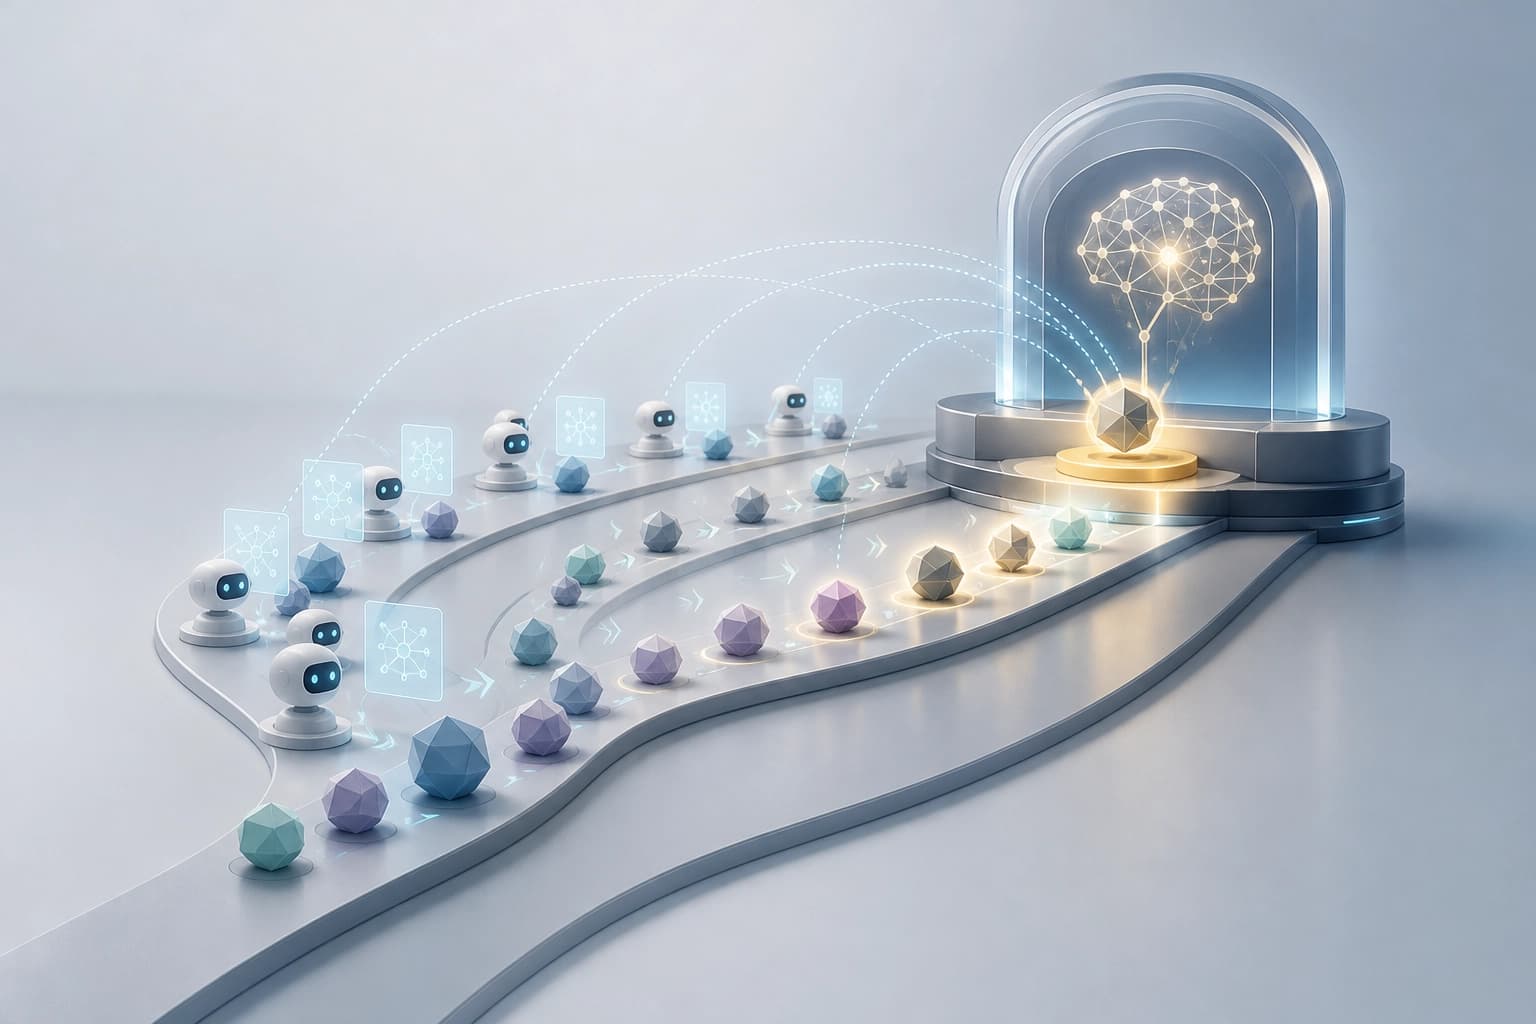
Task and purpose
SpecEvo (Speculative Evolution) is a multi-LLM framework for scientific discovery. It coordinates lightweight and frontier models to make the search for candidate programs less expensive. The arXiv paper arXiv:2610.28706 was submitted on October 20, 2026. The authors are Ha Minh Hieu, Tongyao Zhu, Do Xuan Long, and Min-Yen Kan.
Key characteristics:
- type: multi-LLM framework;
- purpose: scientific discovery and algorithmic search;
- approach: coordination of lightweight and frontier models;
- paper: arXiv:2610.28706, submitted on October 20, 2026;
- authors: Ha Minh Hieu, Tongyao Zhu, Do Xuan Long, Min-Yen Kan.
Practical criterion: consider the framework for tasks where API costs matter and candidate programs need to be found with infrequent checkpoints.
Architecture: roles of lightweight and frontier models
SpecEvo distributes work between lightweight and frontier models. Lightweight models perform the parallel Speculator and Advisor functions. A frontier model acts as the Navigator at infrequent checkpoints.
| Component | Model type | Function | Operating mode | | Speculators | lightweight | generate and refine candidate programs | in parallel | | Advisor | lightweight | summarizes successes, failures, and saturated search directions; turns them into persistent recommendations | summarizing accumulated information | | Navigator | frontier | examines the evolving population; intervenes through synthesis, targeted refinement, or a change in the search frame | infrequently, at checkpoints |
Practical criterion: assign routine search and evidence summarization to lightweight models, and bring in frontier models for strategic interventions.
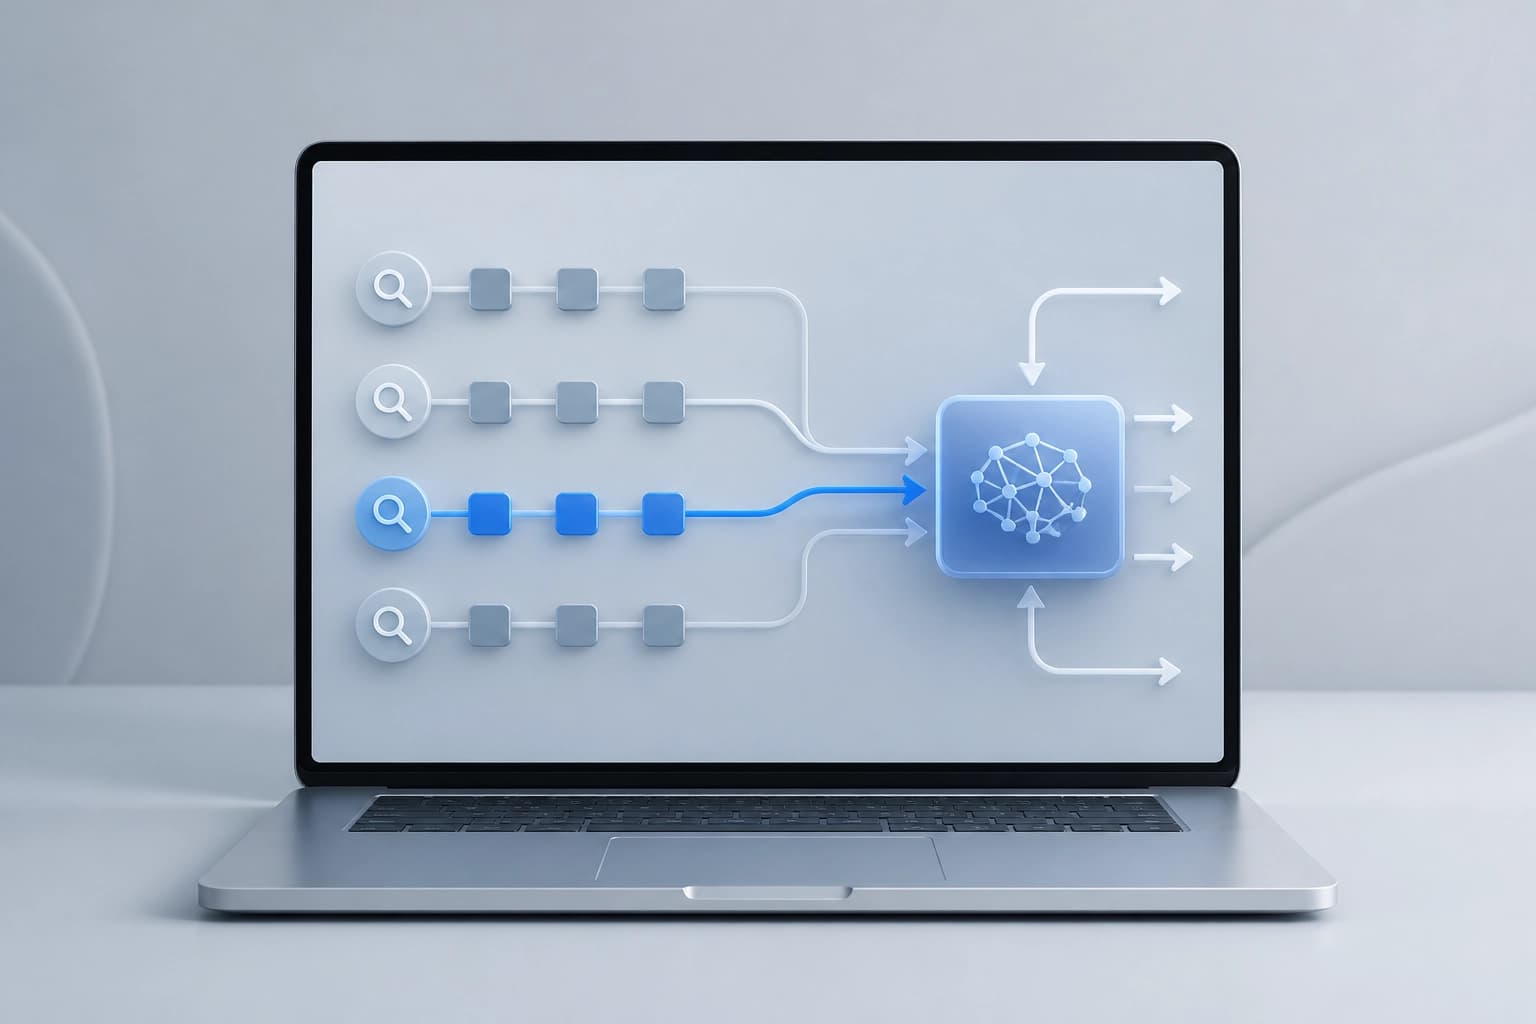
A “hypothesize first, consolidate later” workflow
In SpecEvo, the process is based on assigning routine search and evidence summarization to low-cost models. Frontier models are brought in for strategic interventions. Their benefits carry over to many subsequent low-cost evaluations.
Stages:
- Lightweight models conduct routine searches for candidate programs.
- The Advisor summarizes accumulated information about successes, failures, and saturated search directions.
- At an infrequent checkpoint, the Navigator examines the population and chooses an intervention.
- The intervention depends on search stagnation and may involve synthesis, targeted refinement, or a change in the search frame.
- Low-cost models continue evaluations using the persistent recommendations.
Practical criterion: this approach is suitable if the search allows for infrequent checkpoints and recommendations to accumulate between them.
Results and comparison with baselines
The authors tested SpecEvo on 176 tasks across four areas of scientific and algorithmic discovery. The framework matched or exceeded the results of baselines based on frontier models. At the same time, it reduced API costs by up to 80%. In equation discovery, the framework achieved up to 1.5× higher evaluation efficiency than cost-effective baselines. The framework outperformed the strongest baseline, CO-Bench, by 3.8%.
| Metric | Result | | Comparison with baselines based on frontier models | matched or exceeded | | Reduction in API costs | up to 80% | | Evaluation efficiency in equation discovery | up to 1.5× higher than cost-effective baselines | | Improvement over CO-Bench | 3.8% |
Practical selection criterion: compare search quality and API costs against baselines on your own tasks. The authors conclude that coordinating models based on the search trajectory is an effective approach to cost-effective scientific discovery.
Frequently asked questions
Related materials
All materials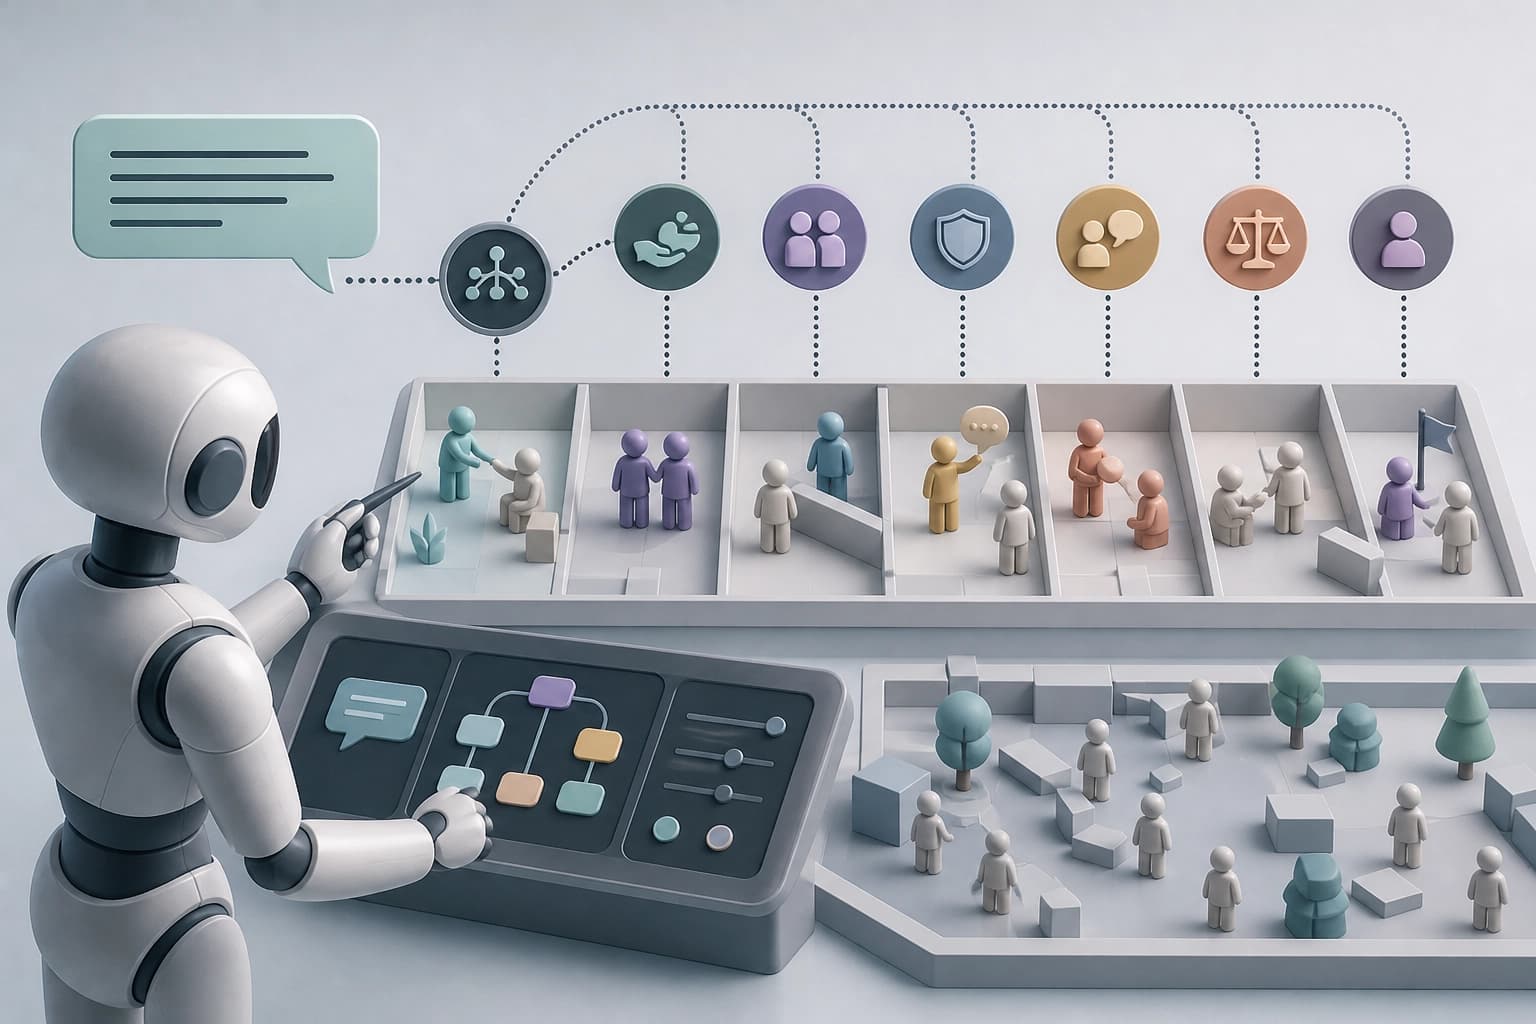
Fig: Controlled game interventions for testing the social behavior of AI agents
Fig takes a natural-language description of the behavior being targeted, divides it into variants, and strategically changes the rules of the game to elicit the desired actions from models. In valid scenarios across six social patterns, the interventions increased the average share of attempts at the target behavior by 10.9% compared with controls, and the authors propose treating multi-agent environments as a configurable testbed for reproducible evaluation.
21 November 2026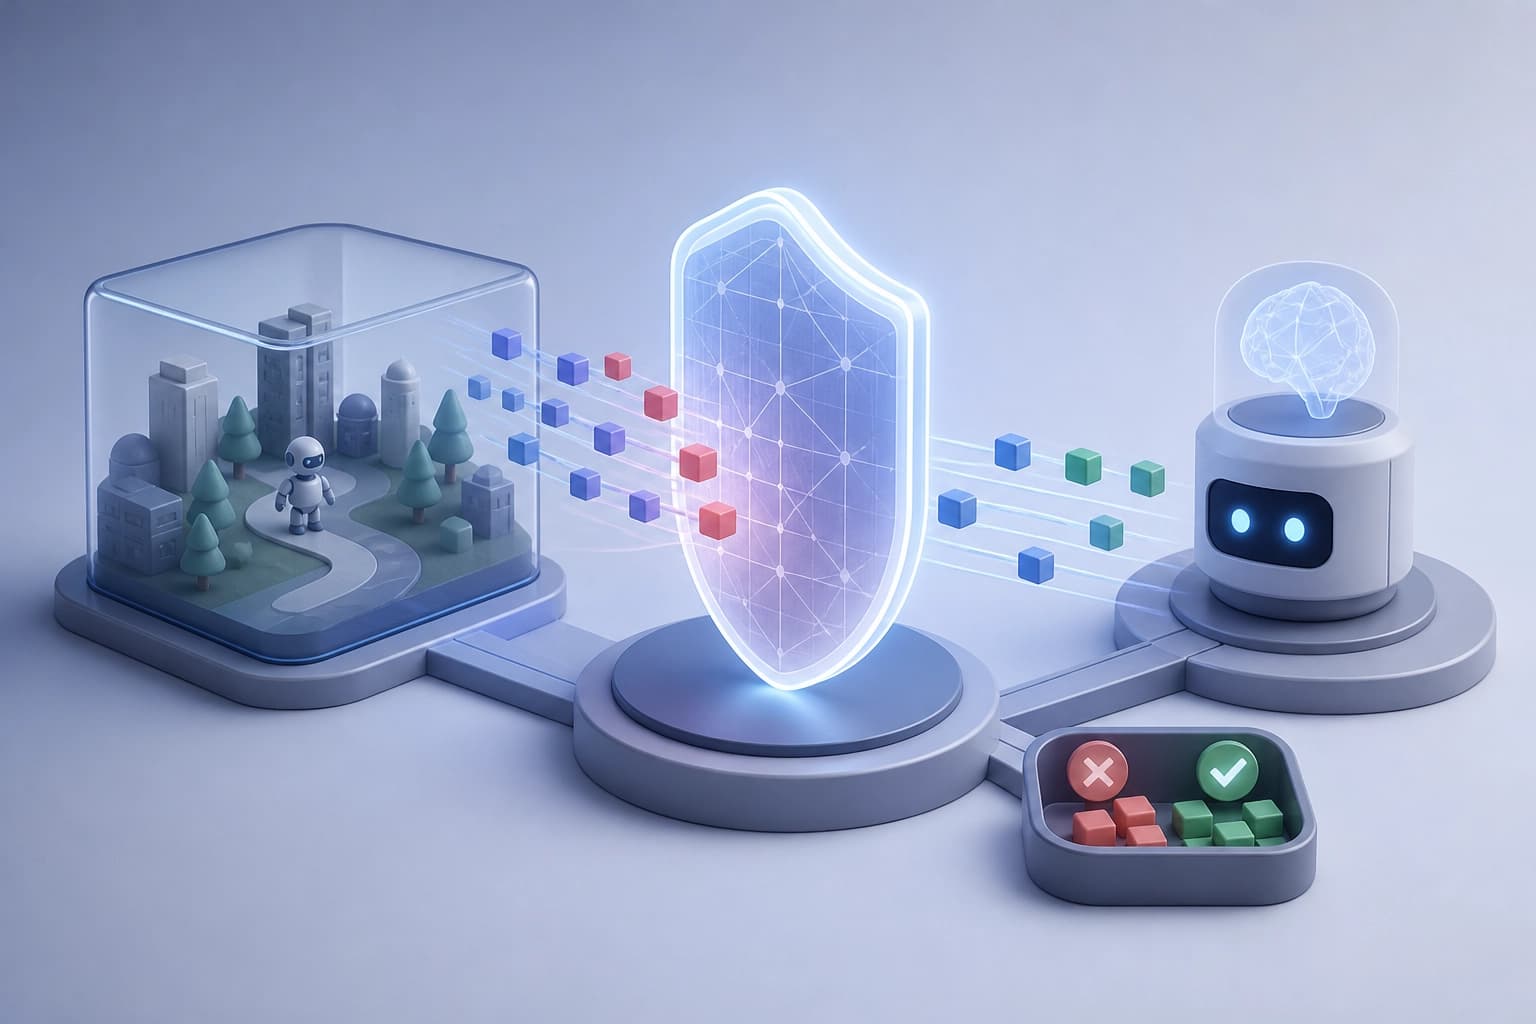
Prompt-Independent Testing of Agent Policies: Execution Environments, Test Suites, and a Trainable Filter
The work proposes a framework that turns execution environments into scenario suites for testing agent policies and enables iterative improvement of the defensive component. The trained filter reduces the rate of successful violations by 40–44% compared with relying only on instructions in the prompt, and is less likely to mistakenly reject safe requests.
20 November 2026
PerMIT: Long-Term Memory Integrity for LLM Agents and Machine-Verified Collective Trust
The authors propose the PerMIT architecture, which limits the flow of untrusted data from the environment into an agent’s sensitive actions through a finite memory interface. Two theorems verified in Lean 4 and the accumulation of community verdicts reduce the risk of poisoning without increasing the burden on individual users. In experiments on Trojan Hippo and τ²-bench, the approach recorded no successful injections with lightweight verifiers and improved the performance of new agents on held-out tasks.
20 November 2026