
PerMIT: Long-Term Memory Integrity for LLM Agents and Machine-Verified Collective Trust
The authors propose the PerMIT architecture, which limits the flow of untrusted data from the environment into an agent’s sensitive actions through a finite memory interface. Two theorems verified in Lean 4 and the accumulation of community verdicts reduce the risk of poisoning without increasing the burden on individual users. In experiments on Trojan Hippo and τ²-bench, the approach recorded no successful injections with lightweight verifiers and improved the performance of new agents on held-out tasks.
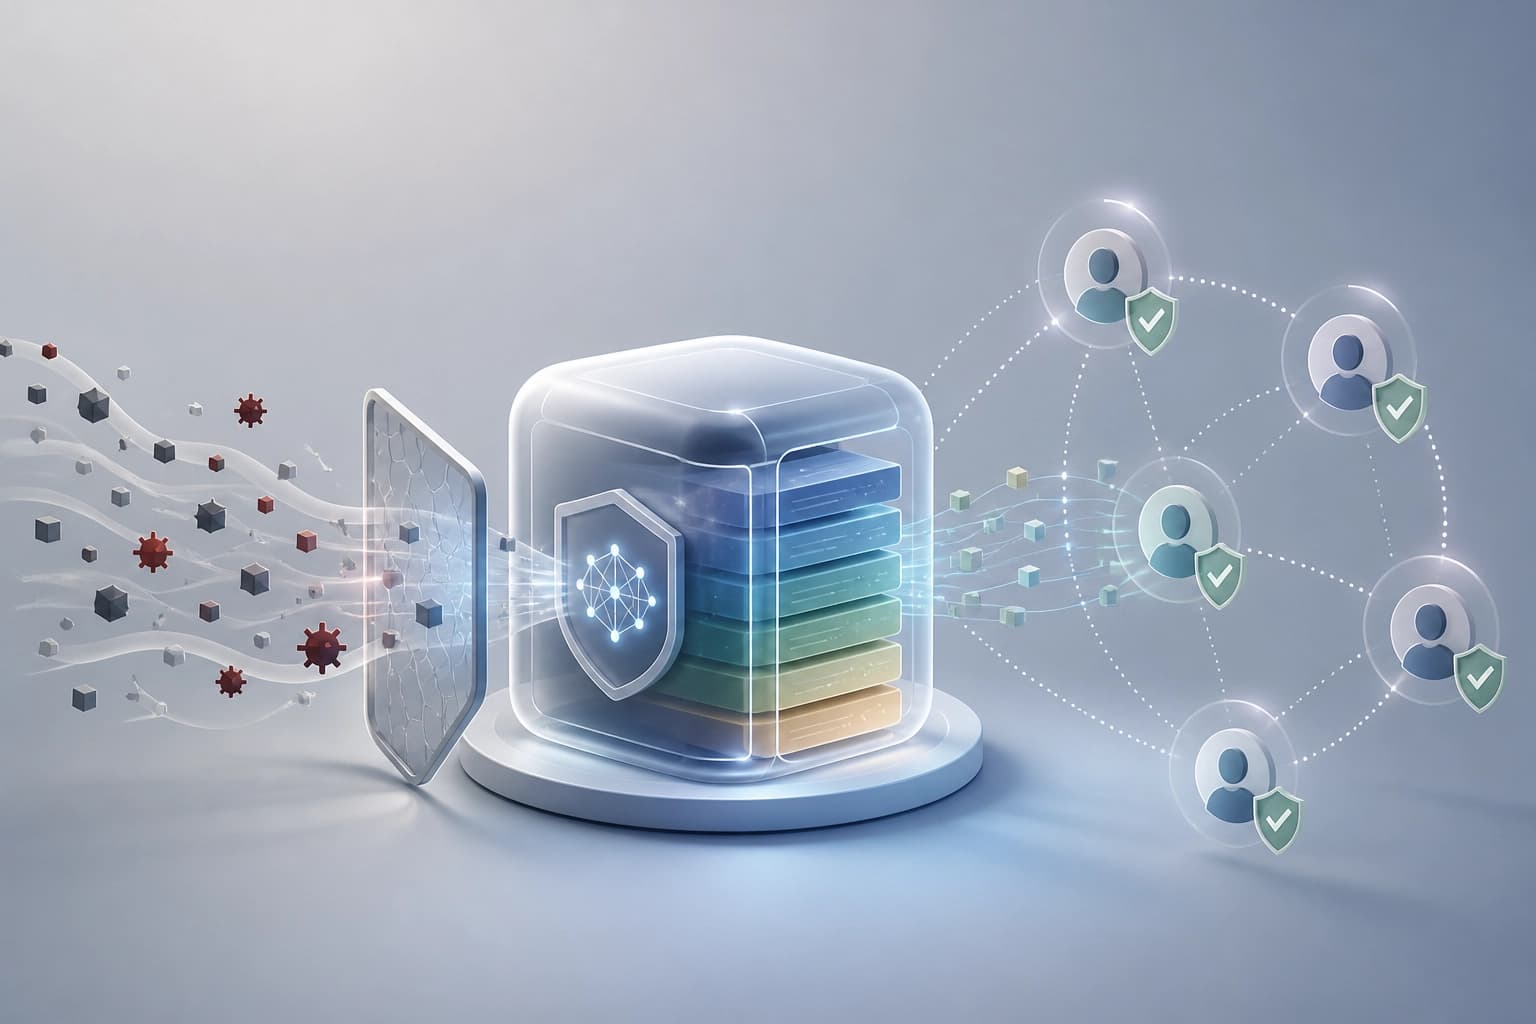
PerMIT — a memory architecture for LLM agents. A paper by Tanqiu Jiang, Min Bai, Sadat Shahriar, Wanyu Du, and Sandesh Swamy, submitted on October 20, 2026; arXiv:2610.28987.
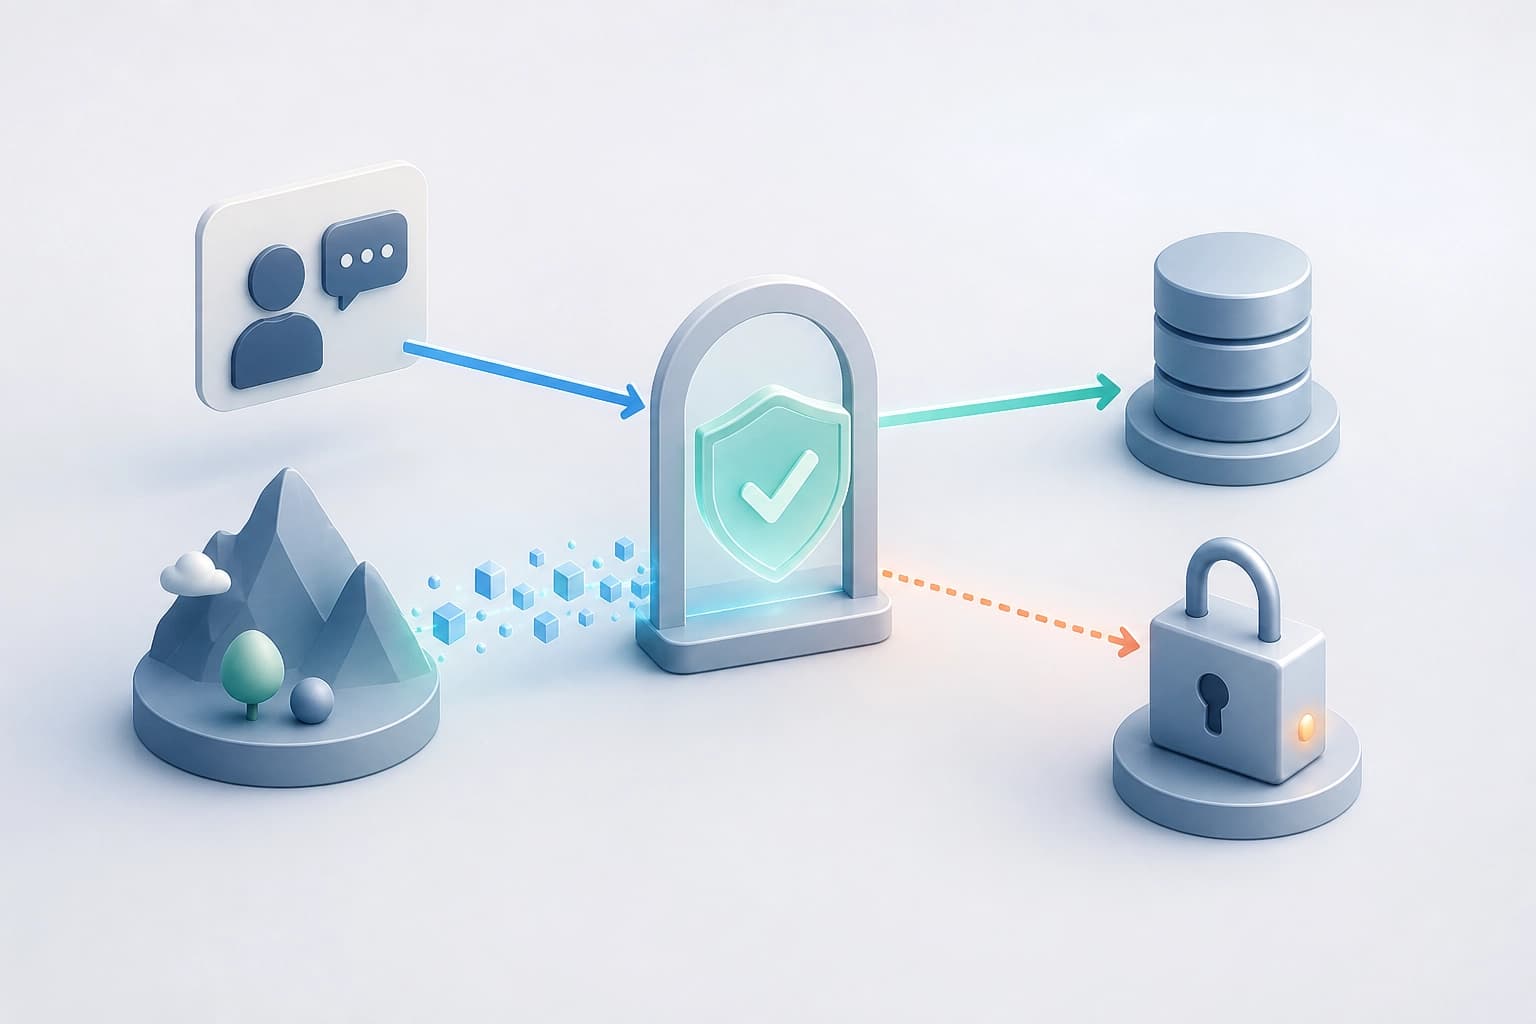
Trust Model
PerMIT establishes an explicit trust assumption. Only user-provided data and values confirmed at the gate are considered trusted. All values from the environment remain untrusted. The architecture regulates their transfer and use through a finite memory interface. The agent’s multi-step planning and tool selection are preserved.
Practical criterion: the approach is suitable if user input is considered trusted and environmental data is not.
Gate and Verifiable Decisions
The finite memory interface relies on a gate. The authors prove two integrity theorems for the interface. The theorems are machine-checked in Lean 4. Together, they guarantee two properties. Memory from the environment reaches a sensitive action only after being confirmed at the gate. The agent’s behavior changes only through what the gate exposes.
Within the threat model, every attack reduces to a single verifiable decision. In practice, the decision is made by a human, an LLM verifier, or both.
Practical criterion: the protection is applicable within a threat model where an attack reduces to a single verifiable decision.
Attestations and Collective Trust
Each attestation is a recorded verdict on exact content. Attestations accumulate across users. Items with sufficient support become community-verified without further review.
Under explicit assumptions, the authors prove a joint scaling property. They also validate it in a simulation. As the community grows, the risks of promoting poisoned data and mistakenly deleting benign knowledge decrease. The verification effort required of an individual user does not grow.
| What changes as the community grows | Direction |
|---|---|
| Risk of promoting poisoned data | Decreases |
| Risk of mistakenly deleting benign knowledge | Decreases |
| Verification effort required of an individual user | Does not grow |
Practical criterion: the collective layer is appropriate when verdicts are tied to exact content and accumulate across users.
Evaluations
On Trojan Hippo, PerMIT showed zero observed attack success. This result was achieved with self-checking and lightweight verifiers.
On τ²-bench, communities of up to 90 autonomous agents create shared knowledge bases using PerMIT. No direct memory injection was promoted. The resulting knowledge significantly improves new agents’ performance on held-out tasks.
Practical criterion — two results: no direct injections are promoted, and new agents improve on held-out tasks.
Frequently asked questions
Related materials
All materials
Composite multi-agent AI system with an evidence-based loop for proton therapy planning in head and neck tumors
The study describes a combination of a trained PPO policy that generates multiple plan options and LLM agents that conduct iterative dialogue, checking clinical metrics and constraints. Using data from 21 patients, the fine-tuned Qwen3-14B followed instructions more effectively and helped shift trade-offs in favor of priority goals. The practical takeaway is that automated DRL planning can be complemented by guided dialogue while preserving control over competing constraints.
20 November 2026
Computational Screening Instead of Empirical Trial and Error: New Approaches to Battery Materials
The article shows how computational databases, machine learning, and generative models narrow down promising compositions, while automated laboratories speed up their testing; the outcome still depends on synthesis and experiments, where predictions may differ from actual conductivity.
20 November 2026
The Evolution of Agent Benchmarks as Task Pools Scale: The Role of Evidence Selection and Sequential Races
This work explains why increasing the number of tasks can hinder the evolution of agent benchmarks: the problem is poor evidence selection, not data volume itself. The proposed Successive Scale Racing iteratively selects diverse task combinations and compares candidates at low cost; across three benchmarks, it increased the share of successful runs as the pool grew from 40 to 200, while baseline methods degraded, and reduced validation runs by about 60%.
19 November 2026