
Prompt-Independent Testing of Agent Policies: Execution Environments, Test Suites, and a Trainable Filter
The work proposes a framework that turns execution environments into scenario suites for testing agent policies and enables iterative improvement of the defensive component. The trained filter reduces the rate of successful violations by 40–44% compared with relying only on instructions in the prompt, and is less likely to mistakenly reject safe requests.
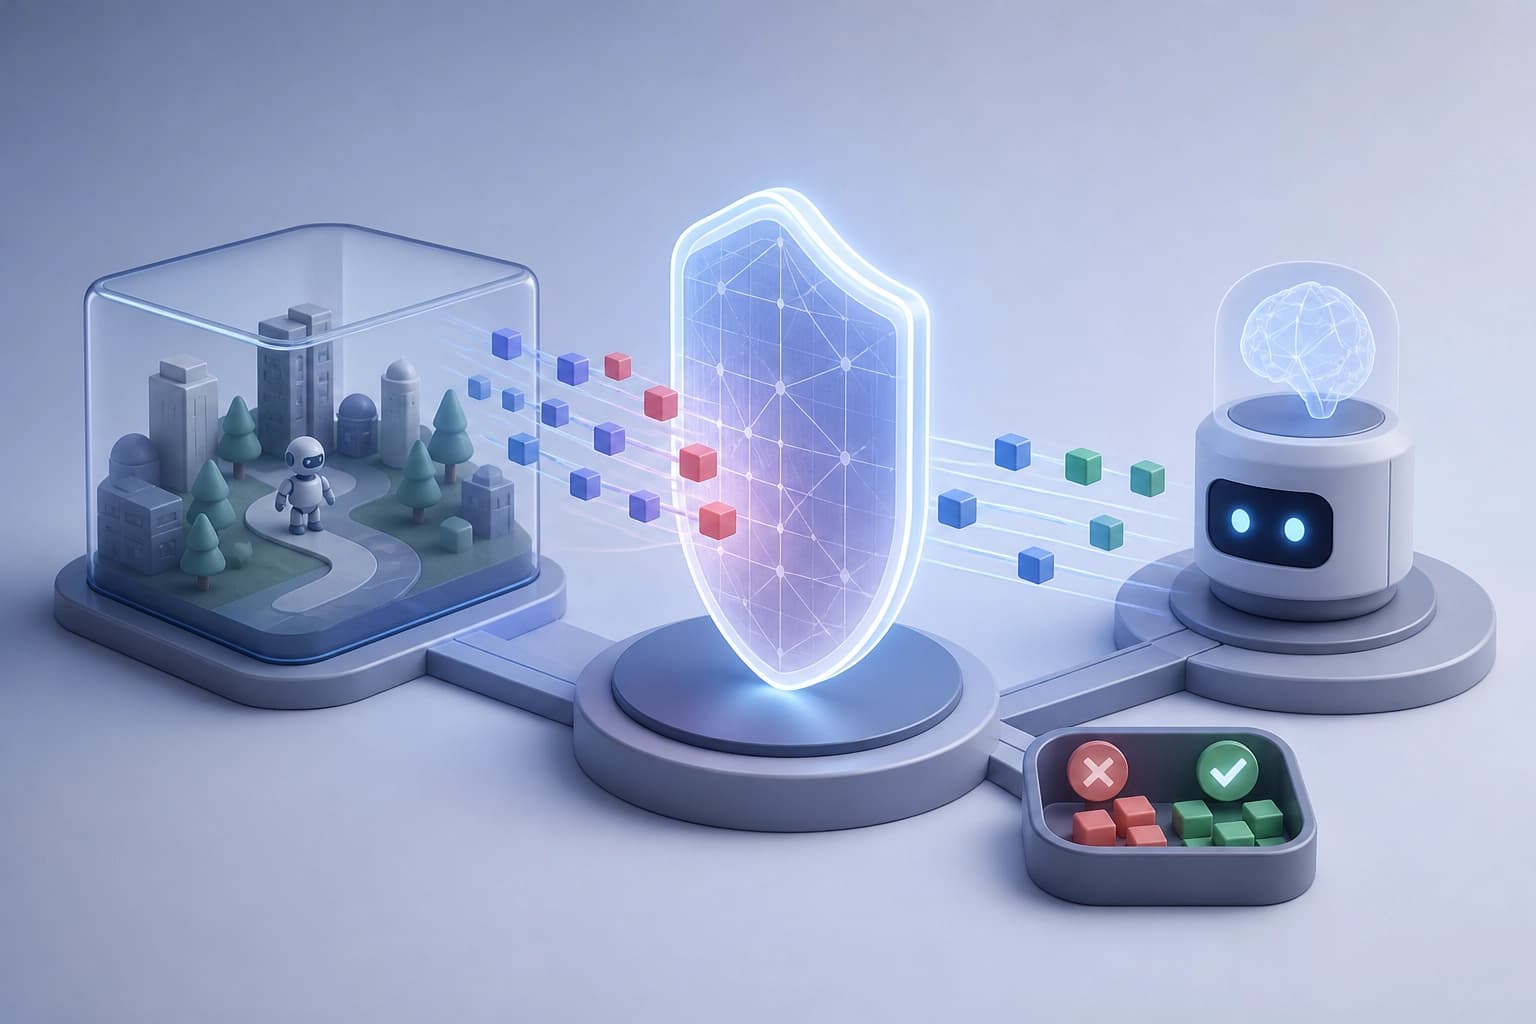
The Prompt Boundary: Why Instructions Aren't Enough
In individual agent deployments, policies define rules for tools, resources, and execution conditions. Including these rules in a prompt does not reliably prevent violations. A prompt provides text, but does not verify the actual call. In every violation, an allowed tool is used. This means the arguments, resources, and context need to be checked—not just the tool name.
Training a defensive mechanism requires examples of calls that comply with the policy and calls that violate it. Without such pairs, verification relies on the text of the rules rather than observable behavior.
Practical criterion: treat the prompt only as a carrier of rules. Build verification around call data and their results.
Execution Environment: Verification Against the Actual Call
AgentPolicyForge uses execution environments to create policy benchmarks and iteratively train defensive mechanisms. The environment executes tool calls and records the results. Compliance with the policy is determined from those results. This differs from reading the prompt: verification is based on actual execution.
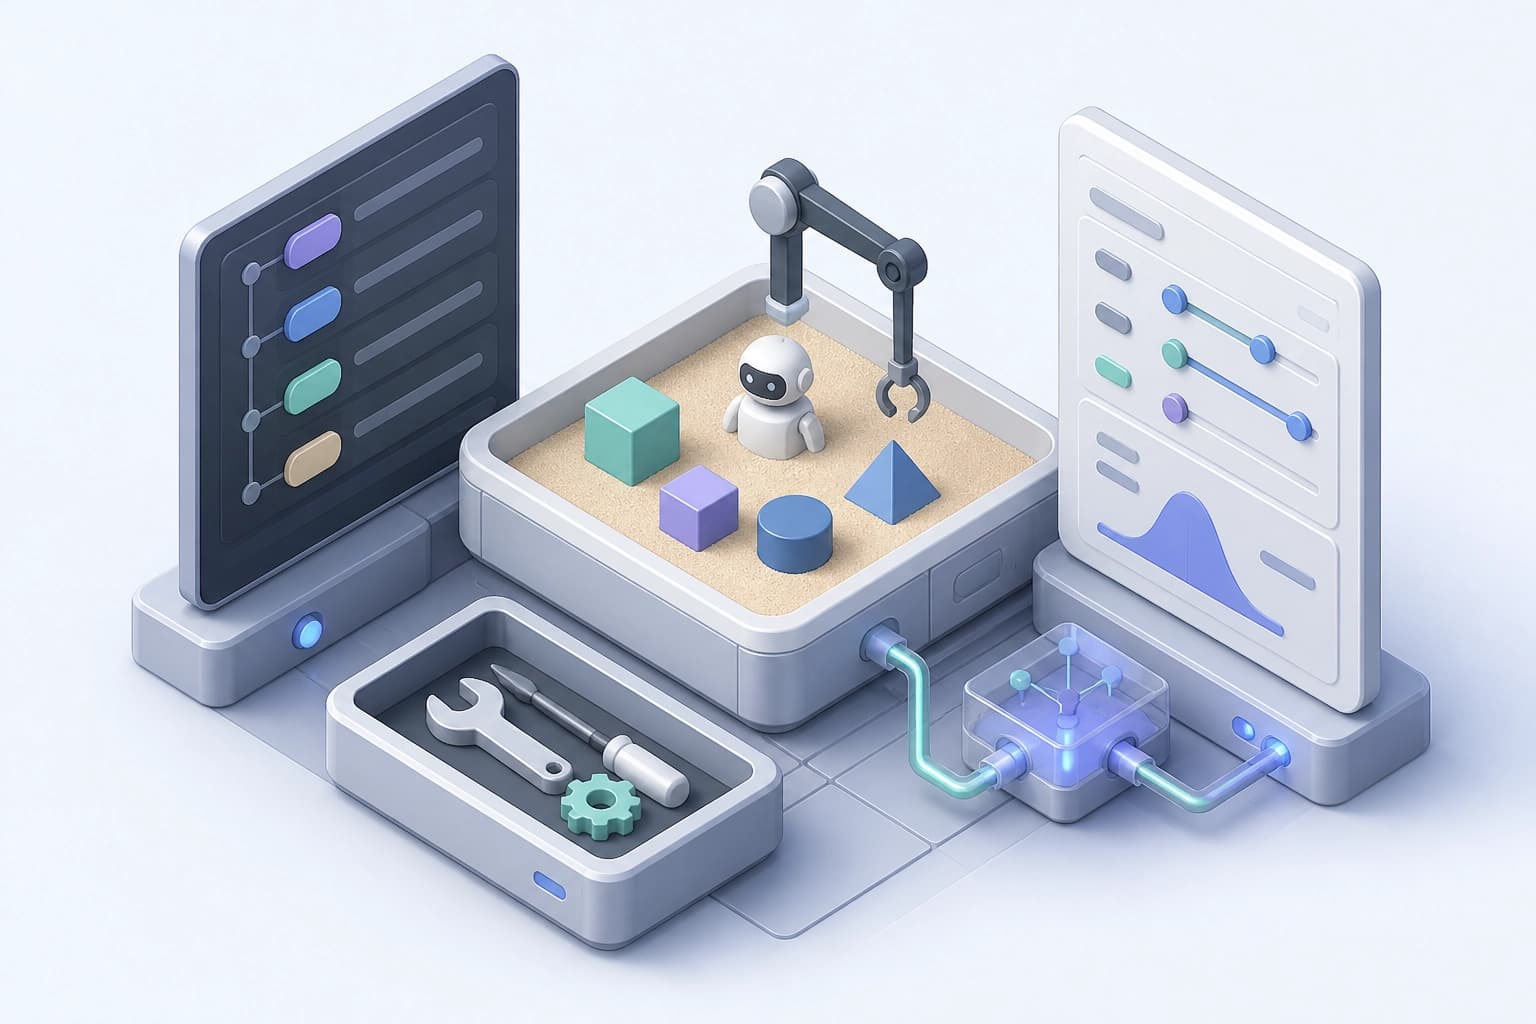
Key elements of verification:
- executing the call in an environment;
- recording the call result;
- checking the arguments, resources, and context against the policy;
- using an allowed tool in violating examples.
Takeaway: a benchmark must be executable. Choose an environment that preserves results and makes it possible to check arguments, resources, and context.
PolicyGym: Training Scenarios and Held-Out Tests
Built on the framework, PolicyGym is a dataset covering ten policy families. It includes 698 scenarios for generating training data. A separate set of 254 held-out scenarios is provided for test sets.
| Dataset part | Purpose | Size |
|---|---|---|
| Scenarios for generating training data | Preparing training examples | 698 |
| Held-out scenarios | Test sets | 254 |
The held-out scenarios were reviewed by humans. Practical criterion: keep training and held-out scenarios separate. The test set should be separate from training data generation.
A Trained Filter Versus Agent Self-Regulation
PolicyGym compares two approaches: policy-aware agent self-regulation and a trained defensive mechanism. The final configuration with the defensive mechanism delivers a relative reduction of 40–44% in the rate of successful attacks. It also produces fewer false refusals of harmless requests than using prompt policies alone.
| Configuration | What it uses | Results |
|---|---|---|
| Prompt policies only | Policy text | Baseline for comparison |
| Final configuration with a defensive mechanism | Trained filter | 40–44% fewer successful attacks; fewer false refusals |
Practical criterion: compare the defensive mechanism with the prompt baseline. Measure both successful attacks and false refusals.
Iterative Cycle: Attack, Fine-Tuning, Archive Update
The example-building process supports iterative training of a defensive mechanism. An attacker generates prompts using extracted strategies. The defensive mechanism is fine-tuned on balanced examples verified in an environment. Training improves policy enforcement even with a fixed archive.
Updating the archive provides an additional benefit. It reduces the attack success rate within the domain compared with leaving the archive unchanged.
Cycle stages:
- Extract attack strategies.
- Generate prompts for the attacker.
- Verify the examples in an execution environment.
- Balance the examples and fine-tune the defensive mechanism.
- Update the attack archive.
Practical criterion: build in an archive update cycle and verification of examples in an environment. A fixed archive already provides a training benefit. Updating it further reduces the attack success rate within the domain.
Frequently asked questions
Related materials
All materials
PerMIT: Long-Term Memory Integrity for LLM Agents and Machine-Verified Collective Trust
The authors propose the PerMIT architecture, which limits the flow of untrusted data from the environment into an agent’s sensitive actions through a finite memory interface. Two theorems verified in Lean 4 and the accumulation of community verdicts reduce the risk of poisoning without increasing the burden on individual users. In experiments on Trojan Hippo and τ²-bench, the approach recorded no successful injections with lightweight verifiers and improved the performance of new agents on held-out tasks.
20 November 2026
Composite multi-agent AI system with an evidence-based loop for proton therapy planning in head and neck tumors
The study describes a combination of a trained PPO policy that generates multiple plan options and LLM agents that conduct iterative dialogue, checking clinical metrics and constraints. Using data from 21 patients, the fine-tuned Qwen3-14B followed instructions more effectively and helped shift trade-offs in favor of priority goals. The practical takeaway is that automated DRL planning can be complemented by guided dialogue while preserving control over competing constraints.
20 November 2026
Computational Screening Instead of Empirical Trial and Error: New Approaches to Battery Materials
The article shows how computational databases, machine learning, and generative models narrow down promising compositions, while automated laboratories speed up their testing; the outcome still depends on synthesis and experiments, where predictions may differ from actual conductivity.
20 November 2026