
Personalization Through Wrapper Development: Where the Boundaries of Approximation, Generalization, and Optimization Lie
The authors investigate personal agents that adapt to an individual user’s requests while keeping the base model fixed, and formalize the improvement of the control layer—context, memory, tools, and execution—as a learning problem. A preference-oriented benchmark and theoretical analysis of approximation, generalization, and optimization errors show the limits of architecture, scale, and algorithms for self-evolving the wrapper.
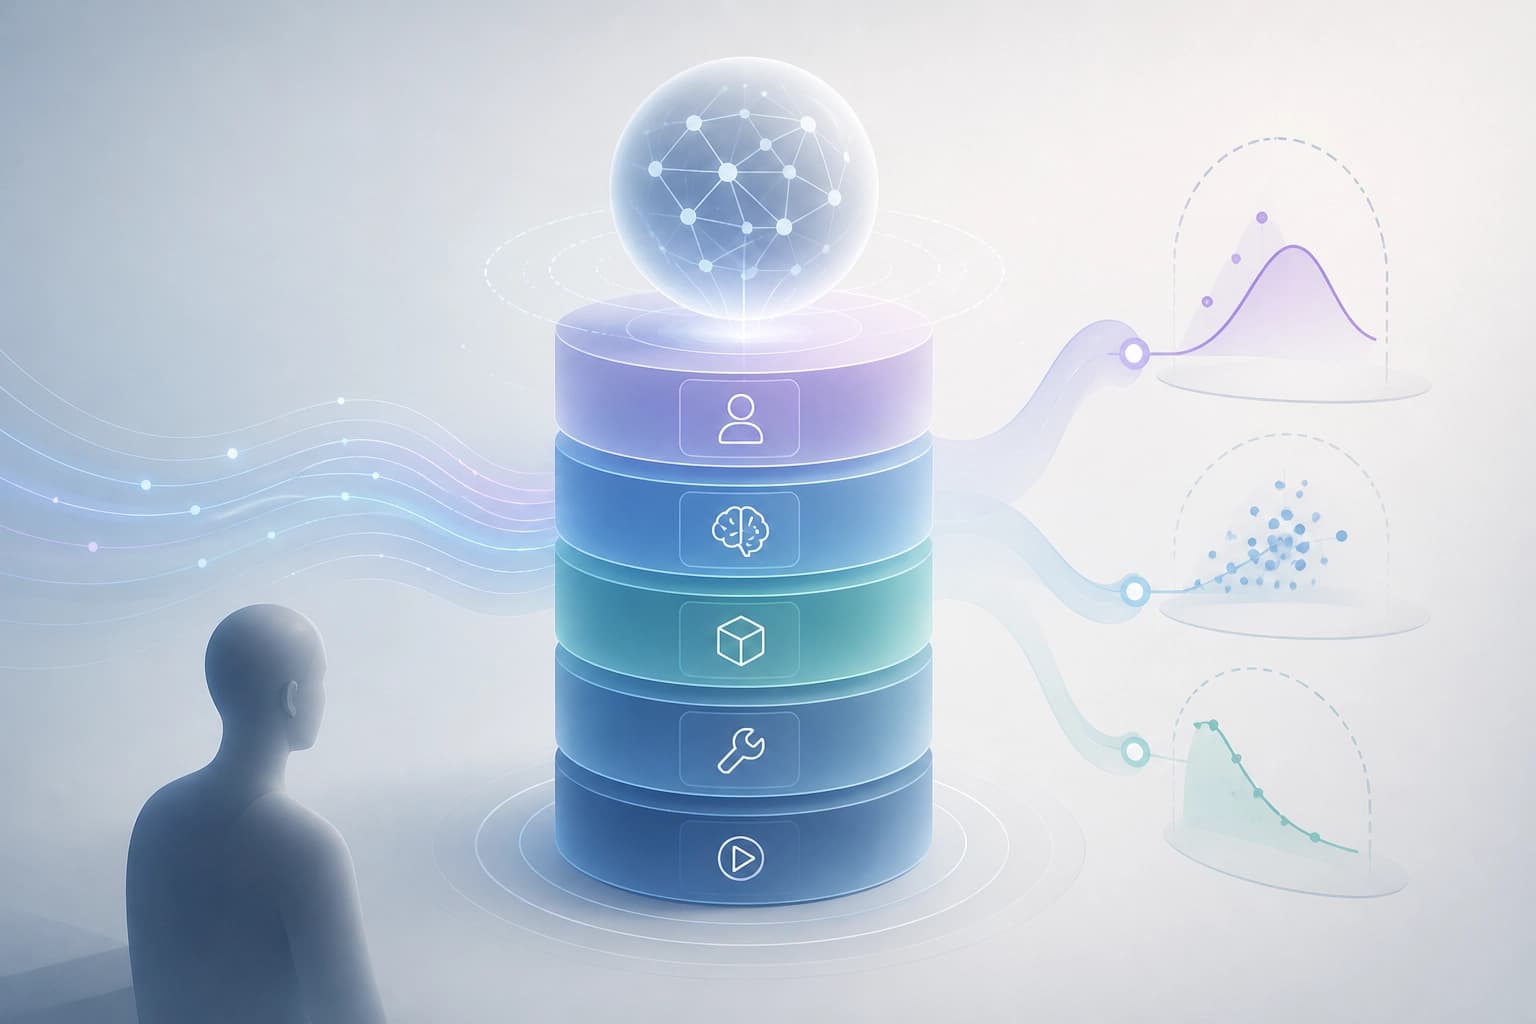
The personal agent harness manages context, memory, tools, and execution. It allows the agent to adapt to an individual user's preferences. The base model itself remains unchanged. This means the harness defines the personalization space.
The paper arXiv:2609.36892, “Harness Evolution as Learning: Approximation, Generalization, and Optimization Limits of Self-Improving Personal Agents,” was submitted on September 29, 2026. The authors are Zeyu Gan, Zixuan Gong, and Yong Liu. They study personal agents that adapt while the base model remains unchanged. Adaptation relies on harness design and evolution.
What evolves: architecture, scale, algorithms
The authors study harness evolution along three dimensions: architecture, scale, and self-evolution algorithms. Architecture determines how the harness manages context, memory, tools, and execution. Scale and self-evolution algorithms define the framework for the same process.
The empirical section presents a preference-oriented benchmark. It systematically characterizes the capabilities and limitations of personal agents in relation to these three dimensions. In other words, the dimensions serve as evaluation axes rather than independent improvements.
Practical criterion: evaluating a single dimension does not describe the agent's overall capabilities and limitations. It makes sense to examine the harness along all three axes at once.
Three types of error as a framework for limits
The theoretical section formulates harness evolution as a learning problem. It explains observed phenomena in terms of approximation, generalization, and optimization errors. These three types of error provide the framework for discussing the limits of personalization.
The authors offer a unified view of the limits of personalization through harness evolution. On this basis, they discuss harness design. This connects the empirical section with the theoretical one.
Practical criterion: describe the limits of personalization in terms of a specific type of error, not a general assessment of the harness. This description shows exactly where progress runs up against a limit.
Reachable policies, evidence, and bias
The theoretical analysis covers reachable policies. This refers to the set of strategies the agent can arrive at. A strategy outside this set remains inaccessible regardless of how the harness is configured.
The analysis covers capacity given finite evidence from interactions. Interaction experience is finite by nature. Its volume limits the conclusions the agent can draw about user preferences.
The analysis covers biased update dynamics. Bias affects how the harness is updated during self-evolution. This factor operates independently of the lack of evidence.
Practical criterion: when analyzing failed personalization, distinguish between an unreachable policy, insufficient evidence, and bias in updates. These three causes require different solutions.
Criteria for harness design
- Treating architecture, scale, and self-evolution algorithms as separate decision areas.
- Relying on a preference-oriented benchmark.
- Describing the limits of personalization in terms of approximation, generalization, and optimization errors.
- Accounting for the finite nature of interaction evidence and bias in update dynamics.
- Maintaining a unified view of the limits of personalization when designing the harness.
This set of criteria keeps personalization within the bounds of what the harness can actually provide while the base model remains unchanged. It also shows where design ends and a limit begins.
Frequently asked questions
Related materials
All materials
Moving to the Probability Simplex Reduces the Modality Gap in Contrastive Multimodal Models
The paper arXiv:2610.32890 proposes replacing spherical embeddings with a probabilistic simplex, adding lightweight softmax adapters and Total Variation similarity. Across five retrieval benchmarks, the cross-modal centroid ℓ2 distance decreases by 97–99% while retrieval quality is maintained or improved.
3 November 2026
How ActionRAG Reconsiders Evidence During Diffusion Across the Memory Graph of LLM Agents
A graph-memory architecture is proposed that carefully reconciles entities during indexing and reevaluates relationships at query time based on local structure. On MemoryAgentBench, the method achieved an average accuracy of 55.1, outperforming the strongest retrieval baseline by 5.4 percentage points while keeping synthesis costs low per query.
3 November 2026
Fifteen companies backed MDK Tether for mining automation
Equipment manufacturers, mining pools, and operators have taken on the development of integrations with Tether’s open suite to standardize equipment monitoring and management; the QVAC AI agent is already built on this foundation. Independent confirmation of reduced electricity costs or increased efficiency has not yet been published.
2 November 2026