
GoldiMask Method for Fine-Tuning Diffusion Language Models: Context Selection and Target Weighting
This paper presents GoldiMask, a supervised fine-tuning approach for discrete diffusion language models that selects visible tokens via approximate maximization of a submodular function and assigns weights to remaining targets based on their training utility. Experiments across several models and datasets demonstrate improved average accuracy, gains on reasoning and coding tasks, and fewer parallel decoding iterations on GSM8K and MATH-500 at comparable quality.
Masking makes two decisions at once
Fine-tuning discrete diffusion language models relies on recovering masked tokens. Some answer tokens are hidden behind masks, and the model predicts their original values from the visible context.
The masking scheme determines two things at once. It determines which context is available to the model. It also determines which tokens become prediction targets.
These decisions are linked: a revealed token is no longer a target. Uniform random masking does not account for this link. As a result, some tokens are revealed where doing so offers little help for prediction.
The GoldiMask method is described in the paper Fine-Tuning Diffusion Language Models with Context Selection and Target Weighting (arXiv:2609.38385, September 29, 2026). It is designed for supervised fine-tuning of discrete diffusion language models.
| Decision | Uniform random masking | GoldiMask |
|---|---|---|
| Which tokens to reveal as context | random selection | selection based on a submodular objective |
| Weight of the remaining target tokens | independent of the selected context | depends on how helpful the context is and on learning potential |
| Relationship between the two decisions | not accounted for | accounted for through model signals |
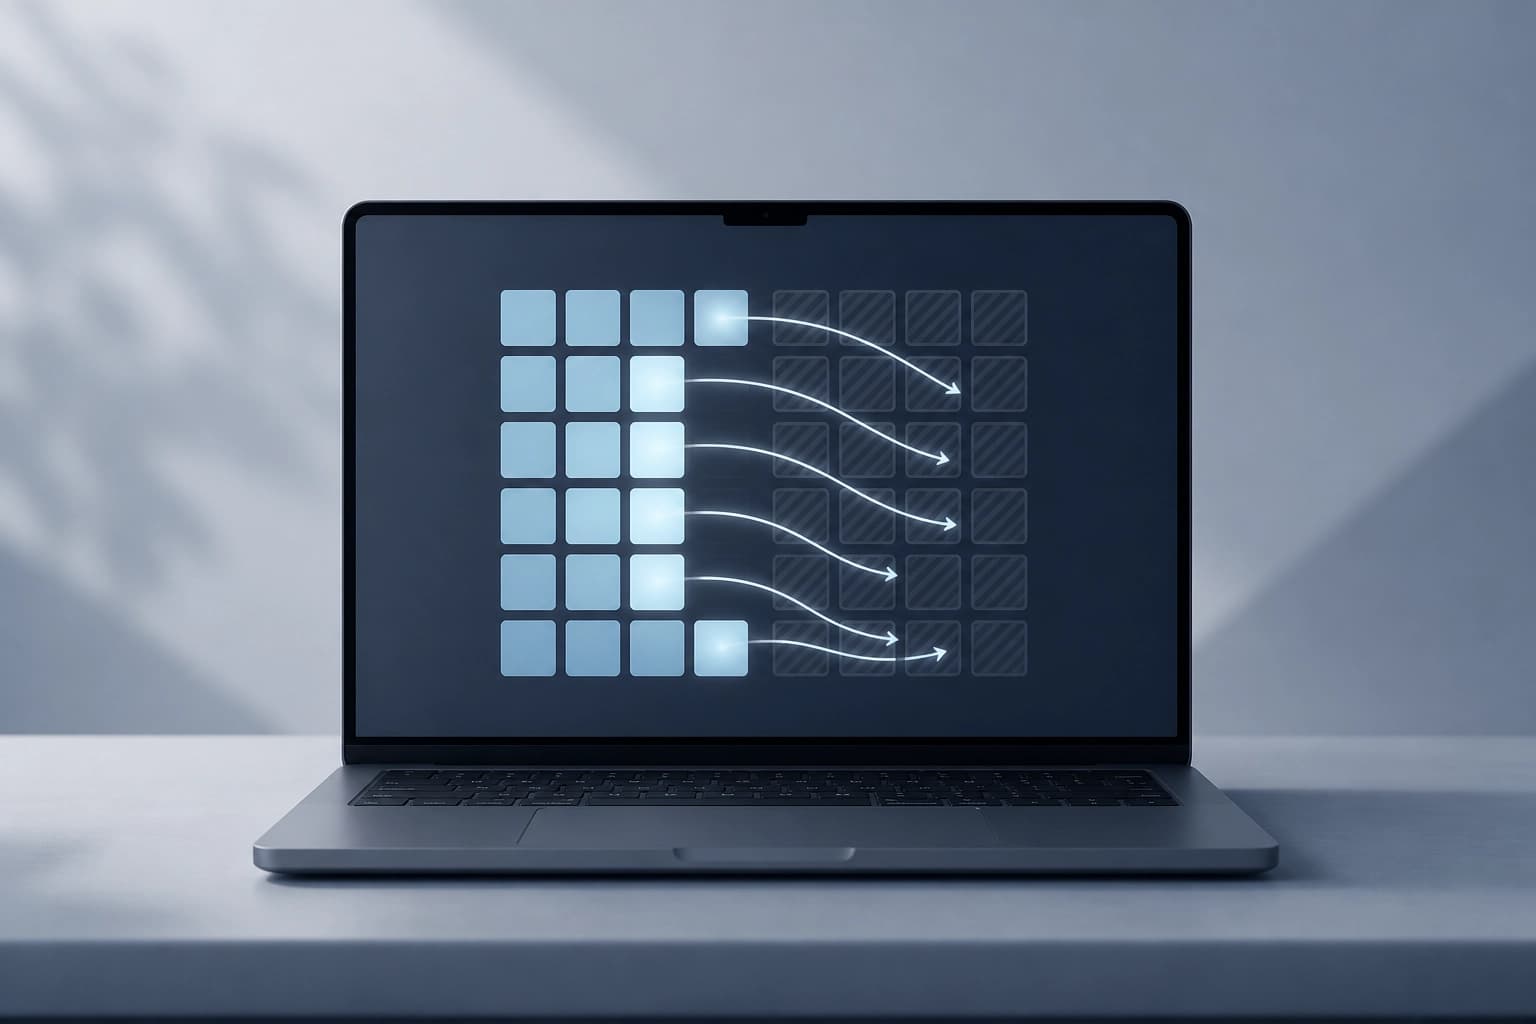
Criterion: the masking scheme should be evaluated as a single decision about context and targets. This makes it clear where revealing tokens is justified and where it is not.
Selecting context based on model signals
GoldiMask selects tokens to reveal as context. The selection approximately maximizes a submodular objective.
The method uses model signals and balances two factors:
- the benefit of revealing a particular token;
- the value of that token as a prediction target.
A token that helps predict its surroundings is worth revealing. A token that the model predicts poorly is better left as a target.
Practical criterion: random context selection does not use model signals. If this is the scheme being used, the potential of context selection remains untapped.
Weighting target tokens
After context selection, some tokens remain as prediction targets. GoldiMask weights them based on two factors:
- how much the selected context helps predict a particular token;
- how much learning potential remains for that token.
This way, the weights tie the targets to the context decision already made. Weighting does not determine what to reveal. It determines how much the tokens that remain hidden contribute to training.
Criterion: when analyzing a masking scheme, it is useful to separate two questions — what to reveal and how much weight to give the remaining tokens during training.
Results on models and datasets
GoldiMask was tested on three base models and three training datasets. The method achieved the highest average accuracy in most of the evaluated settings.
Improvements affected reasoning and code generation tasks. Ablations of the components showed that both mechanisms contributed to the improvements: context selection and target-token weighting.
Practical criterion: the highest accuracy in most settings does not mean an improvement in every configuration. The method should be tested on the specific base model + training dataset pair.
Effect on parallel decoding
A separate result concerns parallel decoding with a confidence threshold. On GSM8K and MATH-500, GoldiMask reduces the number of decoding iterations.
Accuracy remains comparable at higher confidence thresholds.
Practical criterion: if the pipeline uses parallel decoding with a confidence threshold, the method affects both the number of decoding steps and accuracy. Evaluating accuracy alone is incomplete here.
Frequently asked questions
Related materials
All materials
Moving to the Probability Simplex Reduces the Modality Gap in Contrastive Multimodal Models
The paper arXiv:2610.32890 proposes replacing spherical embeddings with a probabilistic simplex, adding lightweight softmax adapters and Total Variation similarity. Across five retrieval benchmarks, the cross-modal centroid ℓ2 distance decreases by 97–99% while retrieval quality is maintained or improved.
3 November 2026
How ActionRAG Reconsiders Evidence During Diffusion Across the Memory Graph of LLM Agents
A graph-memory architecture is proposed that carefully reconciles entities during indexing and reevaluates relationships at query time based on local structure. On MemoryAgentBench, the method achieved an average accuracy of 55.1, outperforming the strongest retrieval baseline by 5.4 percentage points while keeping synthesis costs low per query.
3 November 2026
Fifteen companies backed MDK Tether for mining automation
Equipment manufacturers, mining pools, and operators have taken on the development of integrations with Tether’s open suite to standardize equipment monitoring and management; the QVAC AI agent is already built on this foundation. Independent confirmation of reduced electricity costs or increased efficiency has not yet been published.
2 November 2026