Verifiable reward and its blind spot
Reinforcement learning from verifiable rewards has become a familiar recipe for language models: there is a task with an unambiguously checkable answer — math, code, short-answer questions — and there is a "solved / not solved" signal. The scheme works, but it has a known weakness. The final reward evaluates the outcome as a whole, not the path to it. A model can earn a point for a correct conclusion built on fabricated premises, and just as easily lose a point for correct reasoning with an unfortunate final formulation.
This is exactly where the risk of hallucinations lives. If the reward depends only on the final match, the policy has no incentive to be careful along the way — it is enough to guess the answer. One way to fix this is to add factual control at the process level: checking intermediate claims, not just the outcome.
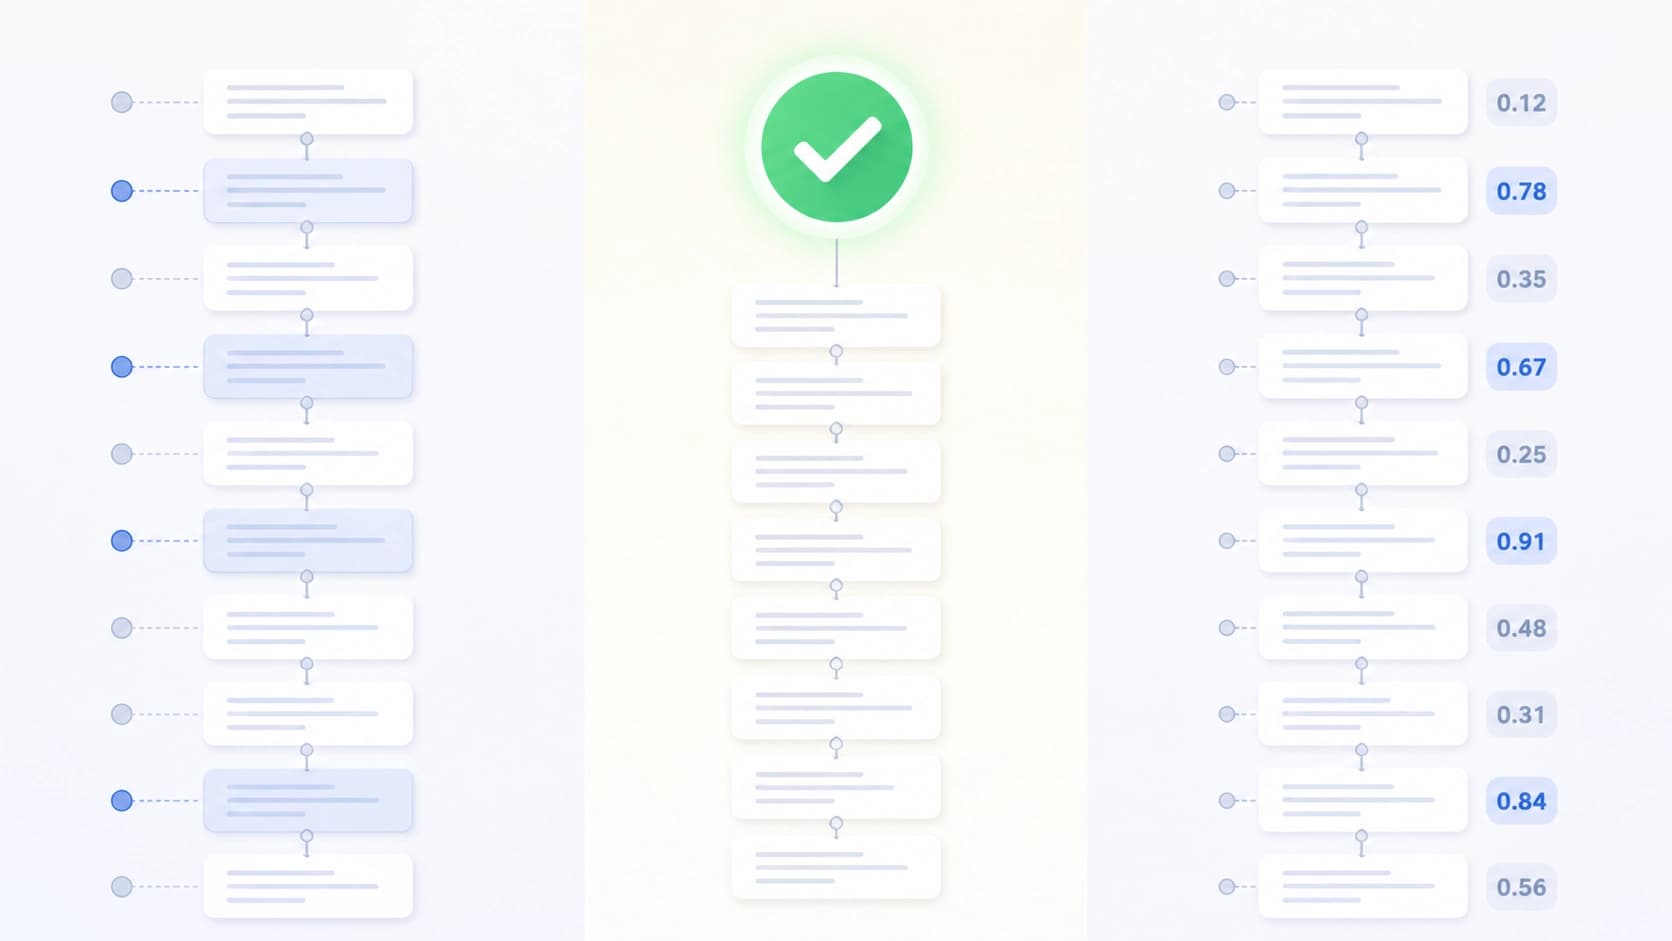
But the process-level approach turns out to have a problem of its own. Fact checks are aggregated and averaged coarsely: the signal arrives as a batch for the whole fragment, and no one assesses the reliability of the checks themselves. As a result, a gap emerges between what was actually checked and what was actually updated in the policy.
Two ambiguities instead of one problem
The authors of arXiv:2608.24350 (Qiming Xie, Wenjie Zheng, Xiangqing Shen, Rui Xia) give this gap a name — "noisy factual credit assignment" — and break it down into two independent aspects.
- Credit localization ambiguity. It is unclear which exact token or fragment should be credited or blamed. The fact was checked at the sentence level, but the update happens at the token level — the granularities do not match, and the signal gets smeared.
- Credit reliability ambiguity. It is unclear how much the check itself can be trusted. Some factual judgments are reliable and reproducible, others are shaky, depending on context or on a particular formulation. Without a confidence weight, they enter training on equal footing.
The second aspect is the most underrated. Conventional schemes for handling factual signals behave as if all checks were equally good. In practice they are not, and weak checks start corrupting the optimization just as much as strong ones.
How FARCA works
FARCA stands for Fact-Aligned Reliability-Aware Credit Assignment. It is not a new model or a dataset, but a policy optimization framework: it restructures how factual control is turned into a training signal.
Aligning granularities
The first step is fine-grained credit localization. The idea is simple in formulation and non-trivial in implementation: the granularity of fact checking must be brought into line with the granularity of policy updates. Then the factual signal does not arrive "as an average over the whole answer" but is tied to the specific tokens that are actually responsible for that claim. Instead of blurred averaging, the policy receives pinpoint guidance.
Assessing how much the check can be trusted
The second step is reliability weights. To compute them, the authors introduce counterfactual evidence attribution: they look at how much a factual judgment depends on the key evidence fragment. If removing or replacing that evidence changes the verdict, then the check really does rely on it, and such a signal deserves more trust. If the verdict stays the same regardless of the evidence, the judgment is probably not about what we think it is — and its weight drops.
The resulting weights then modulate the factual rewards and local policy advantages. The practical meaning: potentially unreliable signals get a smaller voice in the update rather than being blocked entirely. This is soft filtering instead of hard rejection — the policy does not lose information, but it stops following it blindly.
What the experiments show
The authors tested the approach on different models and several benchmarks evaluating factual reasoning. The claimed result is a noticeable increase in factuality while preserving general reasoning abilities. The latter part here is no less important than the former: improvements in factuality are often bought at the cost of degrading other skills, when the model becomes more cautious and simultaneously weaker. According to the authors' data, this does not happen here.
It is also worth noting that the method stays within the RL with verifiable rewards paradigm — it does not require abandoning the existing pipeline or replacing it with something fundamentally different. It slots in as a layer between fact checking and policy updates.
What follows from this
The main idea of the work is broader than one architecture. The conversation about model factuality usually follows the logic of "to check or not to check." But once checks already exist, the key question shifts: how exactly their result is turned into learning. An error at this junction does not look like an error — it looks like ordinary training noise, and therefore easily goes unnoticed.
Acknowledging that sources are not trusted equally seems almost trivial at the level of common sense. But in reinforcement learning schemes it is still rare: signals are thrown into a common pot, and the difference between reliable evidence and a random guess is erased. FARCA is an attempt to bring that difference back into the formula. How transferable the approach will prove beyond tasks with a verifiable answer, where a fact cannot be so easily confirmed or refuted, is an open question — and it is also the most interesting direction for future work.