Why LLMs Make Mistakes Under Partial Observability
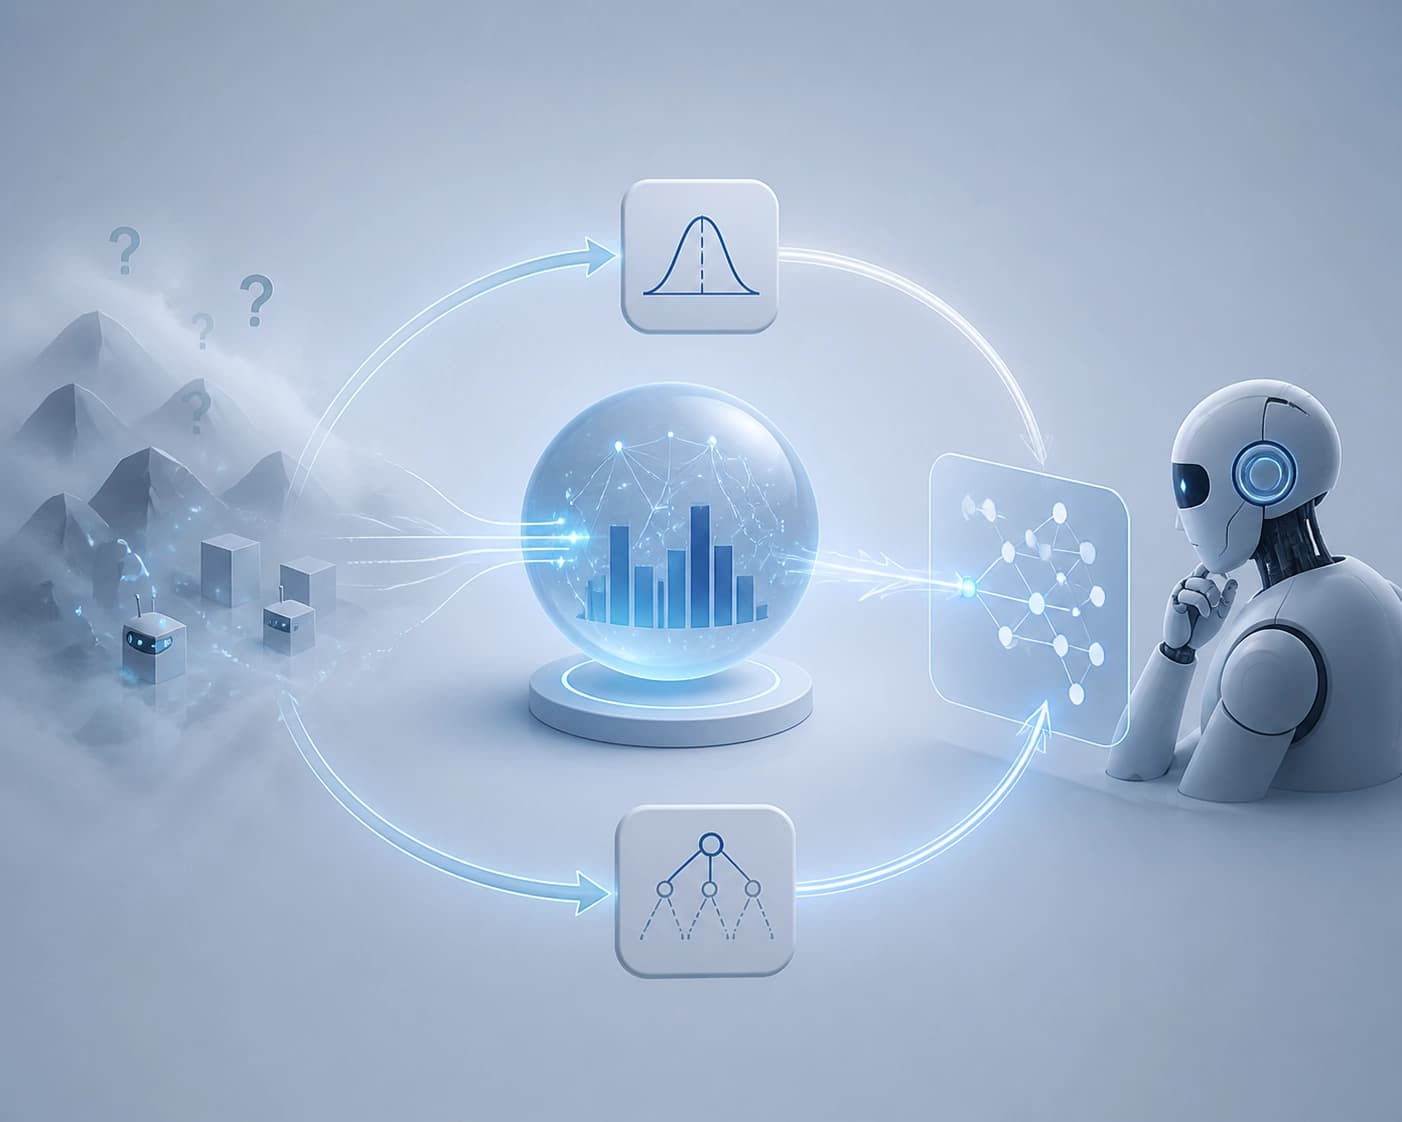
The authors link errors made by LLM agents in partially observable environments to the absence of an explicit belief distribution over the hidden state. Typically, an agent acts according to a policy conditioned on its history of actions and observations.
The article describes three characteristic errors:
- making a decision prematurely in response to ambiguous feedback;
- shifting toward the wrong hypothesis after an informative observation;
- policy drift as the history grows.
The problem is not just the quality of the answer to an individual query. The agent lacks an explicit representation of which hidden states it considers possible.
How the External Bayesian Loop Works
The Belief-State Engine (BSE) is an inference module outside the LLM. It maintains a Bayesian posterior distribution over the hidden states of a given POMDP—a partially observable Markov decision process.
At each step, the loop works as follows:
- The BSE updates the belief distribution over the hidden state.
- The LLM receives only this distribution.
- The original log of actions and observations remains inaccessible to the LLM.
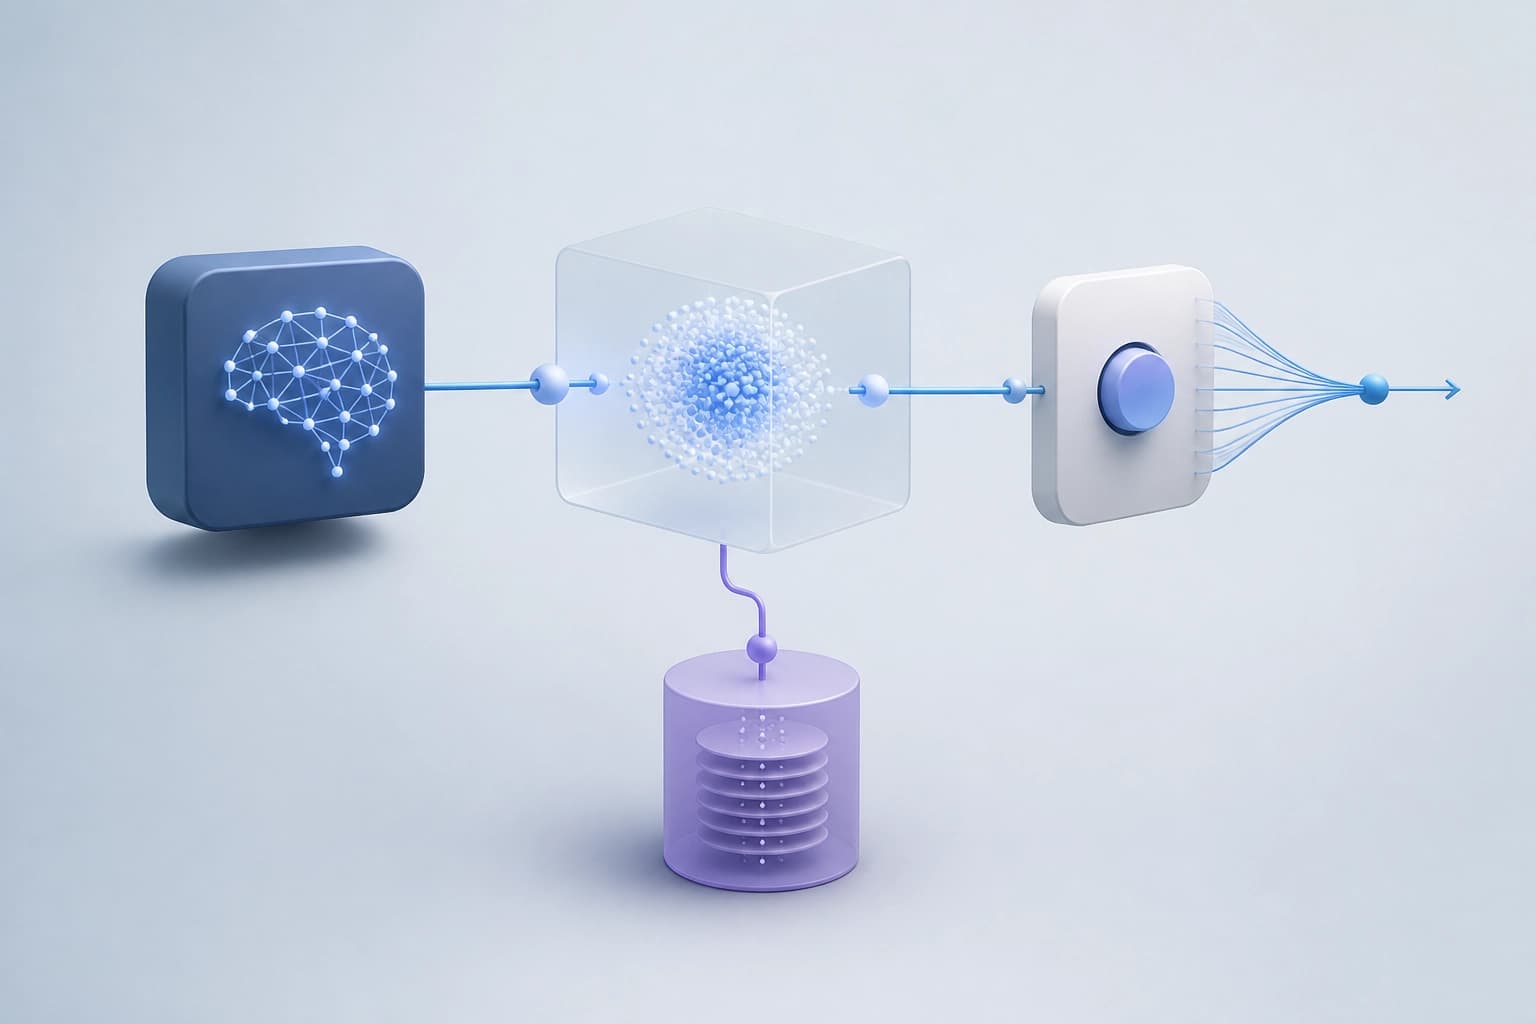
This approach separates uncertainty tracking from the language model. The key architectural condition is that the LLM does not receive the original history.
Which Guarantees Depend on the Architecture
The authors define a minimal specification of four axioms for a belief-consistent internal state. The axioms themselves are not disclosed here.
The authors prove that the LLM and BSE together form a valid Markov policy on the belief MDP induced by the original POMDP. Provided the LLM never has access to the original history, the system inherits the Bellman optimality guarantees of classical POMDP theory.
Practical criterion: these guarantees apply to the described system and depend on restricting access to the history. They cannot be separated from the architectural conditions.
What the Evaluation Showed
The architecture was tested on the Tiger POMDP and a red-team attack-graph task. The comparison included six baseline methods.
| Baseline method | BSE result in both domains |
|---|---|
| Reactive LLM | Higher task return, better belief calibration, and greater decision consistency |
| Chain-of-Thought | Higher task return, better belief calibration, and greater decision consistency |
| ReAct | Higher task return, better belief calibration, and greater decision consistency |
| Natural-language belief tracker | Higher task return, better belief calibration, and greater decision consistency |
| QMDP | Higher task return, better belief calibration, and greater decision consistency |
| POMCP | Higher task return, better belief calibration, and greater decision consistency |
The abstract also states that the effect is not specific to a single model. Ten targeted ablations are intended to isolate the contribution of individual architectural choices.
When the Approach May Be Worth Considering
The BSE supports a distribution over the hidden states of a given POMDP. Therefore, describing the task within such a model is a central criterion for whether the approach is applicable.
The article's evaluation covers the two specified domains. It does not establish that the results transfer to all tasks involving incomplete data.
What Is Available for Verification
The preprint Belief-State Engine: Augmenting LLMs for Principled Planning Under Partial Observability includes code, environment specifications, prompt templates, and seed logs.
Arnab Chattopadhayay and Debdipta Halder submitted the paper to arXiv on September 9, 2026. The practical takeaway should be assessed in light of the environments, comparisons, and conditions governing LLM access to the history.