
Evaluating AI agents without access to their internals
The article describes a method for testing autonomous systems across seven threat categories: the SAGE-RT generator creates 120 attack scenarios for each category. Tests of CrewAI and AutoGen revealed high levels of vulnerability in agent behavior, as well as risks to governance and privacy, especially in multi-agent configurations.
What a black-box assessment means
A black-box approach evaluates the observable behavior of an agentic system. Only basic descriptions of the system are needed for testing; privileged access is not required.
This approach links observable behavior to risk categories. It makes it possible to conduct an assessment without access to internal mechanisms.
Practical criterion: choose black-box testing if privileged access is unavailable but you can provide a basic description of the system.
What the assessment involves
The framework combines a risk taxonomy with automated red teaming. The authors identify seven domains that link agent behavior to risk categories.
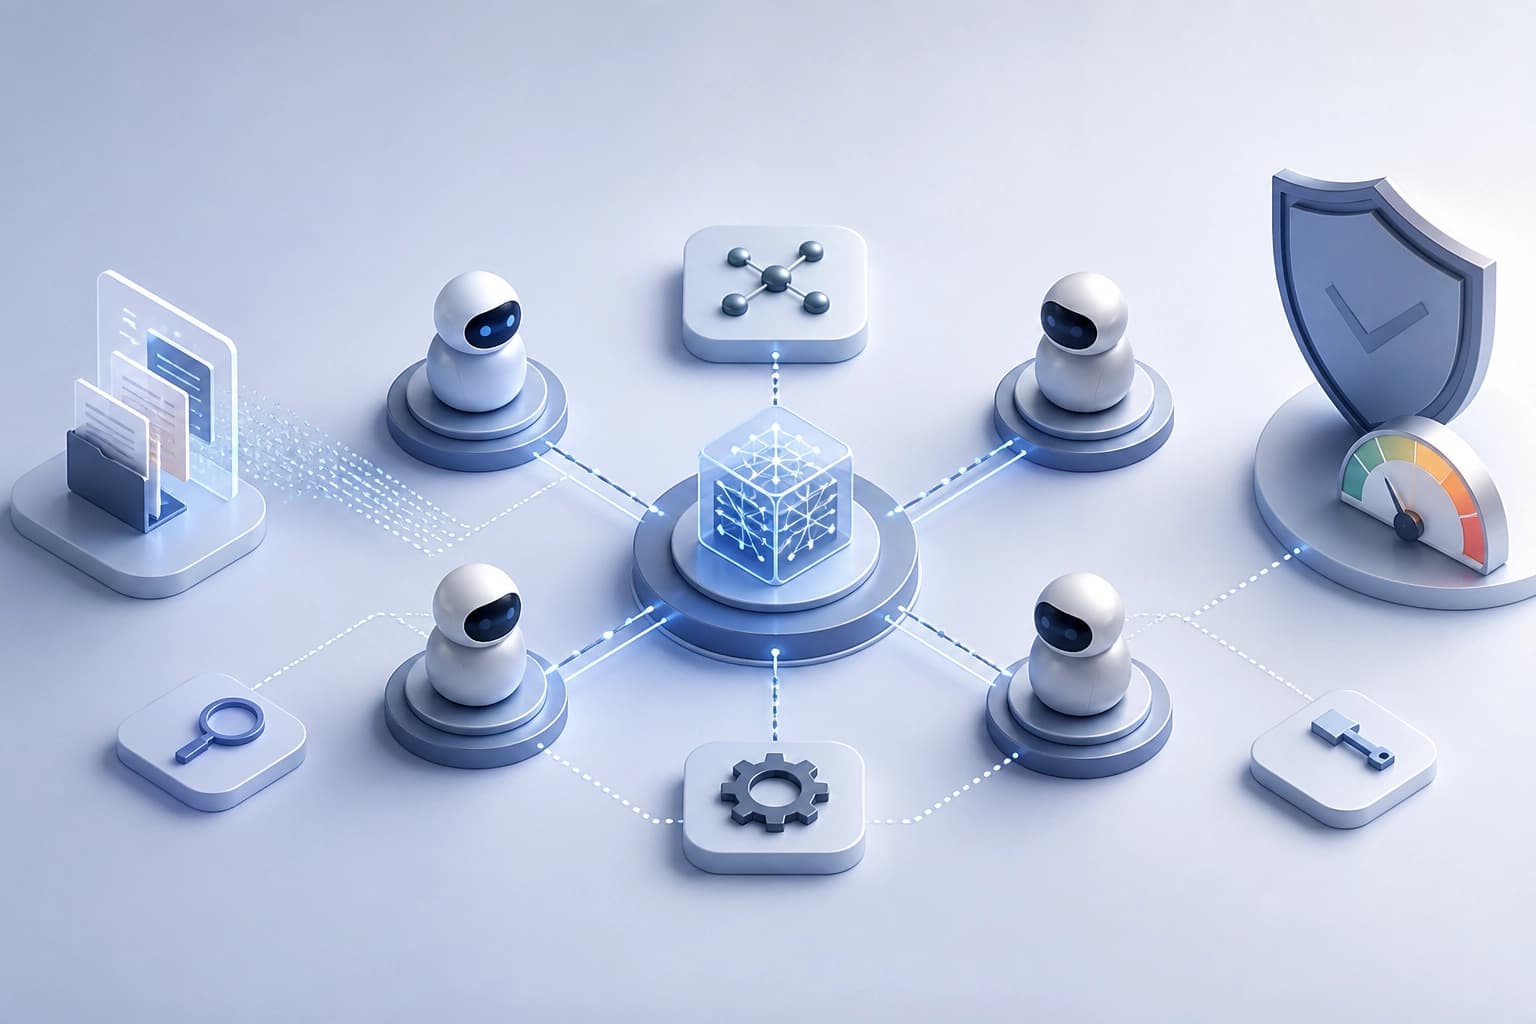
SAGE-RT creates 120 adversarial scenarios for each domain. The assessment also includes human validation and LLM judges.
- Taxonomy: seven risk domains.
- Scenarios: automated red teaming for each domain.
- Result verification: human validation and LLM judges.
Selection criterion: the method is a good fit if you need automated scenario generation followed by review by people and LLM judges.
What the assessment found
The authors tested two agent architectures — CrewAI and AutoGen — and four baseline models.
| Metric | Result |
|---|---|
| Average governance risk | 56.25% |
| Privacy risk in multi-agent configurations | 65% |
| Agent behavior vulnerabilities | up to 85% |
These values describe different metrics. They should not be combined into a single overall risk score.
Practical criterion: when comparing results, preserve the original metric categories and configuration context.
Why a single-step assessment is not enough
The authors note that standard assessments remain single-step. They do not identify vulnerabilities that arise across a sequence of actions.
The risks are related to how agents operate:
- read untrusted inputs;
- call tools with real permissions;
- act autonomously.
The combination of these factors expands the security surface. Assessment criterion: test not only an individual response, but also the agent’s behavior across multiple steps.
When to choose a black-box approach
This approach is suitable for assessing risks when internal access to the agent is unavailable. A basic description of the system is sufficient.
It is also useful when the assessment needs to link observable behavior to risk categories. A single-step assessment is not enough to find multi-step vulnerabilities.
Practical criterion: choose this approach if you need to test behavior without privileged access and account for risks that arise across multiple steps.
Frequently asked questions
Related materials
All materials
AURA-Eval: How to Check Whether an LLM Agent Recognized a Risk and Changed Its Next Step
The framework evaluates LLM agents’ behavior not by their final verdict, but by how they respond to risk at key decision points: tool-call trajectories are interrupted, after which the model must continue reasoning and acting, while a panel of LLM judges assesses risk detection, the nature of the step, and its safety. Across 1,249 tasks drawn from 157 R-Judge trajectories, unsafe actions become more frequent among 20 models when no safe path is available, and removing oversight before execution turns 52.3% of initially safe cases into unsafe ones.
10 November 2026
Chern–Simons Reservoir Memory: Autonomous Connectivity Dynamics and Density Transport
The article explores how a reservoir preserves the history of input signals both in its density distribution and in its geometric degrees of freedom. A comparison of four mechanisms shows that current creates a separate connected component that alters the subsequent density response, while accounting for all measured features yields a small improvement in decoding pulse order.
10 November 2026
STAR: Adaptive Normalization of Temporal Context and Service Graphs for End-to-End Incident Management
The STAR framework trains representations from metrics, logs, and traces, using learnable normalization that accounts for multiscale temporal dynamics and dependency structures between services. On two real-world datasets, this pipeline delivers consistent improvements in anomaly detection, failure ranking, and root cause analysis over state-of-the-art baselines.
10 November 2026