Why SFT After RL Threatens Reasoning
Reinforcement learning develops large language models’ reasoning abilities. This approach has become effective for post-training LLMs. Subsequent supervised fine-tuning adapts a post-RL model to new knowledge domains or types of behavior. This SFT can seriously overwrite acquired abilities.
Existing approaches to reducing forgetting:
- experience replay;
- specialized initialization;
- constrained optimization with gradient projection.
These methods either provide limited retention of abilities or require significant additional computation. Practical criterion: for a post-RL model, choose a method that reduces the risk of overwriting reasoning.
Null Space as a Resource for Adaptation
The authors show that reasoning-related activations are concentrated in low-dimensional subspaces. Significant capacity remains in the null space for adaptation. Approximate null spaces can be reliably estimated from a small number of examples.
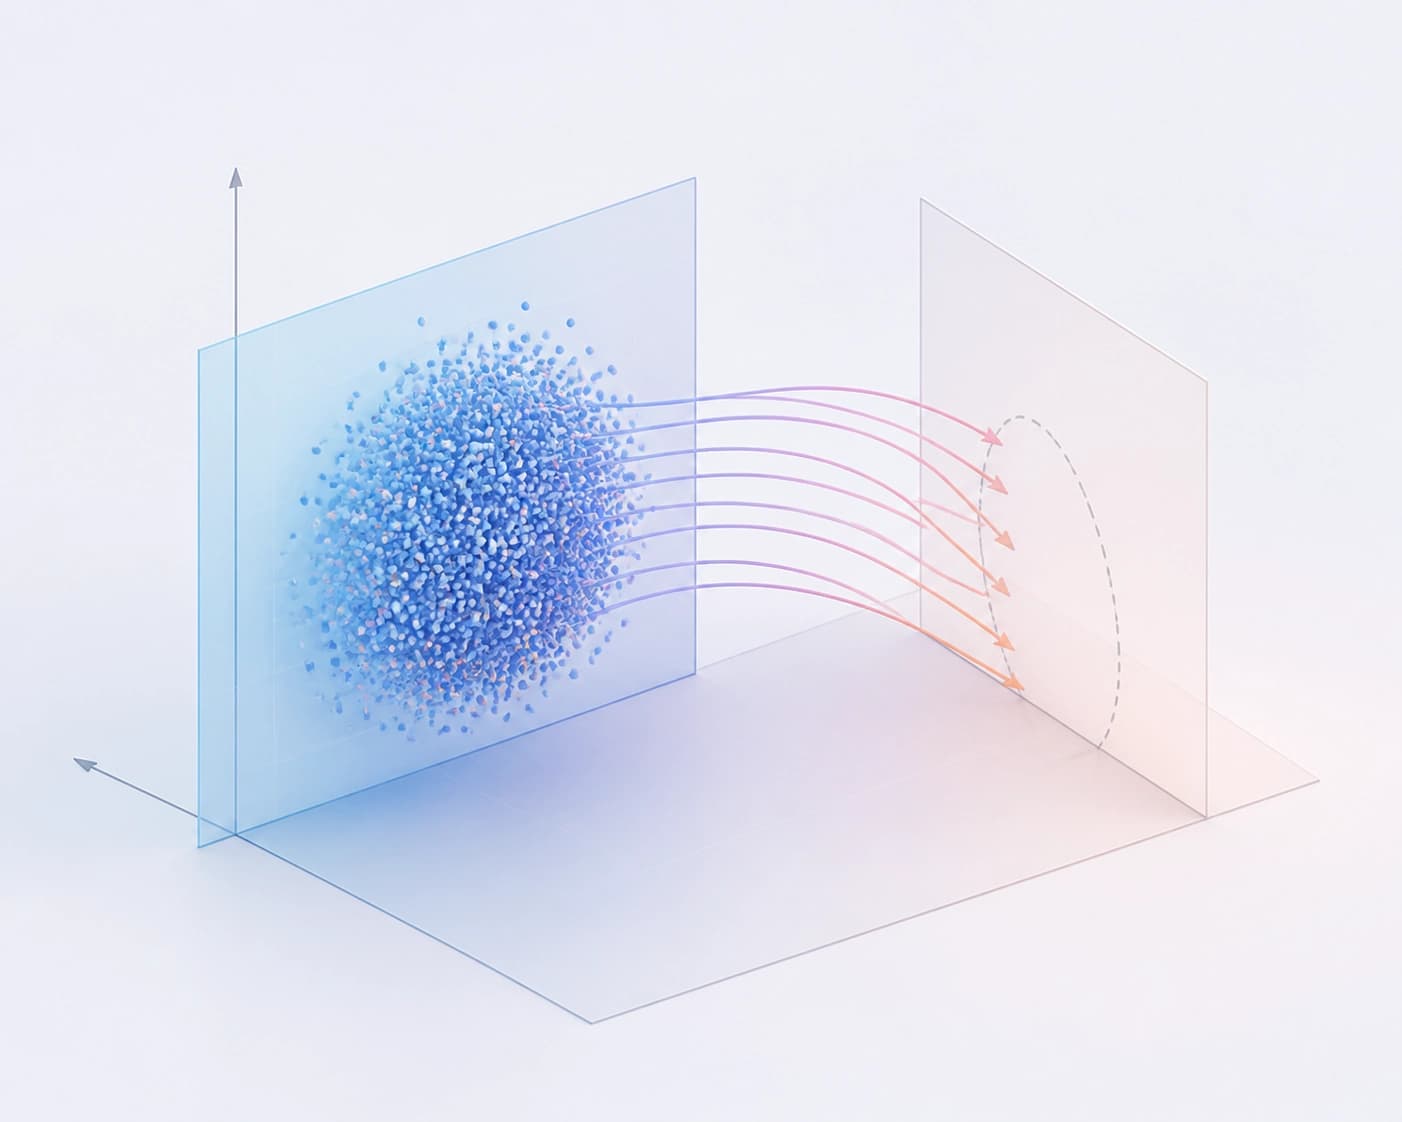
Practical criterion: a method that constructs updates in the null space uses this available capacity. It does not affect reasoning activations.
How NB-LoRA Works
Null-Basis Low-Rank Adaptation (NB-LoRA) is a parameter-efficient adaptation method for post-RL LLMs. It was proposed in the paper arXiv:2609.25618. The method preserves acquired reasoning abilities.
How it works:
- A fixed approximate null basis is constructed from reasoning activations.
- LoRA updates are reparameterized through this basis.
- Reasoning preservation is formulated as a constraint on preserving hidden states at the layer level.
- The constraint is enforced throughout fine-tuning.
Practical criterion: choose NB-LoRA when you need to perform SFT while preserving the reasoning of a post-RL model.
Comparison with Existing Approaches
The table compares mechanisms and features.
| Criterion | Existing approaches | NB-LoRA |
|---|---|---|
| Mechanism | Experience replay, specialized initialization, constrained optimization with gradient projection | LoRA reparameterization through a fixed approximate null basis |
| Feature | Limited retention of abilities or significant additional computation | Constraint on preserving hidden states at the layer level |
Practical criterion: if preserving reasoning is a priority, NB-LoRA provides an inherent constraint. Existing approaches require choosing between limited retention and additional computation.
Experimental Results and Selection Criterion
The experiments cover several RL-trained LLMs and a variety of subsequent tasks. NB-LoRA achieves adaptation quality on par with standard LoRA. The method preserves reasoning accuracy at around its pre-fine-tuning level. This retention transfers to held-out reasoning benchmarks.
Practical criterion: for post-RL LLMs where SFT threatens reasoning, NB-LoRA is a candidate to evaluate on your own tasks.