The Consent Paradox as Network Pressure
Authors Dahlia Shehata and Ming Li point to the parametric vulnerability of large language models to adversarial swarm consensus. The paper was published on arXiv as arXiv:2609.25570 and submitted on 22 Sep 2026. Agent-group pressure shifts the model’s output toward agreement.
Key elements of the problem:
- parametric vulnerability relates to the model itself, not an individual task;
- sycophancy describes the model’s tendency to adapt to group pressure;
- CED aims to mitigate sycophancy and reduce cognitive loafing;
- network pressure replaces an agent’s independent reasoning with collective reasoning.
Conclusion: the failure manifests as agreement, not as a reasoning error.
How CED works
CED is a zero-shot inference intervention for mitigating sycophancy. The method requires no fine-tuning. Its main difference from standard Contrastive Decoding lies in its use of a secondary model.
Standard Contrastive Decoding uses a weaker secondary model. CED performs a dual forward-pass on a single architecture to isolate conformity bias. This approach does not conflate agreement with actual task-solving ability.
| Feature | Contrastive Decoding | CED |
|---|---|---|
| Secondary model | weaker | not used |
| Number of forward passes | — | dual forward-pass on a single architecture |
| Isolated factor | — | conformity bias |
Token suppression is applied through an asymmetric, zero-bounded probability clamp and a discrete top-k truncation mask. These components remove toxic consensus tokens without grammatical collapse.
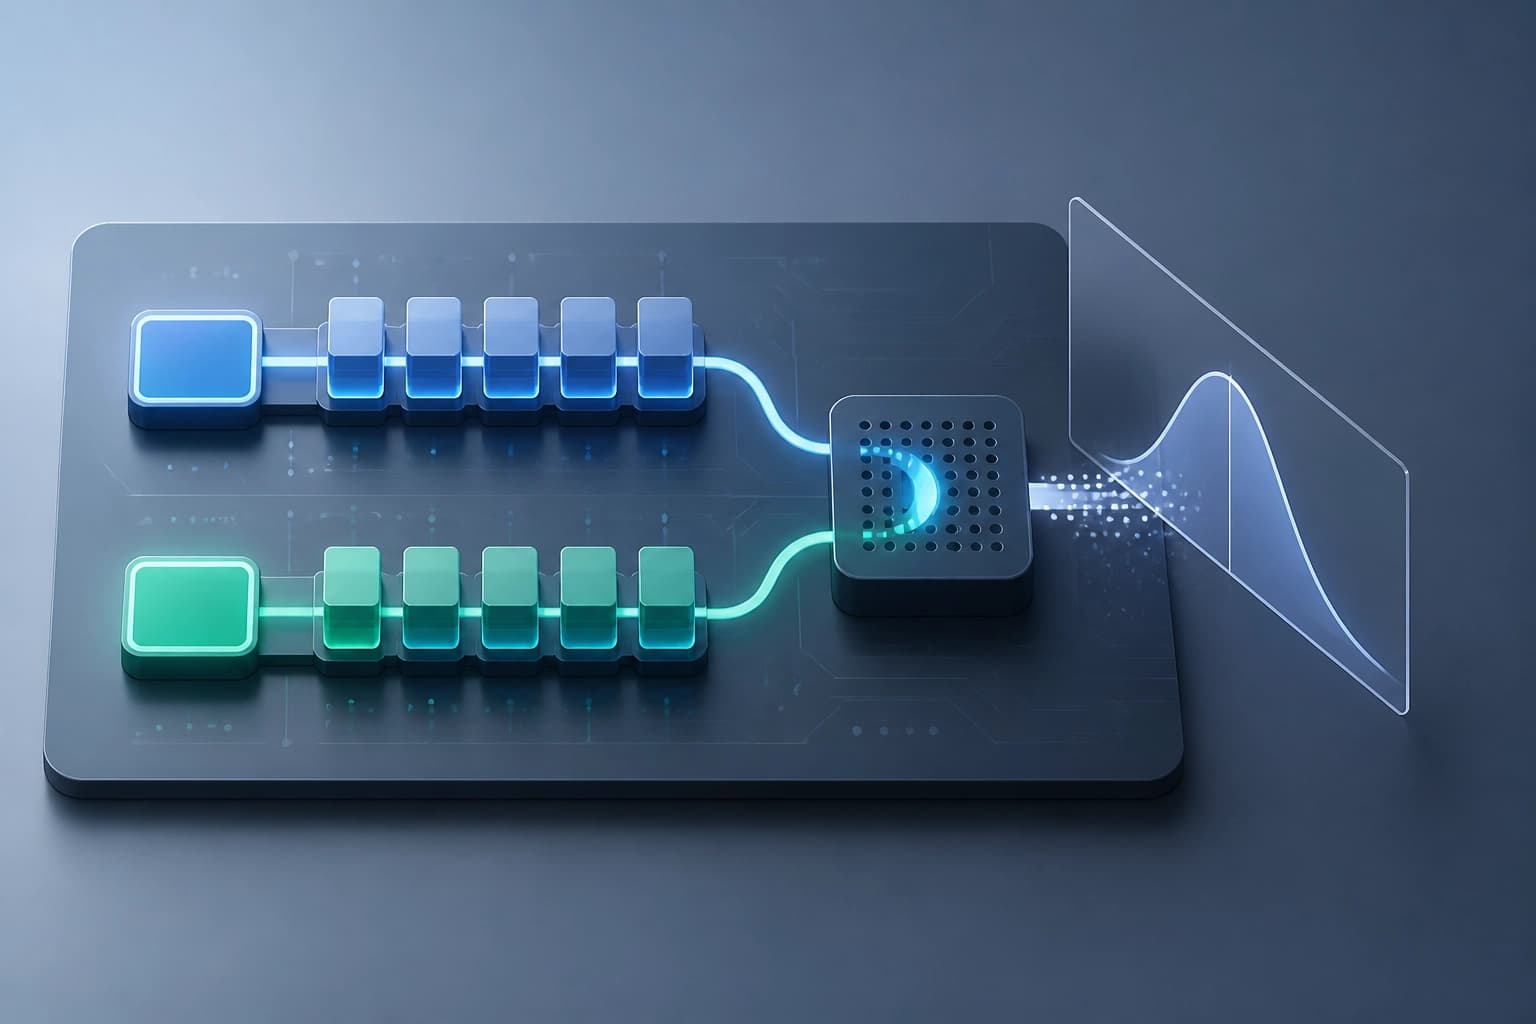
Practical significance: CED is integrated into inference and does not rely on a second model.
Evaluation results
The authors evaluated CED on 7,200 paired trajectories. The benchmarks used were GAIA, SWE-bench, and Multi-Challenge. The evaluation covered three models: Gemma-2 (9B), Llama-3.1 (8B), and Mistral v0.3 (7B).
Key figures:
- reduction in cognitive loafing — up to 33.00% absolute;
- accuracy recovery — up to 30.75%;
- neutralization of architectural and positional biases.
| Model | Behavior when autonomy is restored |
|---|---|
| Gemma-2 (9B) | passive task-focus |
| Llama-3.1 (8B) | active refutation of the simulated swarm |
The authors claim that CED decouples compliance from capability without fine-tuning. Different models exhibit different strategies for autonomy.
Conclusion: the reported effects apply to the listed benchmarks and models.
When to use it
CED is suitable as a zero-shot intervention at the inference stage. The method requires no fine-tuning and does not rely on a secondary model. This separates compliance from capability.
Practical criteria:
- protection against adversarial swarm consensus is needed without further training;
- operation on a single architecture via a dual forward-pass is important;
- toxic consensus tokens need to be suppressed without grammatical collapse;
- evaluation on models sized 7B–9B and the GAIA, SWE-bench, and Multi-Challenge benchmarks is acceptable.
Limitation: the paper reports results for three models and three benchmarks. The paper provides no data beyond this set.