
Problem: an agent trace is a log, not a behavioral model
A multi-step LLM agent leaves behind a long trail: tool calls, intermediate reasoning, corrections, retries. Reading it by eye is nearly pointless — hundreds of lines of text where the useful signal is smeared across the whole volume. For a developer shipping an agent to production, such a log turns into a black box: it's unclear both where exactly the run went off track and which states are even typical for the system.
This is exactly what the paper arXiv:2608.23670 (cs.AI) "Automata from Agent Traces: Failure and Next-Step Prediction" is about — its authors Seonglae Cho, Franklin Cardenoso Fernandez, Umar Mohammed, Zekun Wu, Kleyton Da Costa, Ilham Wicaksono, and Adriano Koshiyama propose looking at traces not as text, but as data about transitions between states. The logic is simple: if an agent's behavior repeats from run to run, then there is structure behind the external chaos, and it can be reconstructed.
It's worth noting separately what previous approaches were missing. Analysis was usually done one trace at a time or relied only on successful runs. In both cases the big picture is lost — the very topology that links next-action prediction and failure prediction. And it is precisely this that is needed both for security auditing and for real-time monitoring.
One automaton for the entire corpus
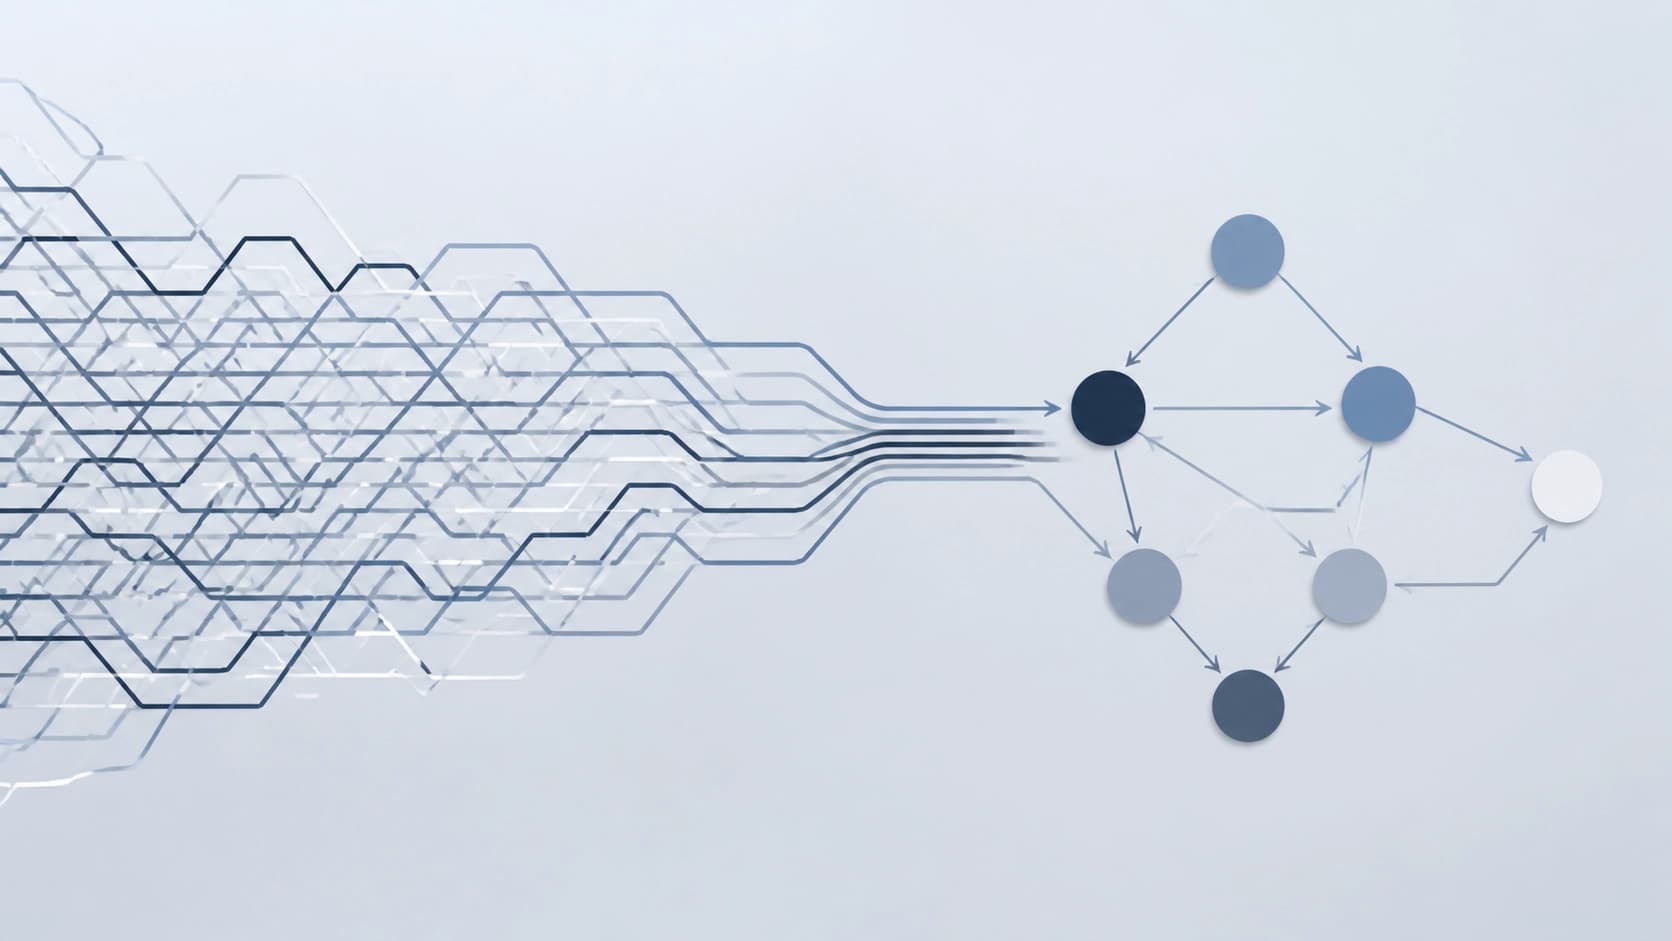
The idea of the method: take the entire set of traces and collapse it into a single compact finite state machine (FSM). Not a decision tree per run, not embeddings somewhere in vector space, but an ordinary graph with states and transitions — the very structural substrate that makes an agent's behavior, if not predictable, then at least describable.
The results on twelve public datasets look encouraging:
- the automata come out small — from 7 to 43 states, meaning they can actually be drawn and discussed on a call;
- on held-out data they reproduce traces with fitness no lower than 0.997 — an almost perfect match;
- the topology built on different splits of the same dataset turns out to be practically identical;
- the assembly itself takes milliseconds, not hours of training.
The last point is more important than it seems. A method that builds instantly can be rebuilt after every change to the prompt or configuration — and you can immediately see whether the system's behavior has changed.
Why this isn't just a pretty visualization
Compactness here is not an end in itself. When you have 20 states instead of thousands of lines of text, it becomes possible to reason about the agent's operating modes: here's the "tried — got an error — retried" loop, here's the "task went into clarifying questions" branch, here's a rare state with almost no exits. From there, these modes can be worked on engineering-wise — for example, building features computed per state.
Next-step prediction: state matters more than memory
To predict the agent's next action, the authors use the context of the FSM state. And this approach beats Agent Workflow Memory on every dataset where the labeling is consistent with the actual execution flow. In other words, knowing "which mode the agent is currently in" turns out to be more useful than accumulated memory of past episodes.
There's an interesting nuance here. State context is not just a node number, but a compressed description of what has already happened and what is likely to happen next. The result is a kind of map of probable continuations, built not on the semantics of the text, but on transition statistics. In practice, this means the next-step predictor can be trained more cheaply: it doesn't need access to the model's hidden states, the structure is enough.
Failure prediction and monitoring on a partial trace
The second half of the work is about diagnostics. Features computed from individual automaton states yield AUROC up to 0.94 on held-out data. That is, a model that knows nothing about the internals of the LLM distinguishes, by behavioral characteristics, runs that will end in failure from those that will make it to the end.
The most practical thing here is the online monitor. It looks at an incomplete trace and ranks failing runs above successful ones without waiting for the finish. That's enough to trigger early stopping long before the agent definitively goes off track: saving tokens, time, and — more importantly — preventing it from causing harm. For agents that write to databases, call payment APIs, or manage infrastructure, the ability to interrupt execution midway is not a luxury but a requirement.
The main takeaway: behavior is set by the harness, not the model
Perhaps the most provocative thesis of the paper goes like this: an agent's behavioral topology is largely determined not by the language model itself, but by the deployment harness — the scaffolding in which the model runs. The prompt template, the tool set, the error-handling rules, the step limits — these are what shape the transition graph.
Several conclusions follow from this. First, swapping the model for another with the same harness may not radically change the structure of behavior — which means an automaton built on one model is worth testing on another. Second, improving an agent is often more effective through changes in the harness rather than through upgrading the weights. Third, a model-agnostic structural primitive emerges: the same approach works for security auditing and for runtime monitoring regardless of whose API you're calling.
What to keep in mind
The approach doesn't remove the need for caution. Twelve datasets is still a limited sample, and a fitness of 0.997 says how well the automaton describes already-collected traces, not that it will predict the system's behavior in an unfamiliar environment. The high AUROC for failure prediction was also obtained on specific tasks: in new domains the features will have to be recomputed.
And yet the direction looks sound. Instead of endlessly increasing the context window and hoping the model "figures it out on its own," you can build a compact behavioral model of your harness once — and then use it as a map: see where the agent gets stuck, which states lead to failure, and what will change if you adjust the configuration. The automaton isn't smarter than the LLM, but it's more honest: it can fit entirely in your head, and that's already half the battle in debugging.


