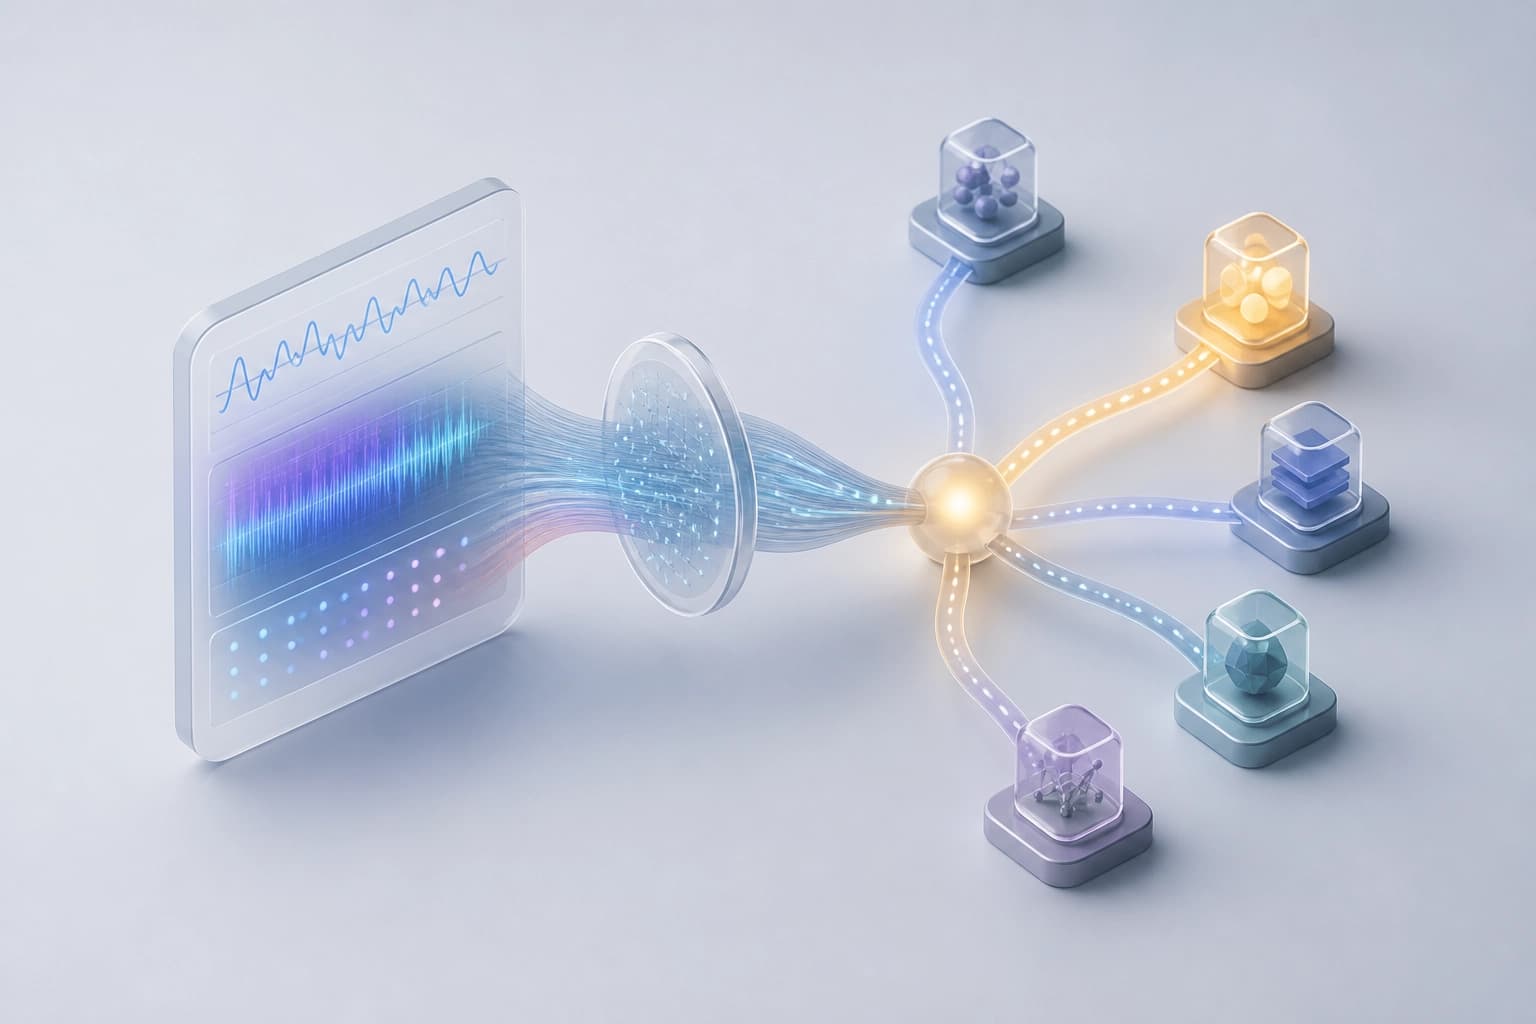
What the Router Receives
In MoE language models, the router selects experts and assigns them weights based on a token's hidden state. In doing so, it uses limited contextual information.
Attention-Aware Routing (AAR) supplements this signal with temporal and spectral features. These are extracted from a sliding window of attention weights.
- Standard routing relies on the token's hidden state.
- AAR adds attention features that summarize the contextual state separately from the hidden state.
Practical criterion: when analyzing expert selection, distinguish between the token signal and the additional context summary.
How AAR Works
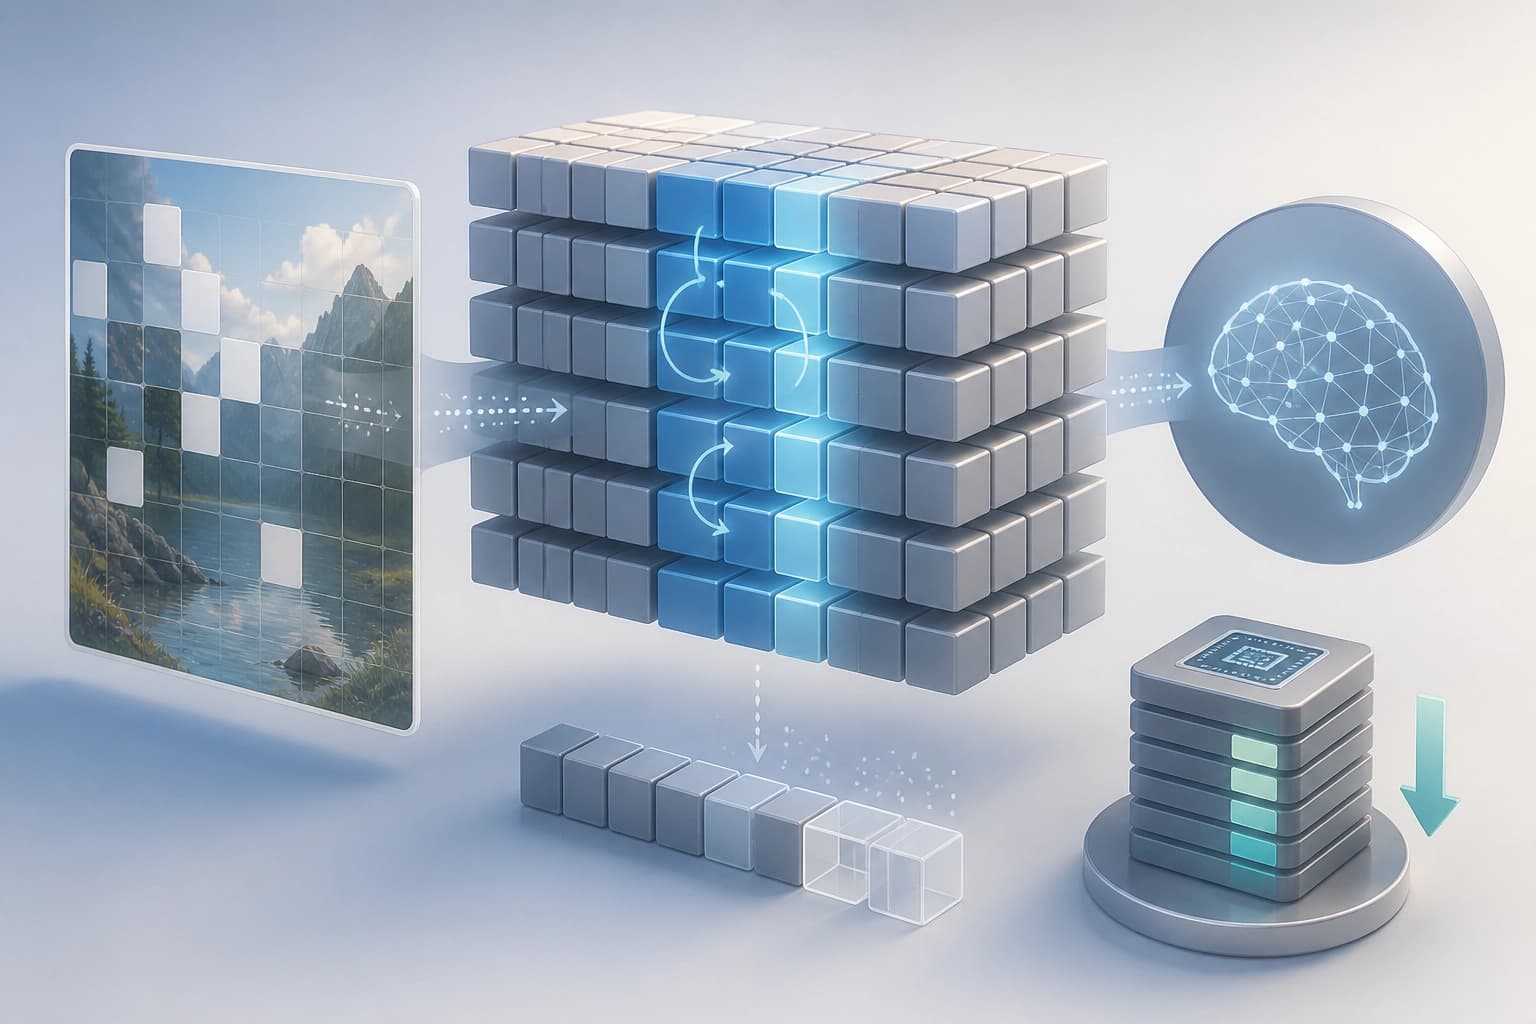
AAR obtains temporal and spectral features from a sliding window of attention weights. This allows the router to use a context signal separate from the token's hidden state.
The authors keep the base transformer completely frozen and train only the routing parameters. This makes it possible to study routing as the sole variable that changes.
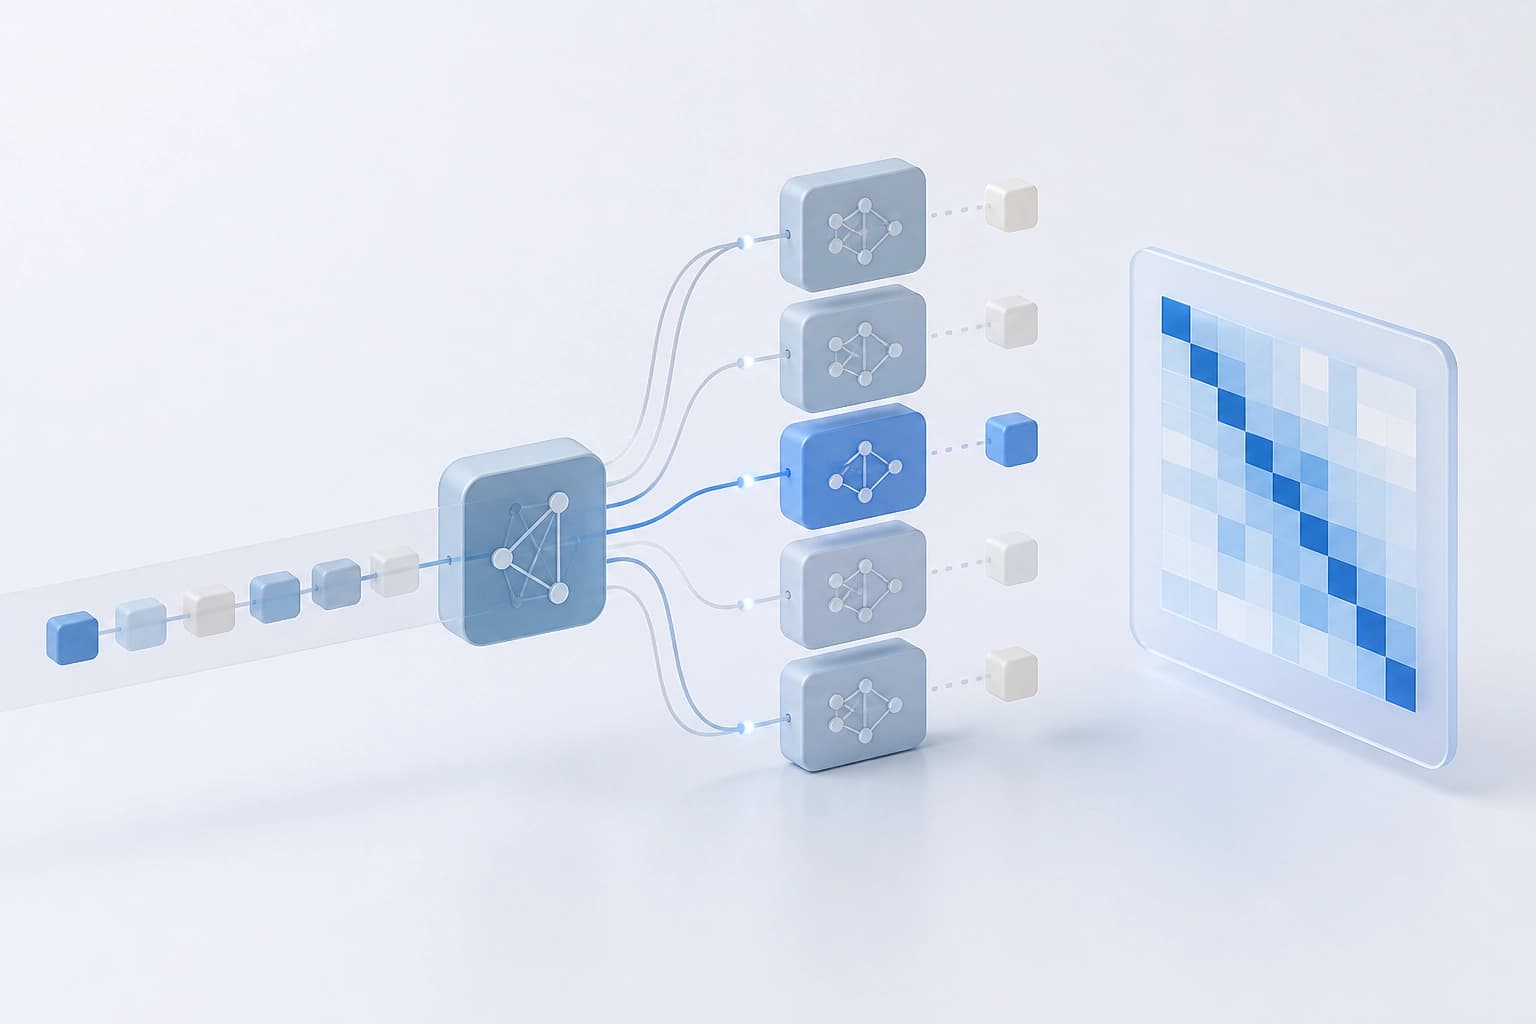
The method's evaluation criterion is to separate the effect of routing from changes to the model's other parameters.
Why Routing Changes Attention
Routing and attention are connected through the sequence of layers. Routing changes at layer l pass through the residual stream and amplify attention sinks at layer l+1.
This changes attention without directly updating its mechanism. This means expert selection can affect subsequent context processing.
When analyzing the results, it is important to account for this connection: attention here is not only an input signal for the router, but also part of the chain of consequences of routing.
What the Results Showed
On OLMoE, AAR improved the GSM8K score by 3.37 percentage points compared with the baseline SFT variant using routing only.
| Metric | AAR Result |
|---|---|
| GSM8K | +3.37 percentage points compared with the baseline |
| Incorrect answers | Became shorter in long divergent generations |
| Correct answers | Length did not change |
These results describe a specific evaluation. They do not show that AAR has the same effect on all tasks.
When comparing variants, consider task performance and generation length separately: these metrics changed differently.
Why It Matters Which Layers AAR Is Applied To
The effect of AAR depends on depth. Applying it indiscriminately across different layers can reduce factual retrieval quality.
When applied at deeper layers, the benefits for mathematical reasoning are retained. This reveals a trade-off between information retrieval and reasoning at different depths.
- To evaluate factual retrieval, it is important to check whether applying AAR across different layers degrades it.
- For mathematical reasoning, it is important to consider the results at deeper layers.
- Selective application makes it possible to investigate what routing information attention carries at each depth.
A practical criterion is to evaluate layers separately rather than assume the attention signal is equally useful throughout the model's depth.