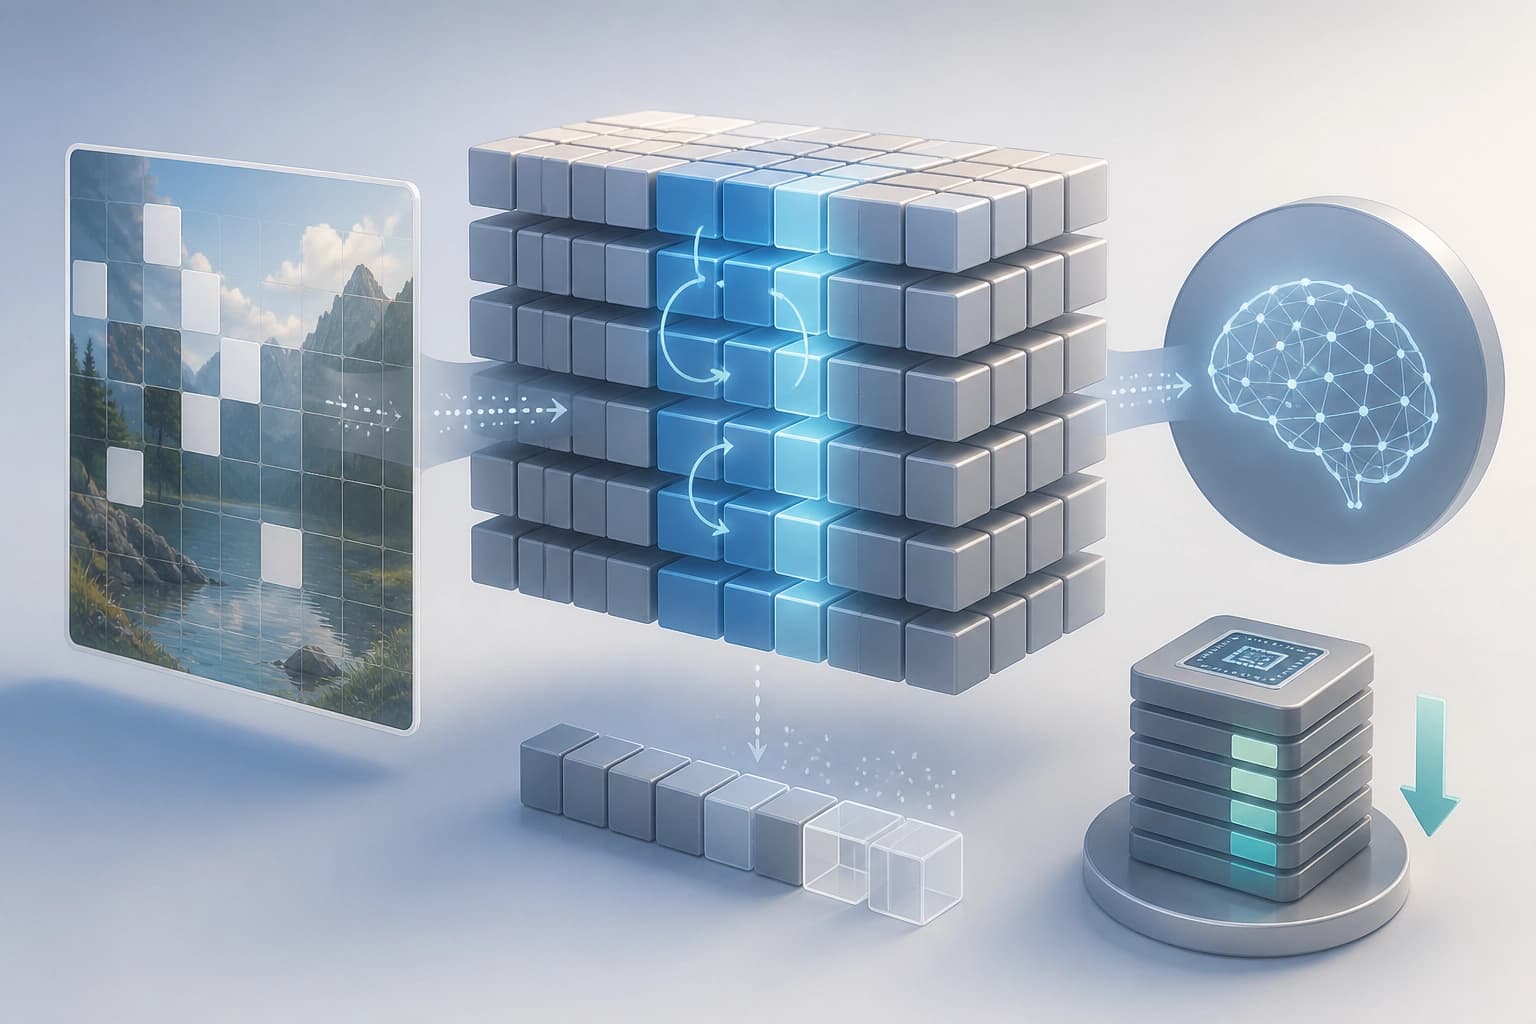
What LocalProp changes
LocalProp is a training procedure that updates model weights locally. The authors contrast it with backpropagation through the entire model. A full pass is not consistent with biologically plausible learning. It is also memory-inefficient. Learning in the brain is highly localized.
| Criterion | Backpropagation through the entire model | LocalProp |
|---|---|---|
| Weight updates | Pass through the entire model | Local |
| Biological plausibility | Not consistent | Draws on localized learning in the brain |
| Memory | Inefficient | Uses only a fraction of peak GPU memory |
| Control | No separate parameter | Number of jointly optimized blocks |
Takeaway: LocalProp replaces a full pass with local updates. This reduces memory load.
Training stages
LocalProp follows a “pre-training then fine-tuning” scheme. The stages are arranged in sequence.
- Pre-training on I-JEPA.
- Local weight updates.
- Pruning.
- Short final fine-tuning.
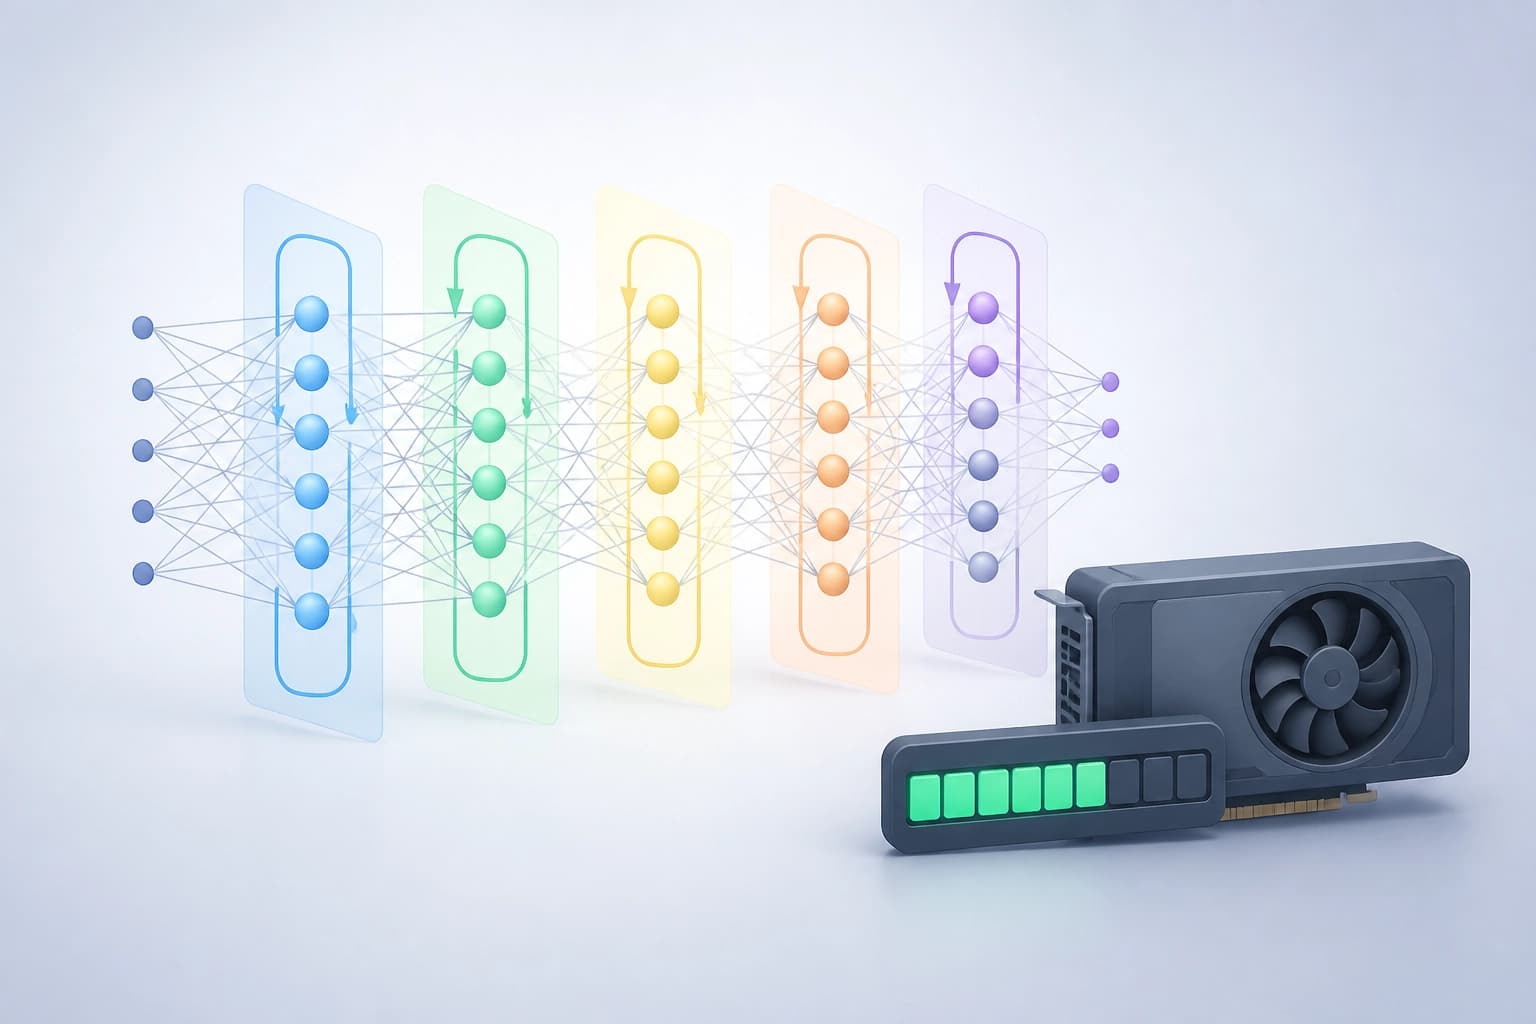
Takeaway: The scheme combines pre-training, local updates, pruning, and final fine-tuning.
The role of pruning
Pruning passes the training signal from upper blocks to lower ones. This step is not simply model compression. It connects upper and lower blocks during training. Takeaway: In LocalProp, pruning acts as a signal transmission channel between blocks.
Accuracy-memory trade-off
The number of jointly optimized blocks determines the gradient propagation length. The authors define this length as a practical parameter. The parameter controls the trade-off between accuracy and memory usage.
- What changes: gradient propagation length.
- What it controls: the balance between accuracy and memory.
- How it is used: through the number of jointly optimized blocks.
Takeaway: Tuning the number of blocks provides a control for balancing the two.
Results and selection criteria
The authors conducted experiments on several datasets. These included large-scale benchmarks, including ImageNet. LocalProp achieves good results while using only a fraction of peak GPU memory. The specific fraction is not stated in the text. Practical criterion: LocalProp is suitable when full backpropagation runs into GPU memory limits. The number of jointly optimized blocks makes it possible to tune the balance.