
Semantic drift in code from LLMs: what the new SA-Bench benchmark measures
LLM-based agents can write code inspired by scientific publications, but they often produce implementations that only superficially resemble the original. The SA-Bench diagnostic benchmark breaks down 30 papers from ICLR, ICML, and NeurIPS 2025 into atomic implementation claims and shows how far generated repositories drift from the authors' intent.
Problem: code that runs but does the wrong thing
Agents based on large language models can already take a research paper and produce a working repository from it. The problem is that "working" and "reproducing" are not synonyms. A script can successfully pass all tests, train a model, and print a beautiful metric, while inside it the order of steps has been imperceptibly swapped, a multiplier in the loss function has been lost, or a stub has been substituted in place of a non-trivial stage.
It is precisely this failure mode that the authors of a new paper call semantic drift: the generated code quietly diverges from what is described in the paper's specification. The error does not catch the eye — it lives in the details that no one checks automatically. The result is a reproduction that formally took place but scientifically confirms nothing.
What SA-Bench is
To measure drift, it first has to be made observable. This is the job of SemanticAlign-Bench, or SA-Bench for short — a diagnostic benchmark described in the paper arXiv:2608.24252 (accepted to Findings of EMNLP 2026, authored by Xue Hu, Zewei Pan, Zeli Su, Zhou Liu, and Wentao Zhang).
The material covers 30 papers from the ICLR, ICML, and NeurIPS 2025 conferences and is distributed across five areas of machine learning. What is evaluated is not a "feeling" about the code but a set of verifiable claims. In total, the benchmark contains 1,491 such claims.
Semantic Alignment Units: atoms of the specification
The key methodological idea is to break the paper's description down into the smallest elements that can be verified against the repository by hand. These elements are called Semantic Alignment Units (SAUs). Each unit is a separate claim about the implementation: a specific hyperparameter, a formula, an order of operations, a stopping condition, a data-splitting scheme.
This granular approach matters because it strips the evaluation of its "worked / didn't work" binary quality. Instead of a single checkmark per paper, there are a hundred small questions, and you can see exactly where the implementation fell short.
Four dimensions of drift
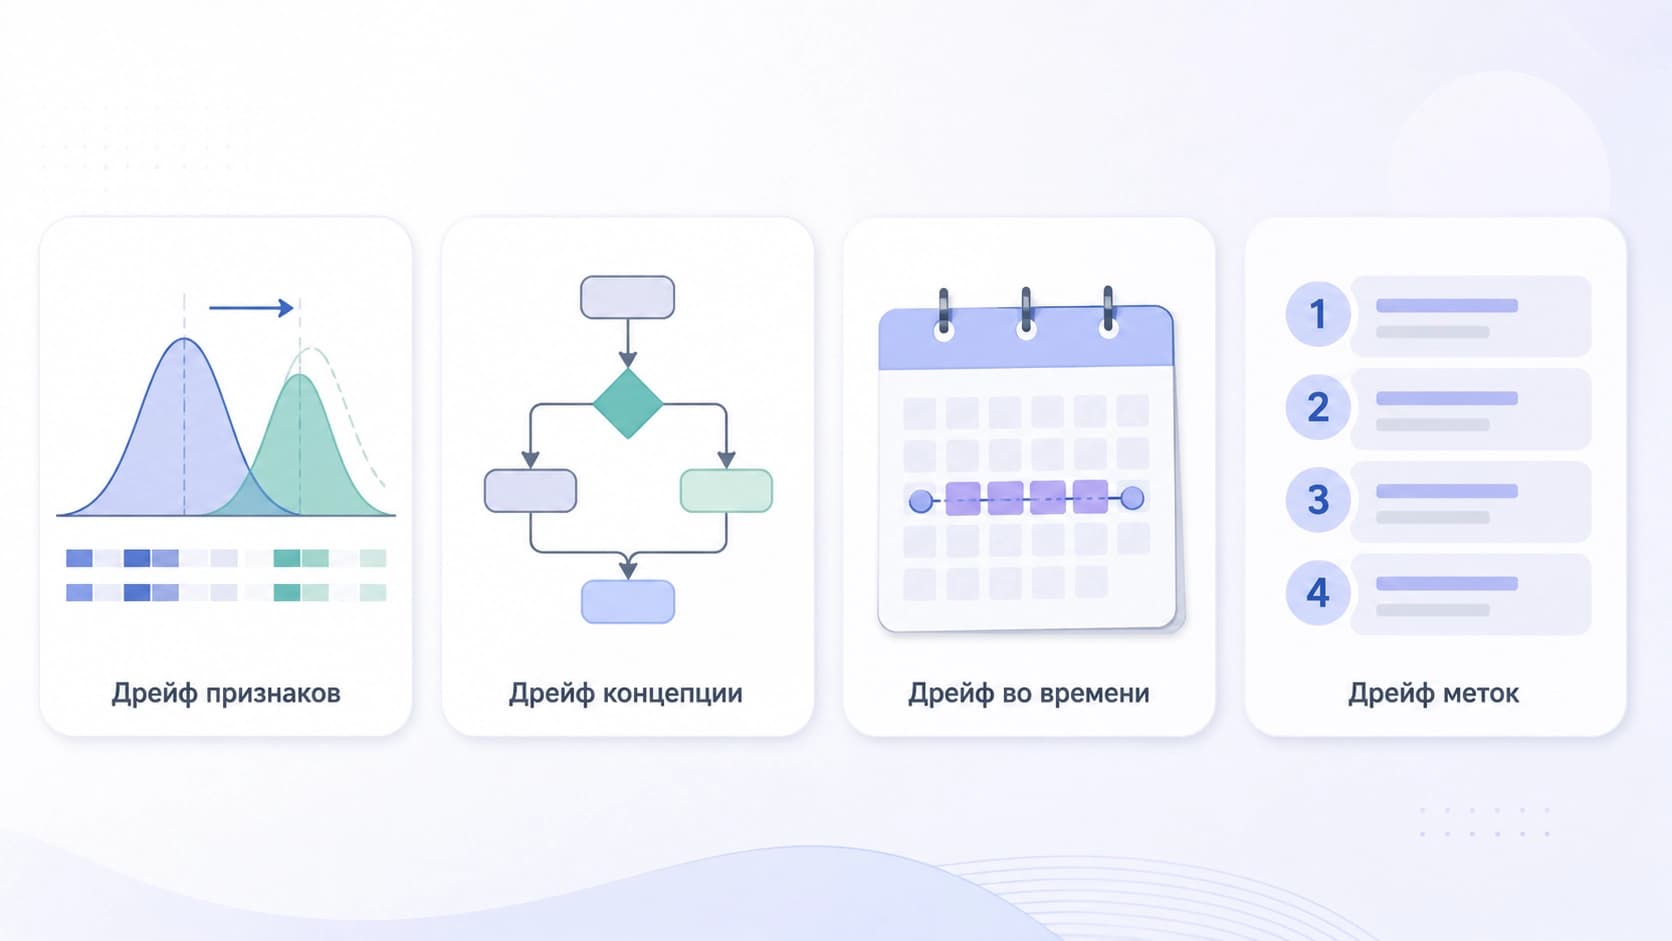
Each repository is evaluated along four diagnostic axes:
- numerical drift — the values of coefficients, dimensionalities, thresholds, and other quantities do not match the specification;
- methodological drift — the training or computation procedure itself is structured differently from what the paper intended;
- protocol drift — the experimental scheme is violated: sample splitting, comparison conditions, evaluation protocol;
- order drift — steps are performed in the wrong sequence, and this changes the result.
Separating the axes has practical value: the developer sees not an abstract "quality is low" but a specific type of breakage.
Results: 0.301 as the ceiling
The authors ran 12 generator configurations — four models in combination with three scaffolds. Each score was measured as a fraction of one.
The numbers turned out sobering. The best result came from the pairing of Claude and PaperCoder — an average of 0.301 SAU points out of a possible 1.0. The overall average score across all 360 evaluations was 0.221.
In other words, even the strongest configuration correctly fulfills less than a third of what the specification requires. At the same time, the models do not ignore the requirements: the failure taxonomy shows that agents usually try to cover most of the points but implement them incorrectly. The bulk of the zeroed-out claims come from two scenarios — implementation mismatch and stubs, that is, places where empty formality is left in place of real logic.
This error profile points to something important: it is not a matter of the agent's laziness or of its having "not finished reading" the paper. It is that it confidently reproduces a plausible but incorrect version.
Executability is not the same as scientific fidelity
A separate conclusion of the paper concerns how modern scaffolds are built. Those optimized for executability — so that the code simply runs and doesn't crash — yield limited gains for scientific reproduction. This makes sense: a successful run verifies syntax and the presence of dependencies but says nothing about whether the logic matches the authors' intent.
To close the gap, scaffolds of a different class are needed — ones that put the verification of semantic specifications front and center. Put simply, an agent needs not just to write and run code but to check each of its steps against a claim from the paper and be able to prove that they match.
What this changes in practice
SA-Bench is not a model competition but a diagnostic tool. Its value lies in moving the discussion of reproducibility from the plane of "works / doesn't work" to the plane of "how accurately does it match." The benchmark, annotations, and evaluation pipeline are publicly available, so the methodology can also be applied to your own tasks — for example, to check internal code-generation pipelines against technical specifications rather than just research papers.
For those building agents, the takeaway is this: increasing the generator's "smartness" without a separate verification layer hits a ceiling. Semantic drift is not a bug of a particular model but a property of an approach in which no one checks semantic correspondence. And until such a layer appears, reproducing research code will remain a task where a human still has to read every line.
Frequently asked questions
Related materials
All materials
Toollery: Choose tools for LLM agents from tens of thousands of options without fine-tuning
Toollery builds a search index from descriptions of skills and tools, then passes the model only a limited set of candidates for each query. In experiments with libraries containing tens of thousands of functions, the approach helps maintain selection quality at a fixed top-K, although the overall effect depends on the workload profile and the provider’s caching.
11 November 2026
Step-by-Step Evaluation of GUI Agents for Dashboard Analysis: The DashAct Benchmark
Introducing DashAct, a benchmark of 348 human-verified trajectories that breaks down GUI agents’ work with interactive dashboards into three stages and four visual conditions. The results reveal persistent issues with action prediction and visual target grounding, as well as agents’ reliance on contextual and spatial support.
11 November 2026
WILSON: combining magnifications and patient slides for pathomorphological analysis and report generation
The preprint introduces WILSON, a vision-language model that encodes images of whole slides and series of slides from a single patient at different magnifications, rather than just a single “best” slide. Without task-specific fine-tuning, it outperforms specialized and larger slide models on a range of metrics while requiring substantially less compute, and its diagnostic descriptions received higher ratings from pathologists.
11 November 2026