What exactly is reused
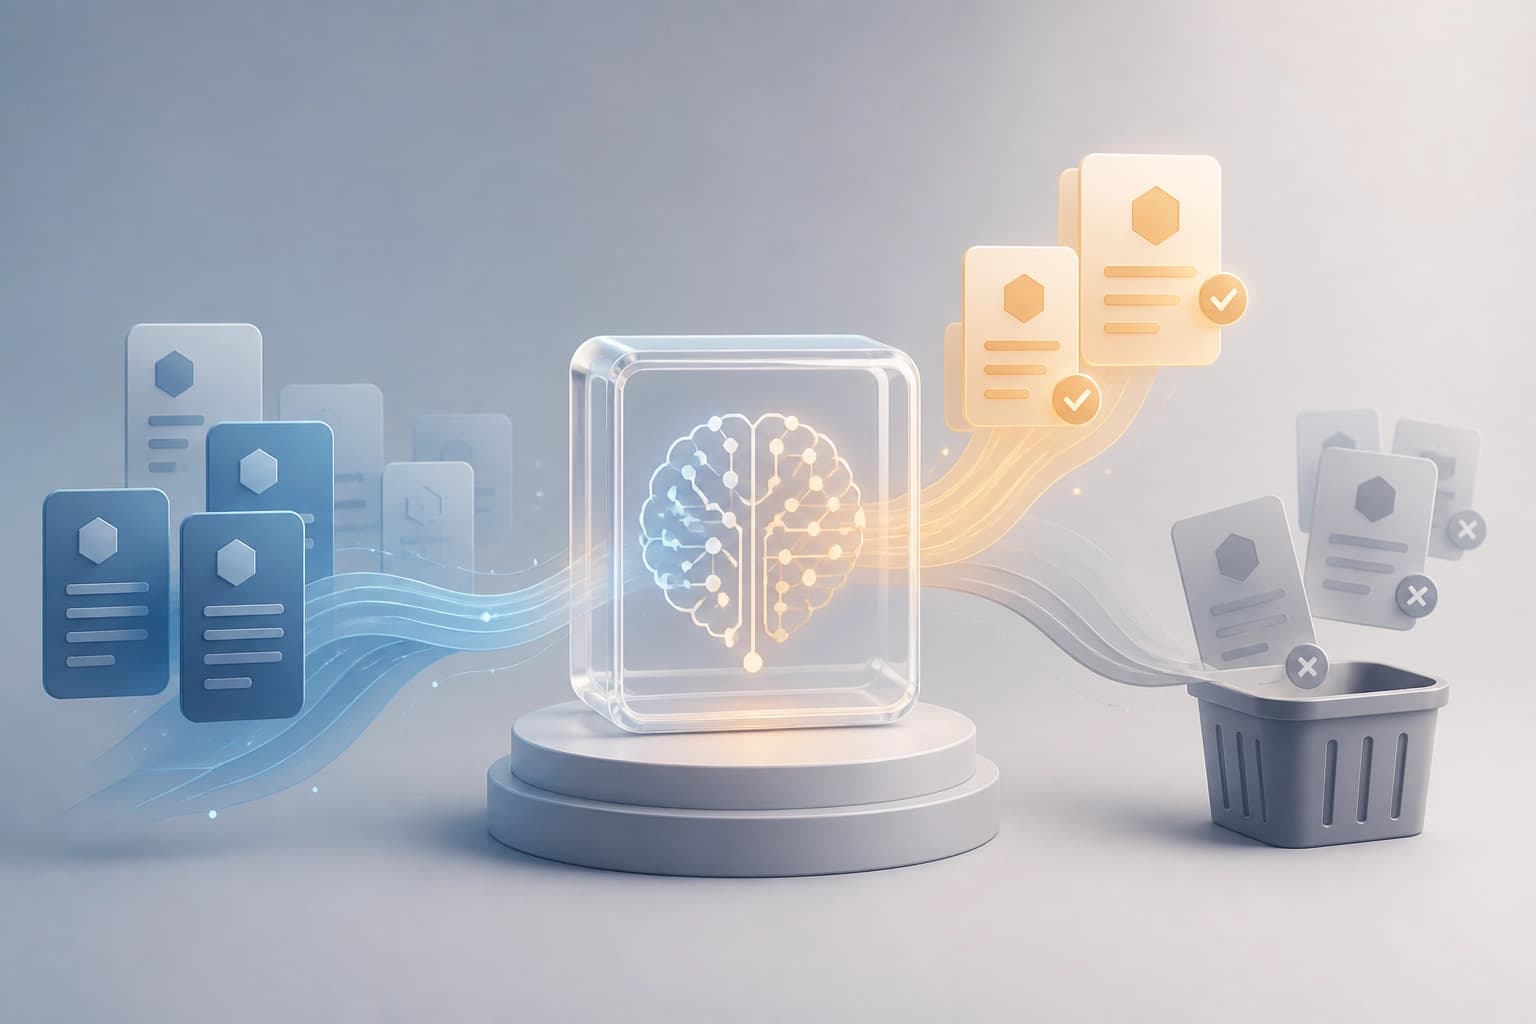
In standard GRPO, each rollout is used in one gradient update and then discarded. The method described in the paper changes this cycle: it retains individual rollouts and returns selected ones to training.
The buffer stores individual generations, not entire groups. Replay prioritizes them by advantage magnitude: rollouts with higher values are reused.
A practical criterion: this is about reusing individual rollouts, not groups.
How replay works
Each batch is formed in two stages:
- Fresh on-policy rollouts are included.
- Separately selected rollouts from the buffer are added.
Replay items are selected based on the advantage magnitude of each rollout. The reported facts do not specify the share of replay items in a batch.
The key difference is that fresh rollouts remain in the batch, while the buffer supplements them with selected generations.
How staleness is limited
The authors note a problem with naive replay: LLM policies change quickly with each gradient step. Stored rollouts can become stale and destabilize training.
The method removes any rollout from the buffer that is older than tau_max training steps. This sets a retention limit, but does not eliminate reuse itself.
The control criterion here is the age of an individual rollout in training steps, not its membership in a group.
What the evaluation showed
The method was tested at three Qwen3-Base scales and on five math benchmarks. It outperformed GRPO and naive replay baselines.
- At every scale, the gain in the average across the five benchmarks was positive.
- At the 4B scale, the gain reached +1.66 pp.
- On AES, a joint measure of accuracy and token efficiency, the method was the only option to outperform GRPO at every scale.
The practical selection criterion depends on the target evaluation: the results cover accuracy, token efficiency, and comparison with two baselines.