
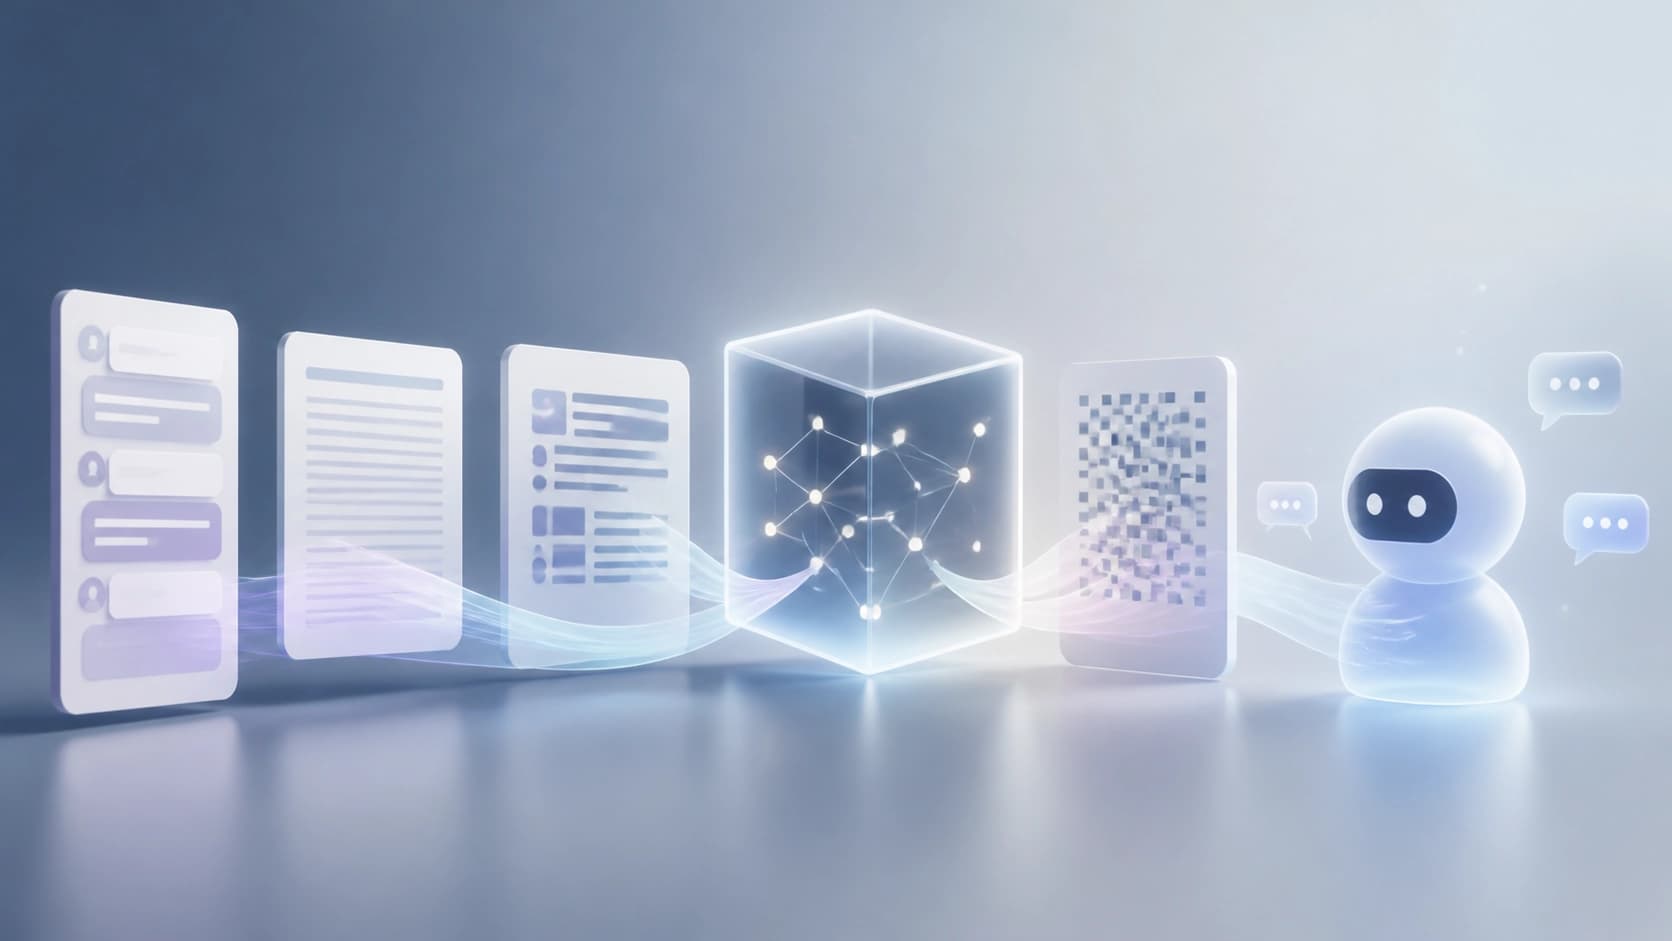
Why the presentation format is not an implementation detail
When we test a language model's memory or the quality of a RAG pipeline, we usually care about exactly one thing: did the model get to the right fact. But the form in which that fact ended up in the input context — a separate memory entry, a compressed summary, a structured record with fields, or a raw chunk of conversation — is typically treated as an internal matter of the system. The logic is simple: if the fact is there, it doesn't matter how it's packaged.
The authors of the preprint arXiv:2608.23568 propose to disagree. Their work "RENDER: Controlling Reader-Facing Evidence in LLM Memory Evaluation" (Yuan Si, Simeng Han, Daming Li, Jialu Zhang; v1 dated June 5, 2026) strikes at the very idea that memory has one honest and universal evaluation. Instead, they propose measuring it the way other configuration-sensitive properties are measured: fix one variable and iterate over the values of the other.
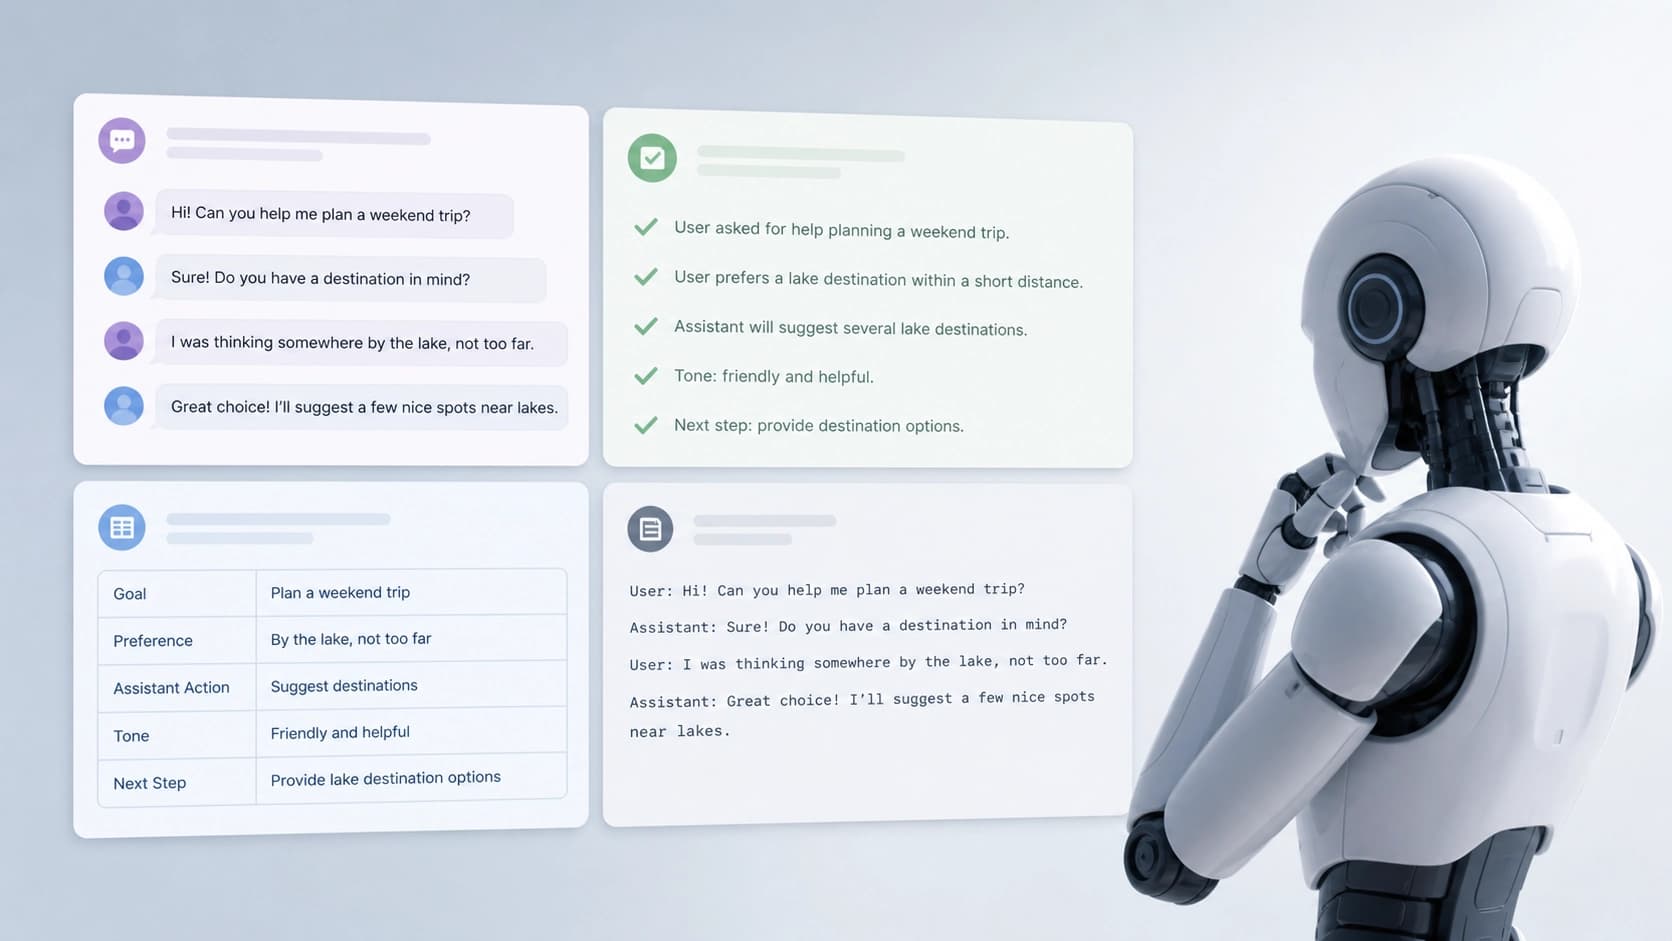
What exactly RENDER controls
The dialogue doesn't change. Only the reader-facing artifact changes: what the responding model actually sees in front of it. It is precisely this layer — the reader-facing artifact — that RENDER turns into a controlled variable.
A ladder of five levels
The core of the methodology is the five-level packet ladder. This is not just a set of formats, but a scale that localizes the moment when the answer-bearing content enters the responding model's input. The point is to separate two fundamentally different failures: the system didn't find the right fact, and the system found it but couldn't convey it in a usable form. Without such a scale, these cases merge into a single line of the report, and then incorrect conclusions follow — for example, that the model "remembers poorly," when in fact it simply couldn't parse the packaging.
Four presentation templates
The second element is deterministic templates that approximate typical ways of showing history to a user. There are four of them:
- ChatGPT-style entries — neat blocks similar to what a person sees in a chatbot interface;
- LangChain-style summaries — compressed retellings that lose the wording but preserve the gist;
- MemGPT-style typed records — a structure with fields and categories, convenient for machine processing;
- raw dialogue — utterances as they are, without markup or repackaging.
The templates are deterministic: the same input produces the same text every time. This matters because otherwise it would be impossible to distinguish the effect of format from random generation variance.
What the numbers showed
The experiment relies on 500 questions from LongMemEval and nine models. It's worth pausing here: this is not a single run or a single pass for a pretty number, but a "model × presentation format" grid, which is what makes the effect visible.
The main result: matched-budget resolved packets beat recency-truncated raw dialogue by 42.4–72.6 points. In other words, if you bring the formats to a comparable budget and give the model content that actually carries the answer, the gap with the most naive presentation method — raw dialogue truncated by recency — turns out to be not cosmetic but precipitous.
In deployed-style templates the picture is milder, but still substantial: the spread between the best and worst format is 24.6–48.8 points for each of the nine models. That is, within a single model, on the same questions, at the same budget, you can "lose" or "gain" dozens of points simply because of how the evidence looks.
Another detail from the primary scoring: in 7 of 9 models, ChatGPT-style entries receive higher point estimates than raw dialogue. This is perhaps the most inconvenient conclusion for those who build metrics on "clean" conversation history.
The judge is not the ultimate truth either
A separate storyline is what happens if the scores are recalculated not by an automatic scorer but by a judge model (judge rescoring). The aggregated positive effect of format persists, but significance across individual models becomes mixed. Put simply: the trend at the level of the whole sample doesn't disappear, but point claims like "model X wins specifically thanks to format Y" are no longer as reliable after re-judging.
This is not a reason to abandon LLM judges, but a good reminder: any memory evaluation is itself a measuring instrument with its own sensitivity to input format. And if the system and the judge react differently to the packaging of evidence, the difference can go into noise or, conversely, into a false signal.
The most striking result: zero versus fifty
If you take one number from the paper, take this one. Three models that showed 0% on formal ledger packets answered the same facts from natural-language entries with an accuracy of 45.4–53.4%.
Not "a bit better," not "within the margin of error" — from a complete zero to a confident hit in half the cases on identical content. Such a gap is hard to explain by the model's lack of knowledge or poor retrieval: the facts were there, only the way they were presented changed. A formal, machine-readable record somehow turned out to be impassable for the model, while the same information stated in plain language was read without problems.
For an engineer, this is a practical signal: if your pipeline stores memory in strict structured blocks, you may be systematically underestimating the model's capabilities — and at the same time overestimating the benefit of formalization.
How robust this is
The effect doesn't fall apart when conditions get more complex: it persists under retrieval noise, that is, when extra fragments are mixed into the context. Moreover, it carries over to HotpotQA — a different dataset built around multi-hop questions. This matters because it removes the suspicion that it's all about the specifics of a single long-memory benchmark.
The limitations are also worth keeping in mind: the templates approximate real presentation methods rather than reproducing them literally, and the conclusions for individual models after re-judging are mixed. So this is not about ready-made recipes, but about the need to notice this variable at all.
What to do about this in practice
The authors' conclusion is fairly direct: reports on memory/RAG evaluation should either state which reader-facing artifact was used or explicitly control it. Below is what this looks like in applied terms:
- Fix the format in the test description. "We ran the model on LongMemEval" is an insufficient description if it doesn't say in what form the history entered the input.
- Run at least two or three formats. One good and one naive (for example, raw truncated dialogue) will already give you a sense of your system's sensitivity.
- Don't compare models against each other on different packaging. A difference of 20–30 points may belong entirely to the format, not the model.
- Check your structured memory schemas. A zero on a formal record with confident answers to the same fact in plain text is a presentation bug, not a memory bug.
- Test the "model-judge" channel separately. If the evaluator is itself sensitive to format, the metric becomes biased.
- Account for the cost of the format. Summaries and typed records save tokens; now this has a measurable downside, and it's worth weighing it consciously.
RENDER's main point is simple and therefore inconvenient: "evaluating a model's memory" without specifying how the evidence is presented is an incomplete claim. The same dialogue, the same questions, the same model, but different answers. The difference lies in how you showed it what it was supposed to remember.


