
OpenCollab: programmable agent coordination, controlled execution environment, and policy compliance metric
The framework brings together the specification of agent interaction structures, a shared environment for experiments, and detailed event tracing, while the newly introduced Adherence metric reflects how closely actual execution follows the declared schema. In benchmarks, the Duo configuration achieves a new state of the art, while the single-agent variant uses the fewest tokens.
Purpose of the Framework
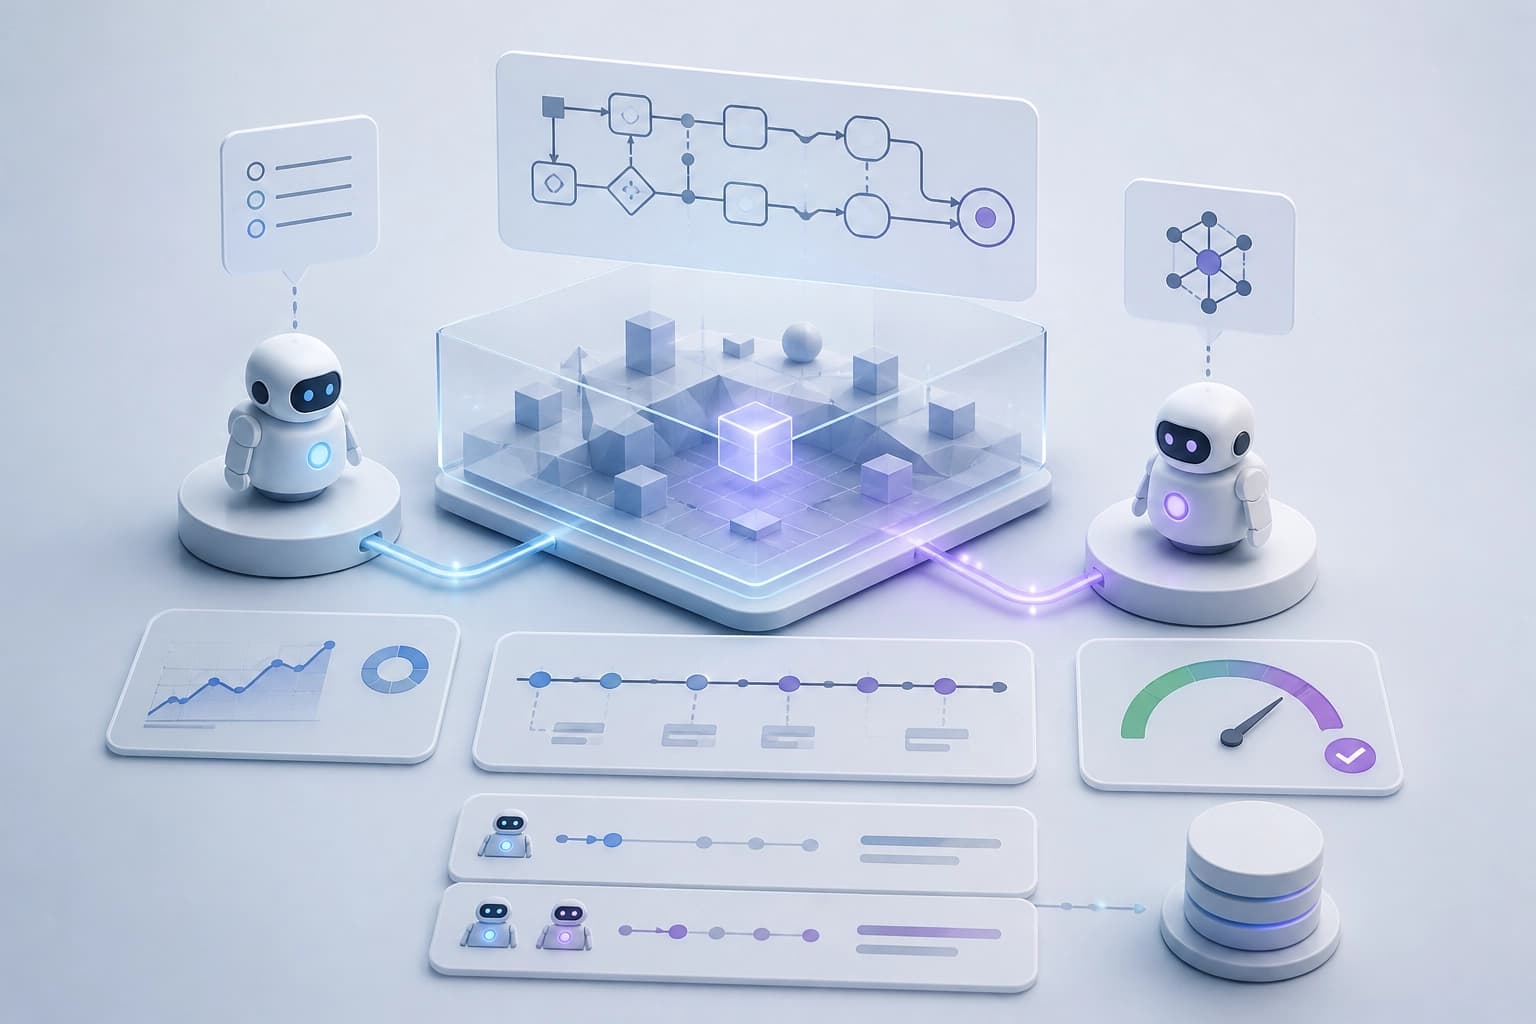
OpenCollab is a framework for multi-agent development. It provides unified infrastructure for programmable interaction and a controlled execution environment.
Key elements:
- multi-agent development;
- programmable agent interaction;
- controlled execution environment.
Practical takeaway: the framework is useful when agent coordination needs to be defined programmatically and run in a controlled setting.
Agent Organization as a Design Object
OpenCollab combines the design of agent organization with execution. Organization becomes part of the configuration rather than an external description.
What the design covers:
- the composition of the agent organization;
- the specified interaction structure;
- the connection between structure and execution.
Criterion: the organization must be described in a way that makes it reproducible. Otherwise, the design remains a declaration.
Controlled Execution Environment and Observability
OpenCollab provides experimental control in a shared execution environment. The environment keeps agents within a single setup.
What the environment provides:
- shared execution conditions for the configurations being compared;
- experimental control;
- detailed event streams.
Practical criterion: without a shared environment and event streams, comparing configurations is not reproducible.
Adherence: A Metric for Protocol Compliance
The authors of OpenCollab introduce Adherence. This metric measures how closely the declared agent organization is implemented in practice.
What the metric captures:
- the declared agent organization;
- actual execution;
- the gap between them as a percentage.
In experiments, changing any single configuration dimension shifted Adherence. The metric ranged from 47.2% to 97.2%.
Practical criterion: Adherence shows the gap between the declared organization and actual execution. The metric is evaluated alongside the final results.
Results on Agentic Development Benchmarks
On agentic development benchmarks, OpenCollab (Duo) achieved a new SOTA. The authors compared it with Mini-SWE-agent, OpenHands, Codex CLI, and Claude Code.
According to the authors’ results, a well-designed agent organization can outperform strong existing harnesses. The single-agent OpenCollab configuration used the fewest tokens across all evaluated test suites.
| Participant | Result |
|---|---|
| OpenCollab (Duo) | New SOTA on agentic development benchmarks |
| Mini-SWE-agent | Included in the comparison |
| OpenHands | Included in the comparison |
| Codex CLI | Included in the comparison |
| Claude Code | Included in the comparison |
| Single-agent OpenCollab configuration | Fewest tokens across all evaluated test suites |
Selection criterion: compare not only the top SOTA result, but also the token usage of the specific configuration.
Practical Selection Criterion
Start by checking whether agent coordination can be defined programmatically. Then check whether the framework measures adherence to the declared organization. OpenCollab provides Adherence and a shared execution environment for this purpose.
Selection checklist:
- Programmable agent coordination.
- Availability of the Adherence metric.
- Shared execution environment and event streams.
- Comparable results on agentic development benchmarks.
- Token usage of the selected configuration.
The framework is a good fit if all five points are verifiable. If any point cannot be verified, the choice lacks a sound basis.
Frequently asked questions
Related materials
All materials
Toollery: Choose tools for LLM agents from tens of thousands of options without fine-tuning
Toollery builds a search index from descriptions of skills and tools, then passes the model only a limited set of candidates for each query. In experiments with libraries containing tens of thousands of functions, the approach helps maintain selection quality at a fixed top-K, although the overall effect depends on the workload profile and the provider’s caching.
11 November 2026
Step-by-Step Evaluation of GUI Agents for Dashboard Analysis: The DashAct Benchmark
Introducing DashAct, a benchmark of 348 human-verified trajectories that breaks down GUI agents’ work with interactive dashboards into three stages and four visual conditions. The results reveal persistent issues with action prediction and visual target grounding, as well as agents’ reliance on contextual and spatial support.
11 November 2026
WILSON: combining magnifications and patient slides for pathomorphological analysis and report generation
The preprint introduces WILSON, a vision-language model that encodes images of whole slides and series of slides from a single patient at different magnifications, rather than just a single “best” slide. Without task-specific fine-tuning, it outperforms specialized and larger slide models on a range of metrics while requiring substantially less compute, and its diagnostic descriptions received higher ratings from pathologists.
11 November 2026