
ExeFuse: Shared Knowledge Graphs Come to the Aid of Highly Specialized Ones
Domain-specific knowledge graphs suffer from incompleteness, while transferring facts into them from general-purpose bases is hindered by fuzzy domain relevance and differing levels of granularity. A team of authors proposed the DKGF fusion task and a neuro-symbolic framework, ExeFuse, which verifies the logical appropriateness of facts and adjusts them to the required granularity.
Domain knowledge graphs hit a coverage ceiling
Industry knowledge graphs are a useful and at the same time finicky thing. A medical ontology, a catalog of industrial parts, a database of regulations: these are all precise structures vetted by experts, where the relationships between entities have a clear meaning. The price of precision is narrowness. Such a graph knows only what has been entered into it, and it hits the ceiling of its own coverage.
General knowledge graphs are built differently. They collect facts from all over the world, but they do so crudely and without regard for any specific subject area. It is precisely on this contrast that the study we are about to discuss is built.
Until now, the enrichment of domain graphs has followed two paths. Either knowledge was extracted from external unstructured texts — documents, articles, reports — or the graph was extended from within, through logical inference over existing connections. Both approaches work, but they do not raise the bar: coverage remains limited, and the quality of integration is unstable.
And most importantly, no one had really studied the question systematically: how to use truly large and high-quality general knowledge graphs to supplement highly specialized ones. This is the gap that the work arXiv:2601.10485 closes.
The DKGF task: panning for what is relevant from the general
The authors formulate a new practical task — fusion of domain-specific knowledge graphs, or DKGF for short. The gist is simple in words: find in the general knowledge graph the facts that the target domain actually needs, and carefully integrate them there. The result is a domain graph that knows more but does not lose its specialization.
The title of the paper — "Panning for Gold" — is an apt metaphor. The general graph here is like a river with sand: there is gold in it, but it needs to be panned, not scooped up wholesale. The task is not to transfer the maximum, but to select what is needed.
Technical details of the work: arXiv:2601.10485, section cs.AI. The authors are Runhao Zhao, Weixin Zeng, Wentao Zhang, Chong Chen, Zhengpin Li, Xiang Zhao, and Lei Chen. The first version appeared on January 15, 2026, the latest, fifth, on August 25, 2026. Length — 13 pages, 5 figures. DOI: 10.48550/arXiv.2601.10485.
Two traps that trip up any attempt
Relevance: domain is a fuzzy concept
The first problem is the high ambiguity of domain relevance. Formally, the question sounds like this: does a particular fact from the general graph belong to our subject area? In practice, the answer is rarely obvious.
Take a medical graph. The fact "substance X affects process Y" may be relevant, or it may be a commonplace from school biology that will only add noise to the database. The boundaries of a domain are fuzzy, and a hard "ours/theirs" criterion simply does not exist. An error in one direction means losing useful knowledge, in the other — garbage in the graph.
Granularity: coarse versus fine
The second difficulty is a mismatch of granularity. Facts in general graphs are usually abstract and coarse-grained: they describe the world in broad categories. Domain graphs, by contrast, live in context — they need fine-grained statements tied to specific application scenarios.
A simple example: a general graph will say that a certain technology belongs to the class of data processing methods. For an industry graph this is almost useless — what matters there is under what conditions, with what constraints, and for what type of tasks the method is applicable. The fact cannot be transferred one-to-one; it needs to be reassembled to fit the target frame of reference.
ExeFuse: a fact as a program
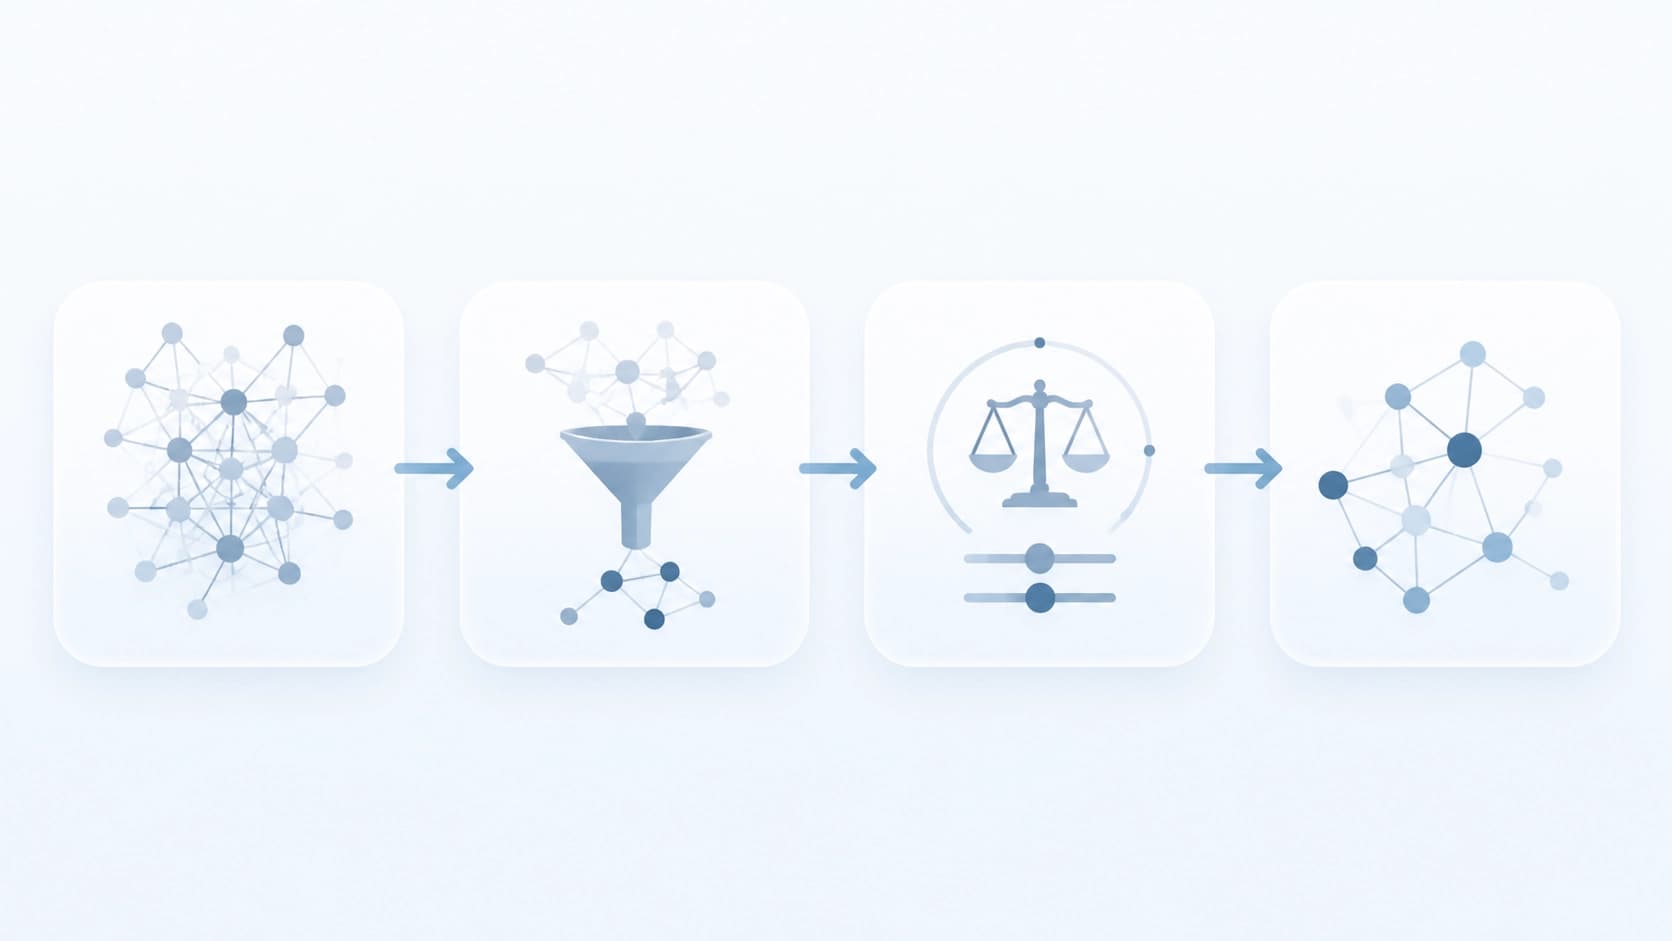
The authors' answer is the neuro-symbolic framework ExeFuse, built on the Fact-as-Program paradigm. The idea is to stop looking at graph fusion as moving ready-made statements from one database to another and start treating it as an executable process.
What does this change in practice? Neuro-symbolic execution makes it possible to verify logical relevance rather than superficial similarity. The difference is fundamental: a match of words or proximity of vector representations does not yet mean that the knowledge is applicable in the domain. Similar terms may describe different phenomena, and different formulations — the same thing. Logical verification looks at the structure of connections and at whether a statement is derivable in the context of the target area.
The second mechanism is target space grounding. It is what calibrates granularity: an abstract fact from the general graph is translated into the form that makes sense for a specific domain scenario. This is how the second of the described traps is removed.
The symbolic part is responsible for the rigor of inference, the neural network part — for handling the incompleteness and fuzziness of real data. The combination is what allows the framework to cross domain barriers where single methods give up.
Data and results
A separate contribution of the work is the datasets. The authors assembled the first standardized benchmark for evaluating the DKGF task. This matters no less than the method itself: without a common platform for comparison, the results of different approaches simply have nothing to be compared against, and the field remains a collection of scattered experiments.
What did the tests show? ExeFuse copes with domain barriers and demonstrates superior fusion performance. The specific metrics are a question for the paper itself; here it is enough to record the qualitative conclusion: the approach works, and does so better than the alternatives.
It is also worth noting the pace of work on the material. Five versions in seven months — from January to August 2026 — indicate that the research was actively refined: wording changed, experiments were expanded, the benchmark was clarified.
Where this will come in handy
The practical meaning of DKGF is broader than a single scientific task. Any industry that has a vetted knowledge graph and a desire to expand it gets a tool for carefully borrowing from general databases.
Medicine and pharmaceuticals are an obvious candidate: domain ontologies have long existed there, but the connections between them are lacking. The legal sphere, industrial safety, logistics, financial compliance — each has its own graphs, and each can be supplemented without rewriting them by hand.
The key here is not the volume of transferred facts, but their appropriateness. This is exactly what the "fact as a program" paradigm aims at: knowledge from the general graph is not copied but, as it were, executed in the coordinates of the target domain, passing verification for logical relevance and calibration by granularity.
If the direction takes hold, domain graphs will gain a third source of development — alongside extraction from texts and internal inference. And, possibly, the richest one.
Frequently asked questions
Related materials
All materials
Validating Candidates Costs More Than Generating Them: Honeypots Against LLM Vulnerability Hunting
The study examines the cost asymmetry in agentic vulnerability discovery: generating candidate versions is cheap, while confirming them through reachability analysis, execution, and PoC development consumes most of the budget, making verification a potential standalone target for defense. The proposed RedHerring—repository-adapted decoys with a hidden certificate—reduced the number of real vulnerabilities found by 38.7–60.4% at equal cost across 33 OSS-Fuzz projects; even after the agent was warned, the reduction remained at 37.2%.
9 November 2026
Checking LLM Hallucinations via SQL-Based Source Representation Without Fine-Tuning
The study examines whether an LLM can apply a basic symbolic skill—building a SQL database from source documents—to ground its outputs in sources without supervision when detecting hallucinations. On RAGTruth and DiaHalu, this neuro-symbolic pipeline proves more accurate than direct prediction and comparable to state-of-the-art methods, without requiring domain-specific fine-tuning.
9 November 2026
MathAdv: What the Final Accuracy of Machine-Generated Proofs Conceals
A diagnostic suite of tasks spanning 13 undergraduate and graduate mathematics topics evaluates machine-proving systems in Lean 4 not only by their final results, but also by their subject-matter mastery, the quality of their informal reasoning, and their robustness to rephrased conditions. A component-by-component analysis shows that translating a problem into formal form remains the main obstacle, and that success depends heavily on the area of mathematics and how the problem is framed.
9 November 2026