
Interpretation as Measurement: The MTI Mathematical Framework Describes Misunderstanding Through Entropy and Confusability
Blake Reynolds presented on arXiv a condensed core of the "Mathematical Theory of Interpretation": understanding here is not a property of the text, but the result of a spectral measurement that depends on the observer, their access, and the chosen method. The work introduces rational entropy as a measure of residual ambiguity and confusability, which turns from an obstacle into a design resource, as well as a four-condition certificate of reading quality with typed failures.
Interpretation usually lives in conversation as a binary label: "got it" or "didn't get it." Blake Reynolds' paper "A Mathematical Theory of Interpretation: Rational Entropy, Spectral Readout, and Confusability as a Resource" (arXiv:2608.23892, August 2026; the condensed core of a 2026 dissertation) proposes looking at this differently. Understanding here is not a state of mind but the result of a measurement that depends on the observer. And this measurement does not happen in a vacuum but within an access structure: some have a key to the data, some don't, and "got it" without specifying access loses its meaning.
The publication appeared in cs.IT with a cross-list to cs.AI — and that in itself is telling. The author moves the conversation about interpretation out of hermeneutics and into information theory, where there is entropy, channel capacity, and explicitly enumerated failure modes.
Four parameters instead of intuition
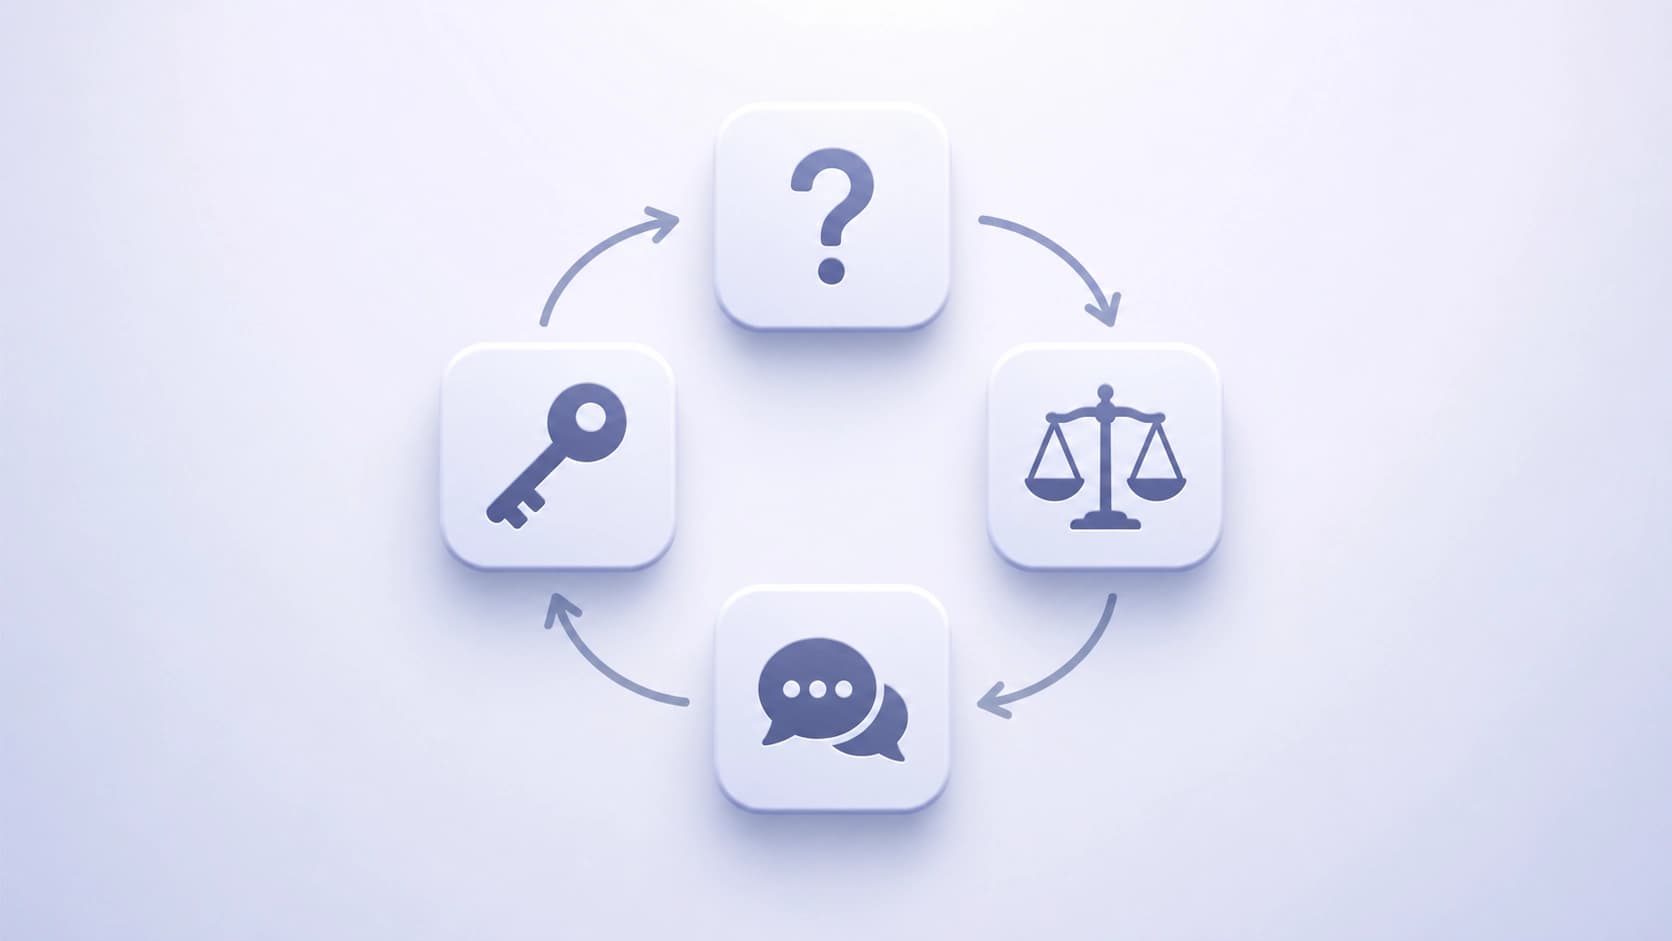
The central move of MTI is to turn interpretation into a method-design problem. Instead of asking "what does this signal mean," the theory asks what capabilities the observer has. There are four such capabilities, and they are set by the parameters access, query, utility, and medium:
- access — which data the observer is admitted to at all;
- query — which questions they are entitled to ask of the system;
- utility — what counts as a good answer for them;
- medium — in what environment the signal is distributed and stored.
What the observer can select, recognize, pass on, or, conversely, refuse to accept depends on this foursome. The practical conclusion here is rather stark: disputes about "correct interpretation" often turn out to be disputes about different sets of these four parameters. Two people can look at the same object and not disagree in logic — they simply have different access quotas and different queries.
Rational Entropy: how much non-understanding remains
The theory then moves to a measurable quantity. In the learning-invariant Hilbert implementation, Rational Entropy is introduced — it describes residual uncertainty along three axes at once: knowledge, utility, and medium. Put simply, it answers the question "how much is still unresolved," and not in general, but taking into account what the observer already knows and what they want.
An important detail: in the finitely effective regime, the authors classify the zero set of rational entropy. That is, the theory doesn't just introduce a measure but also describes when it goes to zero — which configurations of access, queries, and environment yield complete certainty. For engineering, this is the most interesting part: the zero set is a list of conditions under which non-understanding is constructively impossible.
Why this is not ordinary entropy
Classical entropy knows nothing about the observer's goals. Here utility enters the measure itself, which means two systems with identical signal statistics can have different rational entropy — if the observers have different tasks. This is inconvenient for those seeking a single universal metric of "understandability," but it describes reality more honestly.
Confusability as a resource, not a defect
The most counterintuitive result: pairwise confusability (when two states are indistinguishable) is equivalent to uniform atomic collapse. It sounds like a verdict, but then the twist begins. A single utility maximum can select one atom, even if all other states remain non-atomic at zero cost.
In other words, the usual role of confusability in coding theory is turned upside down. There, indistinguishability is a source of errors to be eliminated. Here it can work in the observer's favor: agreement along at least one direction rules out unresolved multi-atom readings, and a joint label preserves the object's identification. If two states "stick together" in one measurement but differ in another, the observer still holds the object as a whole.
How much free design can withstand
A quantitative estimate grows out of this logic. The capacity of free design equals the product of the budgets of all directions except the smallest. The formula is short, but with an unusual emphasis: the weakest direction does not enter the product. This is worth reading as a hint that the bottleneck in interpretation is structured differently from the bottleneck in a communication channel — there, it is precisely the worst segment that determines the outcome; here, the arithmetic is different.
A certificate of four conditions
So that the results don't remain purely theoretical, a four-condition certificate is introduced. It characterizes a reading as:
- sharp — crisp, without blurred boundaries;
- decodable — admitting decoding;
- medium-faithful — true to the medium, that is, not distorting the transmission environment;
- order-independent — not depending on the order of operations.
All of this is on a finite commuting sector of the code. If even one condition is violated, the theory returns not a general shrug but typed obstructions: specific indications of exactly which type of failure occurred. For practice, this is perhaps the main value of the work. Instead of "the model hallucinates," a vocabulary appears: here sharpness was lost, here the medium distorted the signal, and here the processing order broke identification.
Why this is needed beyond mathematics
MTI positions itself as a theoretical foundation for constructing interpretation methods with explicit assumptions about access, guarantees, and failure modes. Applied to AI systems, this is exactly what is often missing when evaluating models: not another "answer quality" metric, but a framework that forces one to state in advance who has what access, which queries are permitted, and what counts as useful. Then the conversation about non-understanding becomes reproducible.
What to keep in mind
This is a preprint: version v1, the condensed core of a dissertation, without a full peer-review cycle. The mathematical apparatus in the paper is dense, and any summary inevitably coarsens the formulations — for precise definitions of the Hilbert implementation and the commuting sector, it's better to go to the source.
But the main idea carries over into practice even without the details. Non-understanding ceases to be a property of a person or a model and becomes a measurable quantity depending on a configured arrangement of access, queries, goals, and environment. Confusability ceases to be merely a defect and sometimes works as a support. And the certificate of four conditions gives a language in which an interpretation failure can be called by its own name — instead of writing everything off as "they explained it poorly."
Frequently asked questions
Related materials
All materials
OpenCollab: programmable agent coordination, controlled execution environment, and policy compliance metric
The framework brings together the specification of agent interaction structures, a shared environment for experiments, and detailed event tracing, while the newly introduced Adherence metric reflects how closely actual execution follows the declared schema. In benchmarks, the Duo configuration achieves a new state of the art, while the single-agent variant uses the fewest tokens.
11 November 2026
Toollery: Choose tools for LLM agents from tens of thousands of options without fine-tuning
Toollery builds a search index from descriptions of skills and tools, then passes the model only a limited set of candidates for each query. In experiments with libraries containing tens of thousands of functions, the approach helps maintain selection quality at a fixed top-K, although the overall effect depends on the workload profile and the provider’s caching.
11 November 2026
WILSON: combining magnifications and patient slides for pathomorphological analysis and report generation
The preprint introduces WILSON, a vision-language model that encodes images of whole slides and series of slides from a single patient at different magnifications, rather than just a single “best” slide. Without task-specific fine-tuning, it outperforms specialized and larger slide models on a range of metrics while requiring substantially less compute, and its diagnostic descriptions received higher ratings from pathologists.
11 November 2026