Why a shared sketch fails for pages
Serving large language models on long context runs into the key-value (KV) cache. The cache is read in full at every decoding step. Attention keys are locally low-rank, though globally high-rank. A fixed low-rank sketch shared across pages is provably blind to page directions.
At the same summary size, a page's own basis ranks pages and preserves carriers far better. A shared sketch does not see these directions. A per-page spectral summary solves the problem.
Per-page spectral summary
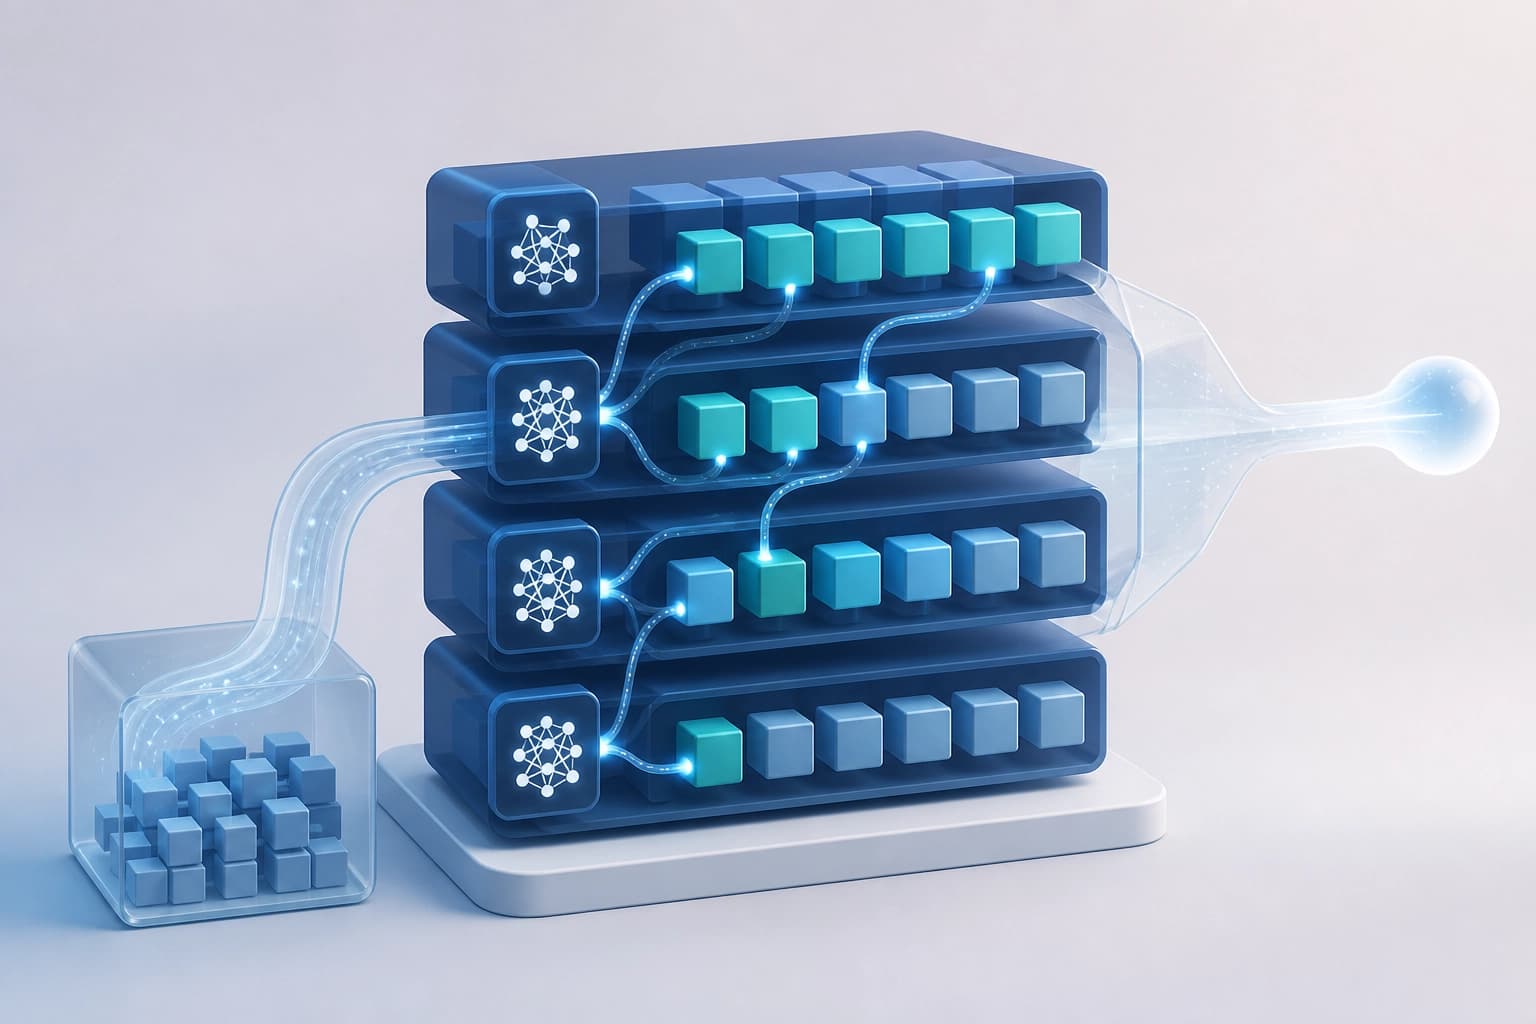
LOCKS gives each page its own rank-r spectral summary. The summary is resident: one tenth of the cache at r=8 and one twenty-fifth at r=2. The method reconstructs intra-page logits. It estimates each page's attention mass via log-sum-exp. Then it processes only the top pages.
Key elements:
- Name: Page-Local Compact Key Summaries for Efficient Long-Context Decoding.
- Summary: rank-r spectral summary for each page.
- Residency: one tenth of the cache at r=8, one twenty-fifth at r=2.
- Reconstruction: intra-page logits.
- Estimation: page attention mass via log-sum-exp.
- Selection: only the top pages.
Takeaway: the summary takes a fraction of the cache but preserves page features. Page selection is driven by spectral data.
Block selection without reading keys
The selection itself does not read candidate keys or values. The choice is made solely from the spectral summary. The summary is scanned in full at every step. KV reads per step drop by 10–25× within the stated rank range.
Decoding latency per token is halved. At 1M tokens on a single H200 NVL, the speedup is 2.0× at r=8. This is a comparison with dense attention. Selection does not depend on reading candidate keys.
Quality on long tasks
LOCKS preserves quality on several task types. On long-document QA (LongBench-v1; Llama-3.1-8B), the result stays within one point of the full cache. On retrieval-dense RULER, the method follows the exact LSE oracle that reads every key, down to the smallest budgets. On long-form reasoning (AIME26, MATH-500; Qwen3-4B), quality holds up longer than all others in the low-budget regime. Eviction-based reasoning selectors and compressors fall behind there.
At a 2048-token budget, LOCKS matches the aggregate FullKV quality on 100K+ context (GLM-4-9B-Chat-1M). At the same time, the method processes 2% of tokens.
| Condition | Result |
|---|---|
| Long-document QA (LongBench-v1; Llama-3.1-8B) | within one point of the full cache |
| Retrieval-dense RULER | follows the exact LSE oracle down to small budgets |
| Long-form reasoning (AIME26, MATH-500; Qwen3-4B) | holds quality longer than all others at small budgets |
| 2048-token budget, 100K+ context (GLM-4-9B-Chat-1M) | matches FullKV, processes 2% of tokens |
Takeaway: on the listed tasks, the approach preserves quality longer than selectors and eviction-based compressors.
Deployment and selection criteria
The approach ships as a drop-in plugin for unmodified vLLM. Batched decoding runs in full CUDA graphs. No modification of vLLM is required.
Selection criteria: long context, limited token budget, the need to reduce KV reads and decoding latency. If the task requires block selection without reading candidate keys, the approach fits.