
The CHOIR Method: Free-Form Listing Reveals Divergent Model Positions Within Collective Systems
The authors propose CHOIR, an approach in which ensembles repeatedly request ranked lists of answers and then compare the salience of merged concepts across models, prompt phrasings, and role conditions. The study shows that high surface similarity among open-ended answers does not necessarily indicate consensus: base-model identity remains the most stable distinguishing factor, while persona settings shift the concepts expressed.
What CHOIR offers
CHOIR stands for Collective Hierarchically-Ordered Inquiry Responses. The approach adapts free-list elicitation for LLM ensembles. Its goal is to uncover the positions where models within an ensemble diverge. The surface-level agreement between responses hides these differences.
The method works with lists, rather than ready-made formulations. Repeated prompts provide material about which topics the models raise on their own. This material is then brought into a comparable form.
Practical criterion: use CHOIR when ensemble responses look alike but you need to understand exactly where the models differ.
Method workflow
The method consists of three steps.
- Repeatedly request ranked lists from ensemble models.
- Combine list items into concepts at the prompt level.
- Measure the salience of concepts across models, prompt variants, and persona conditions.
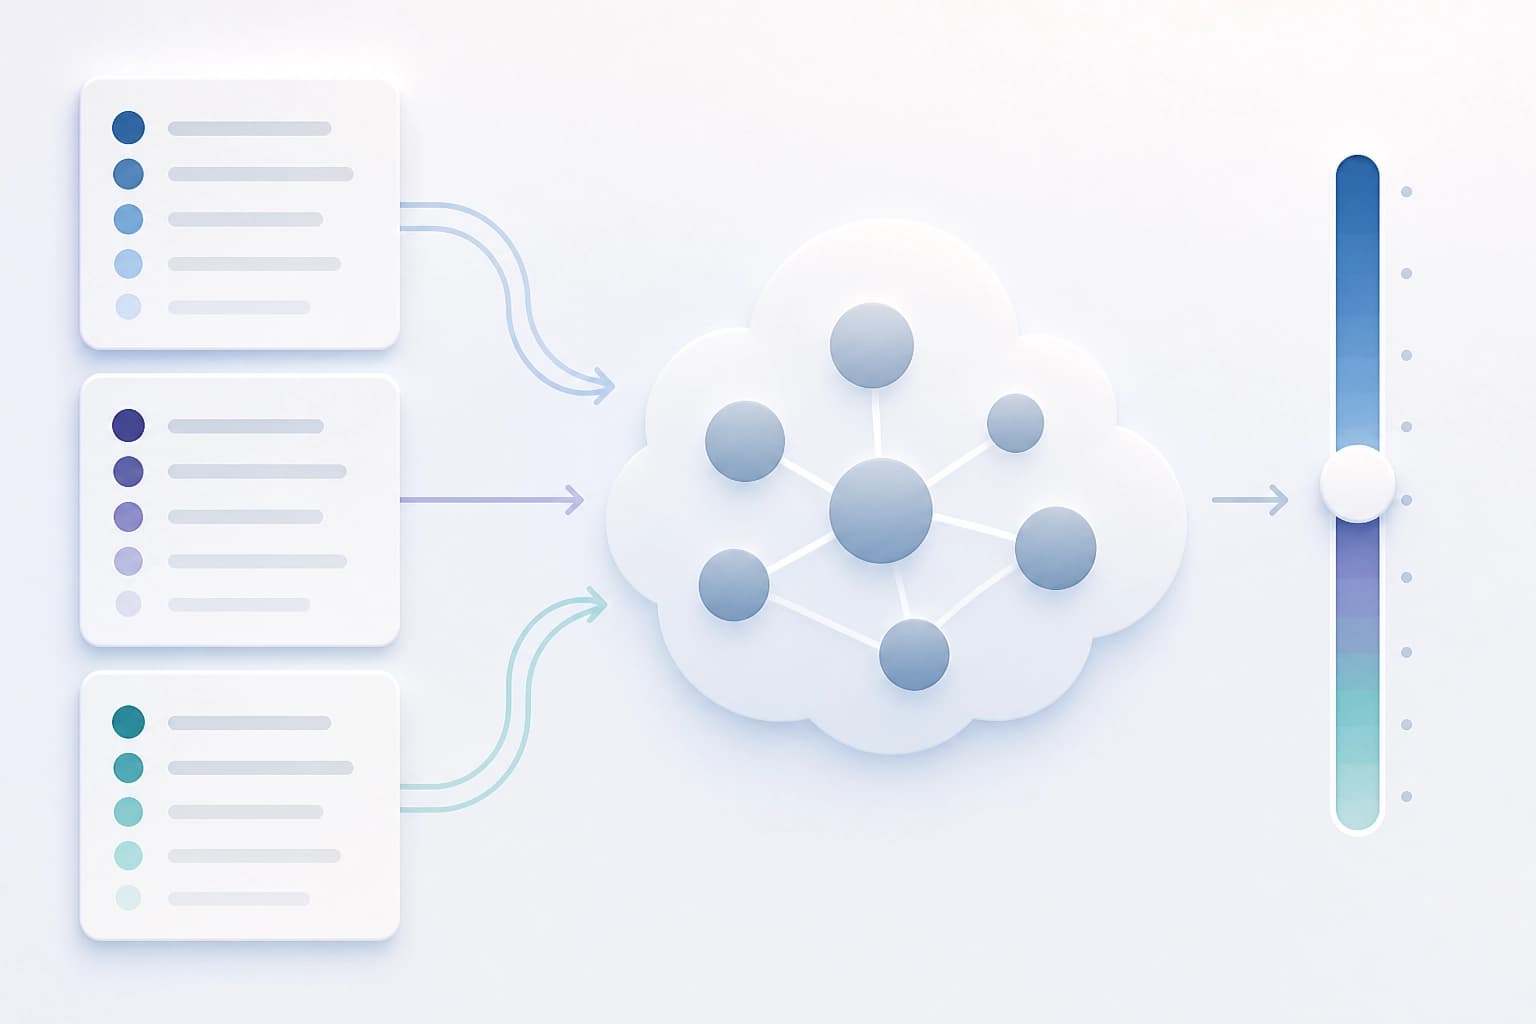
Each step adds a dimension. Lists provide raw material, combining them makes it comparable, and measuring salience reveals differences. Without mapping items to concepts, comparison remains at the level of individual words.
Practical criterion: evaluate the method by whether it preserves differences after combining items into concepts.
Evaluation datasets
| Dataset | What it is | What it showed |
|---|---|---|
| Infinity-Chat 100 | An external prompt set from a recent study on the homogeneity of open-ended model responses | Reproduces high surface-level agreement: 93/100 prompts are above chance. Distinguishes narrow prompts from broad ones, which reveal hidden response depth |
| Targeted diagnostic set | 27 questions designed to reveal differences at the mechanism level | Serves for targeted checks of divergences between models |
The datasets serve different purposes. The external set shows the overall picture of agreement while also distinguishing broad prompts from narrow ones. The targeted set is designed to identify differences at the mechanism level.
Selection criterion: use the external prompt set for an overview of agreement, and the diagnostic set to analyze mechanisms.
What differences can be identified
The findings fall into three groups.
- Base-model identity remains the strongest recoverable signal. This holds for both targeted checks and the external prompt set.
- Persona prompts shift the concepts expressed within base-model signatures.
- A source-blind ranking module identifies rare but stable candidates for further study.
Personas change how concepts are expressed, but do not override the base-model signal. Source-blind ranking works as a filter for further analysis.
Practical criterion: establish the base model first, then assess the shift caused by the persona.
A diagnostic framework instead of a statement of agreement
The authors propose treating the homogeneity of open-ended responses as a diagnostic task. The question then takes a different form: where do models converge, why do they converge, and what else can be uncovered?
- Where they converge — a map of shared concepts across models.
- Why they converge — the reasons behind surface-level agreement.
- What else is visible — candidates identified by source-blind ranking.
The paper was published in Proceedings of the Third Conference on Language Modeling (COLM 2026), 2026. It was submitted to arXiv on September 29, 2026. The authors are Ben Wigler and Maria Tsfasman.
Criterion: response homogeneity is not a final conclusion, but a starting point for diagnosing depth.
Frequently asked questions
Related materials
All materials
AURA-Eval: How to Check Whether an LLM Agent Recognized a Risk and Changed Its Next Step
The framework evaluates LLM agents’ behavior not by their final verdict, but by how they respond to risk at key decision points: tool-call trajectories are interrupted, after which the model must continue reasoning and acting, while a panel of LLM judges assesses risk detection, the nature of the step, and its safety. Across 1,249 tasks drawn from 157 R-Judge trajectories, unsafe actions become more frequent among 20 models when no safe path is available, and removing oversight before execution turns 52.3% of initially safe cases into unsafe ones.
10 November 2026
Chern–Simons Reservoir Memory: Autonomous Connectivity Dynamics and Density Transport
The article explores how a reservoir preserves the history of input signals both in its density distribution and in its geometric degrees of freedom. A comparison of four mechanisms shows that current creates a separate connected component that alters the subsequent density response, while accounting for all measured features yields a small improvement in decoding pulse order.
10 November 2026
STAR: Adaptive Normalization of Temporal Context and Service Graphs for End-to-End Incident Management
The STAR framework trains representations from metrics, logs, and traces, using learnable normalization that accounts for multiscale temporal dynamics and dependency structures between services. On two real-world datasets, this pipeline delivers consistent improvements in anomaly detection, failure ranking, and root cause analysis over state-of-the-art baselines.
10 November 2026